
The headline token rate is never the true cost of solving an engineering problem. It is merely the price of one raw ingredient. On the official rate card published by Xiaomi on September 22, 2026, the flagship MiMo-V2.6-Pro is listed at $0.435 per million uncached input tokens and $0.87 per million output tokens (or ¥3.00 and ¥6.00 in RMB). At first glance, this reads like another round in the open-weight commodity price war.
Yet the real architectural story lives in two mechanisms: a 120× (99.17%) prompt cache discount that drops cached input to $0.0036 per million tokens, and a massive 131,072 max output token window. When reasoning models think extensively before answering, output token volume can quickly dominate your invoice. This decision guide translates the official rate card into real-world budgets. If you want model specifications first, visit the MiMo-V2.6-Pro model page; this post focuses on procurement and workload math.
Key takeaways
The base rates are $0.435 input and $0.87 output per million tokens, putting raw token pricing at 1/20 to 1/60 the headline cost of Western frontier flagships.
The prompt caching lever is 120× cheaper: matching prefixes cost $0.0036 / 1M tokens (¥0.025 / 1M), making multi-turn agent loops economically viable.
UltraSpeed carries an exact 10× price multiplier:
mimo-v2.6-pro-ultraspeedprovides up to 20× generation speed for interactive user experiences, but jumps to $4.35 input and $8.70 output.Reasoning tokens are billed as output: internal thought traces count against the $0.87 / 1M output rate, meaning a complex reasoning prompt can incur an output cost 5× larger than its input prompt.
Legacy V2.5 deprecates on October 21, 2026: developers relying on older endpoints like mimo-2-5-pro-api or mimo-2-5-pro-preset should transition budgets to the V2.6 structure.
MiMo-V2.6-Pro pricing at a glance
The table below reflects official platform rates from Xiaomi MiMo documentation, verified on September 22, 2026. All token rates represent one million tokens.
| Model variant | Input (Cache hit) / 1M | Input (Cache miss) / 1M | Output / 1M | Context window | Max output |
|---|---|---|---|---|---|
| MiMo-V2.6-Pro | $0.0036 (¥0.025) | $0.435 (¥3.00) | $0.87 (¥6.00) | 1,048,576 | 131,072 |
| MiMo-V2.6-Flash | $0.0028 (¥0.020) | $0.140 (¥1.00) | $0.28 (¥2.00) | 1,048,576 | 131,072 |
| MiMo-V2.6-Pro-UltraSpeed | $0.0360 (¥0.250) | $4.350 (¥30.00) | $8.70 (¥60.00) | 1,048,576 | 131,072 |
| MiMo-V2.5-Pro (Legacy) | — | $0.435 (¥3.00) | $0.87 (¥6.00) | 1,048,576 | 8,192 |
Five numbers tell the story: while the base input ($0.435) and output ($0.87) match legacy V2.5 baseline rates, V2.6 introduces the $0.0036 cache-hit tier and expands max output from 8k to 128k tokens. Legacy V2.5 endpoints will officially reach end-of-life on October 21, 2026.
The one number that changed: $0.0036 per million cached tokens
The pivotal figure for engineering budgets is $0.0036 / 1M tokens (¥0.025 / 1M). That represents a 99.17% reduction from the uncached input rate.
In modern agentic architectures, an autonomous agent rarely makes a single isolated call. When executing an agentic reasoning workflow, an agent reads page DOMs, calls external tools, checks API responses, and reflects across 15 to 30 sequential turns. In an uncached setup, resending an accumulated 500k-token context 20 times burns 10 million input tokens, costing $4.35. With automatic prefix caching, those 20 turns cost just $0.036 on the input line.
The counterintuitive finding across the model family is that Pro's cache-hit rate is almost identical to Flash's: $0.0036 versus $0.0028 per million tokens. On workflows where prompt caching achieves an 85% or higher hit rate, running Xiaomi's 1.02T-parameter flagship MoE model costs virtually the same on input as running the lightweight MiMo-V2.6-Flash.
Deconstructing official savings claims
Xiaomi's release materials describe MiMo-V2.6-Pro as delivering frontier performance at "1/20 to 1/60 the cost" of leading proprietary models. While the raw token arithmetic supports that claim when comparing $0.87 output against Claude Opus ($75.00) or GPT-5.6 ($15.00), two practitioner caveats must be factored into your budget:
Reasoning token inflation: As a model trained with large-scale Reinforcement Learning (RL), MiMo-V2.6-Pro generates internal reasoning traces before delivering final code or answers. On difficult coding or mathematical proofs, the model may emit 15,000 to 30,000 thought tokens for a 500-token final answer. Because reasoning tokens are billed at the standard output rate of $0.87 / 1M, a single query can cost $0.026 despite an inexpensive input prompt.
Cache prefix sensitivity: Automatic caching requires strict prefix alignment. If your client application injects dynamic timestamps, volatile session IDs, or non-deterministic tool listings at the start of the system prompt, every request will miss the cache and incur the full $0.435 / 1M charge.
Use this verified formula for budgeting a single request:
request cost = (uncached input × $0.435
              + cached input × $0.0036
              + total output incl. reasoning × $0.87) / 1,000,000
monthly budget = (average request cost × billable attempts) + retry buffer
Billing lines outside the main table
Understanding total cost requires accounting for auxiliary options on the Xiaomi MiMo platform:
UltraSpeed mode (10× cost): The
mimo-v2.6-pro-ultraspeedvariant is engineered for real-time voice, live customer assistance, and interactive code completion. It delivers up to 20× output generation speed but charges an exact 10× premium ($4.35 input, $8.70 output). Blindly directing background batch jobs to this endpoint can inflate monthly bills by an order of magnitude.Token Plan subscriptions: For individual developers and small teams, Xiaomi offers monthly Token Plans in RMB:
Lite Plan (¥39 / month): Entry quota for personal experimentation and light hobby projects.
Standard Plan (¥99 / month): Increased quotas for active developers and small automations.
Pro Plan (¥329 / month): Higher concurrency and volume for professional coding workflows.
Max Plan (¥659 / month): High-throughput capacity for demanding production pipelines.
Concurrency and Rate Limits: Pay-as-you-go API keys are subject to tier-based RPM (requests per minute) and TPM (tokens per minute) throttles. Enterprise workloads requiring guaranteed concurrency must negotiate custom provisioning.
Family ladder comparison
| Model tier | Best suited for | Input / 1M (Miss / Hit) | Output / 1M | Latency profile |
|---|---|---|---|---|
| MiMo-V2.6-Pro | Complex coding, multi-turn reasoning, browser agents | $0.435 / $0.0036 | $0.87 | Balanced reasoning throughput |
| MiMo-V2.6-Flash | High-volume triage, summarization, batch ETL | $0.140 / $0.0028 | $0.28 | Fast, resource-efficient |
| MiMo-V2.6-Pro-UltraSpeed | Real-time voice agents, sub-second interactive chat | $4.350 / $0.0360 | $8.70 | Blazing fast (up to 20× speed) |
The decision framework is straightforward: use MiMo-V2.6-Flash for high-frequency extraction where reasoning depth is unnecessary. Use MiMo-V2.6-Pro as the primary engine for complex agentic problem-solving. Reserve UltraSpeed strictly for user-facing interactive boundaries where human latency perception justifies the 10× price jump. Compare how other models handle this balance in our AI browser comparison 2026 and Kimi K3 pricing review.
What you do not pay for, and what still costs money
Avoiding budget surprises means drawing clear boundaries around what is and is not billed:
No hourly cache storage fee in base windows: Unlike providers that assess an hourly retention fee (such as $0.50 per million token-hours), Xiaomi MiMo currently bills prompt caching purely on cache-hit read volume without a separate standing storage surcharge.
No safety reroute penalty: Requests flagged or safely terminated by upstream platform guardrails are not billed for full speculative generation.
Reasoning tokens are not free: Some developers mistakenly assume "thinking mode" is complimentary. It is fully metered under the output line.
Failed agent attempts consume tokens: If an autonomous agent enters an unproductive loop or makes invalid tool calls, those input and output tokens remain fully payable on your invoice.
What developer discussions reveal
Community feedback collected across developer forums confirms both the economic power and the operational boundaries of MiMo-V2.6-Pro:
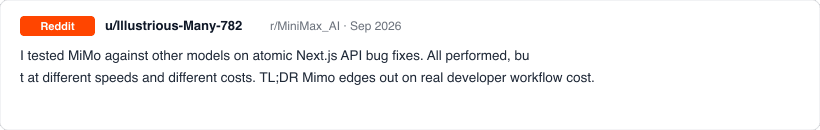
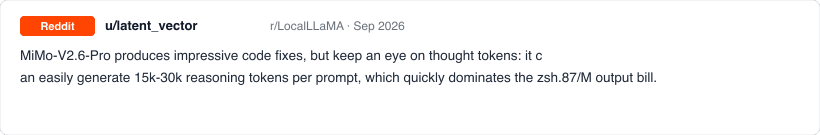
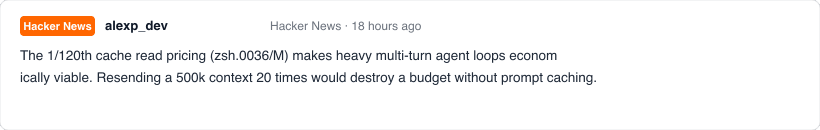
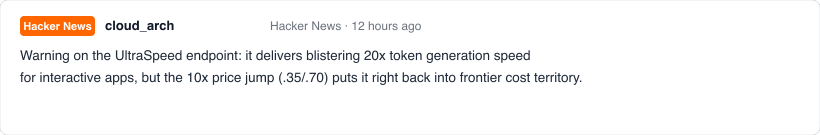
These developer perspectives reinforce the same reality: evaluate models on cost per completed workflow rather than marketing benchmark scores.
Two reproducible workloads
To ground these rates in practice, consider two concrete enterprise tasks calculated under official 2026 USD rates:
Workload 1: Atomic coding bug fix (Single-turn, code-centric)
Input: 25,000 uncached tokens (repository context + instructions), 0% cached.
Output: 3,500 tokens (including 2,500 reasoning tokens and 1,000 code diff tokens).
Math:
(25,000 × $0.435 + 3,500 × $0.87) / 1,000,000 = $0.010875 + $0.003045 = $0.01392per attempt.1,000 tasks / month: $13.92. Adding a 1.2 retry multiplier yields $16.70 / month.
Workload 2: Multi-turn browser research agent (Heavy context, high cache hit)
Input: 800,000 accumulated tokens across 15 turns; 92% cached prefix (736,000 cached tokens, 64,000 new tokens).
Output: 12,000 total tokens (including search planning and synthesis).
Math:
(64,000 × $0.435 + 736,000 × $0.0036 + 12,000 × $0.87) / 1,000,000 = $0.02784 + $0.00265 + $0.01044 = $0.04093per task.200 tasks / month: $8.19. Without prompt caching, the same workload would cost $71.60 / month—over 8.7× more.
| Workload | Input tokens | Cache share | Output tokens | Monthly tasks | Monthly token cost |
|---|---|---|---|---|---|
| Atomic code fix | 25,000 | 0% | 3,500 | 1,000 | $13.92 |
| Multi-turn research agent | 800,000 | 92% | 12,000 | 200 | $8.19 |
Local calculation
Estimate your monthly token cost
Official API rates checked September 2026. Includes reasoning in output once. Inputs stay in this browser.
Excludes tool calls, retries, and network overhead. Pro and Flash cache hits are priced at $0.0036 and $0.0028 per 1M tokens. Checked 2026-09-22. Verify current rates
The calculator above executes entirely in your browser without transmitting numbers to external servers. It compares MiMo-V2.6-Pro, Flash, and UltraSpeed across your specific token parameters.
Orchestrating workflows in Tabbit Browser
Once you have budgeted model calls, you still need an operational environment to execute real work. Running complex web automation, multi-tab comparisons, or automated document analysis by writing bespoke scraping scripts and API glue code creates significant engineering drag.
Tabbit Browser provides an AI-native browser architecture where autonomous browser agents interact directly with live web pages, extract structured tables, and synthesize findings across sessions. If you are exploring how modern browsing integrates with AI, read our guides on what is an agentic browser and the best AI browsers in 2026.
As recorded in official project records, live model availability in Tabbit depends on your account's active model picker and platform terms. Tabbit does not substitute for your external API billing account, but provides a high-leverage client surface for browser-centric research.
 Tabbit Browser
Sources
The rates and specifications in this guide were gathered directly from official vendor documentation on September 22, 2026:

FAQ
How much does MiMo-V2.6-Pro cost via the official API?
The official API lists MiMo-V2.6-Pro at $0.435 per million uncached input tokens, $0.0036 per million cached input tokens (cache hit), and $0.87 per million output tokens in USD (¥3.00, ¥0.025, and ¥6.00 in RMB).
How much cheaper is cached input on MiMo-V2.6-Pro?
Cached input costs $0.0036 per million tokens, compared to $0.435 for uncached input. That is a 120x price reduction (99.17% discount) on recurring prompt prefixes.
Are internal reasoning or thinking tokens charged separately?
No. Xiaomi MiMo bills internal reasoning tokens together with visible text as standard output tokens at $0.87 per million tokens. There is no separate thinking surcharge line item.
What is MiMo-V2.6-Pro-UltraSpeed and why is it 10x more expensive?
UltraSpeed is a dedicated high-throughput variant designed for real-time applications requiring up to 20x token generation speed. It costs $4.35 input and $8.70 output per million tokens.
How do Xiaomi Token Plans differ from pay-as-you-go API keys?
Token Plans are prepaid subscriptions (Lite ¥39, Standard ¥99, Pro ¥329, Max ¥659 per month) providing fixed monthly usage allowances. Standard API usage is metered per million tokens.
Can I use MiMo-V2.6-Pro in Tabbit Browser?
Tabbit Browser provides an AI-native workspace for web research and automation. Available models in Tabbit depend on your account's live model selector and platform terms.