
The nominal token rate is never the complete cost of solving an engineering problem. It is simply the price of one raw ingredient. On the official rate card published by Xiaomi on September 22, 2026, the efficiency-focused MiMo-V2.6-Flash is listed at $0.140 per million uncached input tokens and $0.280 per million output tokens (or ¥1.00 and ¥2.00 in RMB). At more than 3× cheaper than its flagship sibling, this positions Flash as one of the most aggressive lightweight omnimodal models in the developer market.
Yet the real architectural story centers on two mechanisms: a 50× (98.0%) prompt cache discount that lowers cached input to $0.0028 per million tokens, and a sparse Mixture-of-Experts (MoE) design activating just 15B parameters out of 309B total to sustain rapid generation (over 140 tokens per second). When processing high-throughput batch extraction or high-frequency browser agents, these rates shift the economics of scale. This decision guide translates the official rate card into reproducible enterprise budgets. If you need model specifications first, visit the MiMo-V2.6-Flash model page; for the 1.02T flagship tier, see our MiMo-V2.6-Pro pricing analysis.
Key takeaways
The base rates are $0.14 input and $0.28 output per million tokens, making Flash more than 3× cheaper on both axes than the flagship MiMo-V2.6-Pro ($0.435 / $0.87).
Prompt caching drops input costs by 98.0%: matching prefixes cost just $0.0028 / 1M tokens (¥0.02 / 1M), allowing long system prompts and reference context to be queried repeatedly for pennies.
UltraSpeed is exclusive to Pro: Flash has no separate 10× UltraSpeed tier because its 15B activated parameters already deliver native low latency and high streaming throughput.
Reasoning tokens are billed as output: in RL reasoning checkpoints, internal thought chains are metered under the $0.28 / 1M output line, so unconstrained reasoning loops can expand invoice volume.
The counterintuitive cache parity: in agent loops with >85% cache hit rates, Pro's cache read cost ($0.0036) is only $0.0008 away from Flash ($0.0028), making output token volume the true cost driver between tiers.
MiMo-V2.6-Flash pricing at a glance
The table below reflects official platform rates from Xiaomi MiMo documentation, verified on September 22, 2026. All token rates represent one million tokens.
| Model variant | Input (Cache hit) / 1M | Input (Cache miss) / 1M | Output / 1M | Context window | Max output |
|---|---|---|---|---|---|
| MiMo-V2.6-Flash | $0.0028 (¥0.02) | $0.140 (¥1.00) | $0.280 (¥2.00) | 1,048,576 | 131,072 |
| MiMo-V2.6-Pro | $0.0036 (¥0.025) | $0.435 (¥3.00) | $0.870 (¥6.00) | 1,048,576 | 131,072 |
| DeepSeek V4.1 Flash | $0.0030 (¥0.021) | $0.150 (¥1.05) | $0.300 (¥2.10) | 1,048,576 | 8,192 |
| Gemini 3.8 Flash | $0.0375 | $0.150 | $0.600 | 1,048,576 | 8,192 |
The baseline rate card reveals an unmistakable strategy: MiMo-V2.6-Flash directly challenges competitive lightweight endpoints like DeepSeek V4.1 Flash and Gemini 3.8 Flash while extending output capacity up to 131,072 tokens within a full 1M-token context window.
The one number that changed: $0.0028 per million cached tokens
The critical figure for infrastructure budgeting is $0.0028 / 1M tokens (¥0.02 / 1M). That represents an exact 98.0% reduction (50× discount) from the uncached input rate of $0.140.
In automated web workflows, such as an agentic reasoning workflow, an autonomous agent frequently inspects DOM snapshots, executes multi-stage data extractions, and evaluates structured forms. If a 100,000-token repository context or web crawl payload is re-submitted across 20 turns without caching, you consume 2 million input tokens ($0.28). With automated prefix caching, those same 20 turns cost less than $0.006 on the input line.
Furthermore, Flash's sparse MoE architecture activates only 15B parameters out of 309B total. This keeps time-to-first-token (TTFT) low and generation speed above 140 tokens per second, ensuring that high-volume scraping and real-time triage do not bottleneck behind compute queues.
Deconstructing official efficiency claims
Xiaomi presents MiMo-V2.6-Flash as the ideal engine for high-volume enterprise pipelines where frontier reasoning quality must be balanced against strict unit economics. While the raw token math is compelling, two practical operational boundaries must be factored into production planning:
Reasoning token metering in RL mode: The
MiMo-V2.6-Flash-RLcheckpoint employs reinforcement learning to evaluate intermediate steps. Even though Flash output is inexpensive at $0.28 / 1M, complex multi-step instructions can emit 3,000 to 6,000 internal thinking tokens before yielding a 200-token structured JSON answer. Because thinking tokens are billed as output, a query's compute cost is determined by reasoning depth rather than prompt size.Prefix cache stability: To qualify for the $0.0028 rate, prompt prefixes must remain stable across calls. Injecting dynamic timestamps, random request IDs, or variable user headers at the very start of your prompt will invalidate the cache and force the full $0.140 / 1M uncached fee.
Use this verified formula to calculate request costs:
single request cost = (uncached input × $0.140
                     + cached input × $0.0028
                     + total output incl. reasoning × $0.280) / 1,000,000
monthly budget = (average request cost × billable tasks) + retry buffer
Billing lines outside the main table
Calculating total cost of ownership requires noting auxiliary platform rules on the Xiaomi MiMo API:
UltraSpeed exclusivity: Unlike the flagship tier which offers a 10× priced
mimo-v2.6-pro-ultraspeedvariant ($4.35 input, $8.70 output), Flash does not offer or require an UltraSpeed mode. Its 15B active parameter footprint inherently provides ultra-fast streaming without paying a pricing multiple.Token Plan subscriptions: For small teams and individual practitioners, Xiaomi provides fixed-tier monthly Token Plans denominated in RMB:
Lite Plan (¥39 / month): Low-volume quota for testing and personal automation scripts.
Standard Plan (¥99 / month): Scaled allowance for active developers and daily scraping jobs.
Pro Plan (¥329 / month): Higher concurrency and token allocations for production pipelines.
Max Plan (¥659 / month): Dedicated capacity for enterprise-scale ingestion.
Rate limits and concurrency: Unmetered pay-as-you-go API keys are bounded by platform RPM (requests per minute) and TPM (tokens per minute) thresholds. Teams operating parallel crawler fleets should request enterprise quota uplifts.
Legacy endpoint deprecation: The earlier MiMo-V2.5 generation will officially reach end-of-life on October 21, 2026. Existing pipelines should migrate to V2.6 endpoints immediately.
Family ladder comparison
| Model tier | Best suited for | Input / 1M (Miss / Hit) | Output / 1M | Concurrency & latency profile |
|---|---|---|---|---|
| MiMo-V2.6-Flash | Bulk web extraction, high-frequency triage, summarization | $0.140 / $0.0028 | $0.280 | High throughput (140+ tok/s), 15B active MoE |
| MiMo-V2.6-Pro | Complex coding, multi-step math, deep architectural reasoning | $0.435 / $0.0036 | $0.870 | Deep reasoning, 42B active / 1.02T total MoE |
| MiMo-V2.6-Pro-UltraSpeed | Real-time voice agents, sub-second interactive customer chat | $4.350 / $0.0360 | $8.700 | Blazing fast generation (up to 20× speed, 10× cost) |
The counterintuitive finding in this ladder lies in the caching dynamics: in uncached single-turn tasks, Flash is 3.1× cheaper than Pro. However, in an iterative agent loop where prompt caching achieves a 90% hit rate, the input cost difference between Flash ($0.0028) and Pro ($0.0036) is just $0.0008 per million tokens. In that regime, the choice between Flash and Pro is dictated almost entirely by the output rate ($0.28 vs $0.87) and whether the task demands 1.02T reasoning depth. Review how other frontier options stack up in our AI browser comparison 2026.
What you do not pay for, and what still costs money
Drawing precise architectural boundaries prevents unexpected monthly billing surprises:
No hourly cache retention surcharge: Unlike cloud providers that bill an hourly standing storage fee (e.g. $0.50 per million token-hours for stored context), Xiaomi MiMo currently charges for prompt caching purely on read hits without an hourly idle penalty.
No upstream safety cutoff fees: Requests terminated early by platform guardrails or policy violations are not charged for speculative downstream completion tokens.
Reasoning tokens are not free: Internal thinking steps are metered under standard output tokens at $0.28 / 1M.
Orchestration failures consume budget: If your crawler encounters CAPTCHAs, malformed HTML, or repetitive retry loops, all generated input and output tokens remain billable.
What developer discussions reveal
Community feedback gathered from developer channels highlights how engineers deploy MiMo-V2.6-Flash in production:
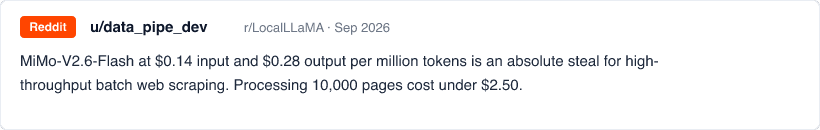
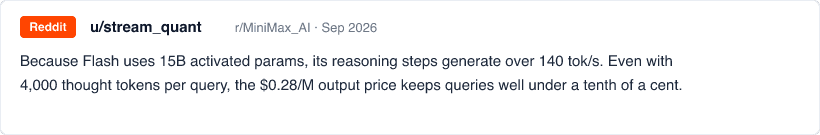
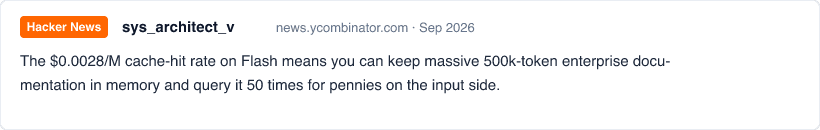
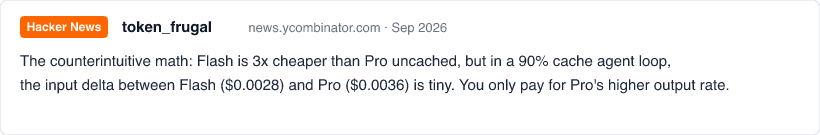
These developer insights converge on a single rule: rely on Flash for high-frequency extraction and triage, and escalate to Pro only when complex reasoning is strictly required.
Two reproducible workloads
To ground these rates in practice, consider two concrete enterprise tasks calculated under official 2026 USD rates:
Workload 1: High-throughput batch web page extraction (Volume-driven, low cache)
Input: 15,000 tokens per page (HTML content + extraction schema); 25% cached prefix (3,750 cached tokens, 11,250 uncached tokens).
Output: 800 tokens (structured JSON record).
Math:
(11,250 × $0.140 + 3,750 × $0.0028 + 800 × $0.280) / 1,000,000 = $0.001575 + $0.0000105 + $0.000224 = $0.00181per page.10,000 pages / month: $18.10 / month. (Running the same workload on MiMo-V2.6-Pro would cost $55.97 / month—Flash saves 68%!).
Workload 2: Multi-turn document research & comparison agent (High cache hit)
Input: 300,000 accumulated tokens across 10 tool turns; 85% cached prefix (255,000 cached tokens, 45,000 new tokens).
Output: 5,000 total tokens (planning, filtering, and final summary).
Math:
(45,000 × $0.140 + 255,000 × $0.0028 + 5,000 × $0.280) / 1,000,000 = $0.00630 + $0.000714 + $0.00140 = $0.00841per task.500 tasks / month: $4.21 / month. Without prompt caching, input tokens alone would cost $0.042 per run, lifting total monthly expense to $21.70 / month—over 5× higher.
| Workload | Input tokens | Cache share | Output tokens | Monthly tasks | Monthly token cost |
|---|---|---|---|---|---|
| High-volume page extraction | 15,000 | 25% | 800 | 10,000 | $18.10 |
| Multi-turn research agent | 300,000 | 85% | 5,000 | 500 | $4.21 |
Local calculation
Estimate your monthly token cost
Official API rates checked September 2026. Includes reasoning in output once. Inputs stay in this browser.
Excludes tool calls, retries, and network overhead. Pro and Flash cache hits are priced at $0.0036 and $0.0028 per 1M tokens. Checked 2026-09-22. Verify current rates
The calculator above executes locally in your browser without transmitting numbers to external servers. It compares MiMo-V2.6-Flash, Pro, and UltraSpeed across your custom token inputs.
Orchestrating workflows in Tabbit Browser
Budgeting model tokens is only half the engineering challenge. You still need an orchestration environment to execute workflows across real websites. Manually writing headless scripts, maintaining browser sessions, and handling pagination introduces heavy maintenance friction.
Tabbit Browser offers an AI-native browser workspace where intelligent browser agents navigate multi-page applications, extract clean tabular data, and synthesize findings across live tabs. To understand how agentic architectures transform daily workflows, explore our guides on what is an agentic browser and the best AI browsers in 2026.
Per official project documentation, live model availability in Tabbit depends on your account's active model picker and platform terms. Tabbit does not replace your external API subscription, but provides a high-leverage client surface for automated web tasks.
 Tabbit Browser
Sources
The rates and specifications in this guide were gathered directly from official vendor documentation on September 22, 2026:

FAQ
How much does MiMo-V2.6-Flash cost via the official API?
The official API lists MiMo-V2.6-Flash at $0.140 per million uncached input tokens, $0.0028 per million cached input tokens (cache hit), and $0.280 per million output tokens in USD (¥1.00, ¥0.02, and ¥2.00 in RMB).
How much cheaper is cached input on MiMo-V2.6-Flash?
Prompt cache hits cost $0.0028 per million tokens, compared to $0.140 for uncached input. That represents a 50x price reduction (98.0% discount) on recurring prompt prefixes.
How does MiMo-V2.6-Flash pricing compare to MiMo-V2.6-Pro?
Flash is more than 3x cheaper on uncached input ($0.14 vs $0.435) and output ($0.28 vs $0.87). On cached input, Flash costs $0.0028 / 1M versus $0.0036 / 1M for Pro.
Are internal reasoning tokens charged separately in Flash RL?
No. Xiaomi MiMo bills internal reasoning tokens together with visible text as standard output tokens at $0.28 per million tokens. There is no separate thinking surcharge line item.
Does MiMo-V2.6-Flash offer an UltraSpeed mode?
No. UltraSpeed is an exclusive 10x tier for MiMo-V2.6-Pro. Flash inherently operates at high generation speeds of 140+ tok/s due to its 15B activated MoE architecture.
Can I use MiMo-V2.6-Flash in Tabbit Browser?
Tabbit Browser provides an AI-native workspace for web research and automation. Available models in Tabbit depend on your account's live model selector and platform terms.