
To organize research across ChatGPT, Claude, and Gemini, keep one versioned brief outside the chats, give each tool the same evidence requirements, and collect the results in a claim-by-claim source table. Save the original reports separately. Write the final answer only after checking the sources behind important claims.
A Reddit discussion about academic research captures the practical problem: the project needs to survive switching tools. A useful reply recommends keeping source PDFs, notes, and verified outputs outside the conversation. That is the starting point here, rather than assuming any chatbot remembers what happened in another one.
Tabbit Browser provides two ways to help with this workflow: built-in multi-model replies for comparing answers, and Agent Mode for coordinating work in browser tabs. They have different permissions and outputs. The example below explains where each fits and what still needs manual checking.
Key takeaways
Keep the research brief, source register, and final decision outside any single chat history.
Use the same question and inputs for a controlled comparison. Assign different roles only when you deliberately want different work.
Tabbit multi-model replies compare models available inside Tabbit. They do not inherit the three providers' website research tools.
An Agent can help open and operate websites, but login, plan eligibility, quotas, research plans, and completion must be checked on each site.
Treat agreement as a reason to inspect evidence. Count independent sources, not agreeing models.
Research organization at a glance
| Approach | What you compare | Access needed | What to save |
|---|---|---|---|
| One prompt in Tabbit multi-model replies | Answers from the selected built-in models | Eligible Tabbit plan and currently available models | Prompt version, model labels, each answer |
| Research on three provider websites | Reports produced by each site's research feature | Separate website accounts, feature access, and quotas | Conversation URL, research mode, original report, sources |
| One primary tool plus a reviewer | A sourced report and a critique of it | Access to the tools you choose | Original evidence and the review separately |
| Manual browser research | Original webpages and your own analysis | Permission to access those webpages | Source register and dated notes |
The first two rows solve different problems. A GPT-family model response in Tabbit is not proof that ChatGPT Deep Research ran. The same distinction applies to Claude and Gemini. Our guide to AI deep research use cases explains why multi-step research differs from an ordinary answer.
1. Write one brief before opening three chats
Choose a bounded decision. "Research project management software" is too broad. "Compare three tools for a five-person design team, using publicly documented export and guest-access features" gives every research run a target.
Include the audience, region, cutoff date, exclusions, required deliverable, and acceptable sources. Mark private material before sending it to any provider. If one tool cannot access a file, either give all tools the same accessible excerpt or record that the inputs differ. You cannot fairly compare answers when one model received a full report and another only saw its title.
Use a simple naming rule such as design-tools / export-access / 2026-10-29 / brief-v1. The exact separator is unimportant. The useful part is that the same identifier appears in your document, filenames, and conversation titles wherever renaming is available.
Research brief v1
Decision: Which of Tools A, B, and C fits a five-person design team?
Region: Singapore. Evidence cutoff: 2026-10-29.
Criteria: guest permissions, usable export formats, account requirements.
Sources: prioritize official help pages and current product documentation.
Do not infer a feature from marketing language or a search snippet.
For every important claim, provide the source URL, page title,
publication/update date when visible, and the supporting passage.
Separate documented facts, your interpretation, and unknowns.
Deliver: comparison table, unresolved questions, and a short recommendation.
Do not purchase, start a trial, or contact vendors.
This is a reusable example, not a completed comparison of real vendors. Replace the placeholders and remove any unnecessary inputs. For the underlying browser structure, profiles, workspaces, and tab groups have different jobs. A tab group can hold your research pages; it does not merge the accounts or conversation memories inside them.
2. Choose independent comparison or a division of work
For a controlled comparison, give all three tools the same brief first. Do not show the second tool the first tool's conclusion. Otherwise you are testing whether it can react to that conclusion, rather than what it finds independently.
For a cheaper workflow, let one tool gather a report and another challenge its reasoning. A discussion comparing the three research tools includes this practical pattern: ask ChatGPT and Gemini the research question, then use Claude to challenge gaps and weak conclusions. That is a user's workflow preference, not evidence that those roles are universally best.
Choose roles by the job and the access your accounts actually have. One tool might have permission to read an approved document repository; another might be limited to the public web. Record that difference before evaluating their output. Avoid fixed claims such as "Gemini always researches best" or "Claude is always the critic."
Use built-in multi-model replies for question framing, alternate explanations, and a first pass at a source checklist. Use native research features when the deliverable requires the site's search, planning, and report workflow. Agentic reasoning and deep research provides more background on that distinction.
3. Check each website's research permissions
Sign in to the intended accounts yourself. Check the mode and remaining allowance before submitting a long brief. A provider subscription and a Tabbit membership are separate purchases and separate permissions.
OpenAI's Deep research documentation describes starting a task through the tools menu or /Deepresearch, reviewing the proposed plan, and receiving a documented report. Availability and usage depend on the account. Read the in-product counter instead of copying an old monthly quota from a comparison article.
Claude's Research documentation states that Research is available on paid Claude plans and needs web search enabled. The documented web entry is the + menu, then Research. Connected tools can add a different source set, so inspect which connectors are enabled before a run. A normal Claude reply without this mode should be labelled ordinary chat in your register.
Google's Gemini Deep Research guide describes the native research workflow, including sign-in and age requirements. Opening its homepage alone does not establish eligibility. Check the tools available in your account and the plan shown before starting. Gemini's limits page explains that availability and limits can vary. If the mode is unavailable, record the block rather than quietly substituting a normal answer.
The account-specific UI and an end-to-end run across all three services were not tested for this guide. These instructions combine current documentation with an explicitly proposed workflow. They are not a promise of unattended completion.
4. Register each run before collecting answers
Start a row as soon as a task exists. Record provider, visible model if shown, mode, brief version, conversation URL, start time, and status. Useful statuses are not started, needs user action, running, complete, and failed. Do not mark a job complete because a tab opened or the model wrote an introduction.
Keep the first output unchanged. If you ask a follow-up, record it as a revision. Save the report in whatever format the website actually offers, or copy the relevant text into your own note with the conversation link. Do not assume every provider exports the same file types or that a private conversation URL is readable by your teammates.
You can store everything in one Markdown document and an attachments folder. A larger project may justify a spreadsheet. The structure matters more than the app. This also makes it easier to find old research in browser history and bookmarks without treating those histories as your only archive.
5. Build a source register, then compare claims
A useful source row contains a claim ID, the exact claim, original URL, publisher, visible date, date checked, supporting passage, and verification status. Use the same source ID when multiple reports cite the same document.
Suppose two reports say a tool permits guest exports, while another says only administrators can export. First check whether they mean the same file format, plan, and role. All three answers could describe different conditions. A disagreement table should expose that mismatch before a synthesizer turns it into a confident sentence.
C-01 | Guest can export project data
ChatGPT report: yes, cites S-01
Claude report: administrator only, cites S-02
Gemini report: unclear, cites S-01
Check: do S-01 and S-02 describe the same plan and export format?
Decision: unresolved until the relevant help page states the guest role.
This is an illustrative record, not a product finding. Mark claims verified, contradicted, or unresolved only after opening the original page. A URL in a generated report can be unrelated, outdated, or inaccessible. Keep the supporting passage short and preserve its conditions.
In an X post about his LLM Council experiment, Andrej Karpathy describes comparing model answers and having models evaluate one another, while questioning whether their ranking matched his own qualitative judgment. That is a useful reminder to retain human review. It is a personal experiment, not a benchmark for the workflow here.
Three reports citing one vendor page give you one underlying source. Two different articles repeating the same announcement may still represent one piece of evidence. For the tab-management side of the workflow, see how to handle too many browser tabs.
Putting this workflow into practice with Tabbit
Tabbit is useful when the brief, reports, and source pages are already spread across browser tabs. Its role here is to reduce repeated browser work and keep comparison visible. The researcher workflow page covers the broader use case.
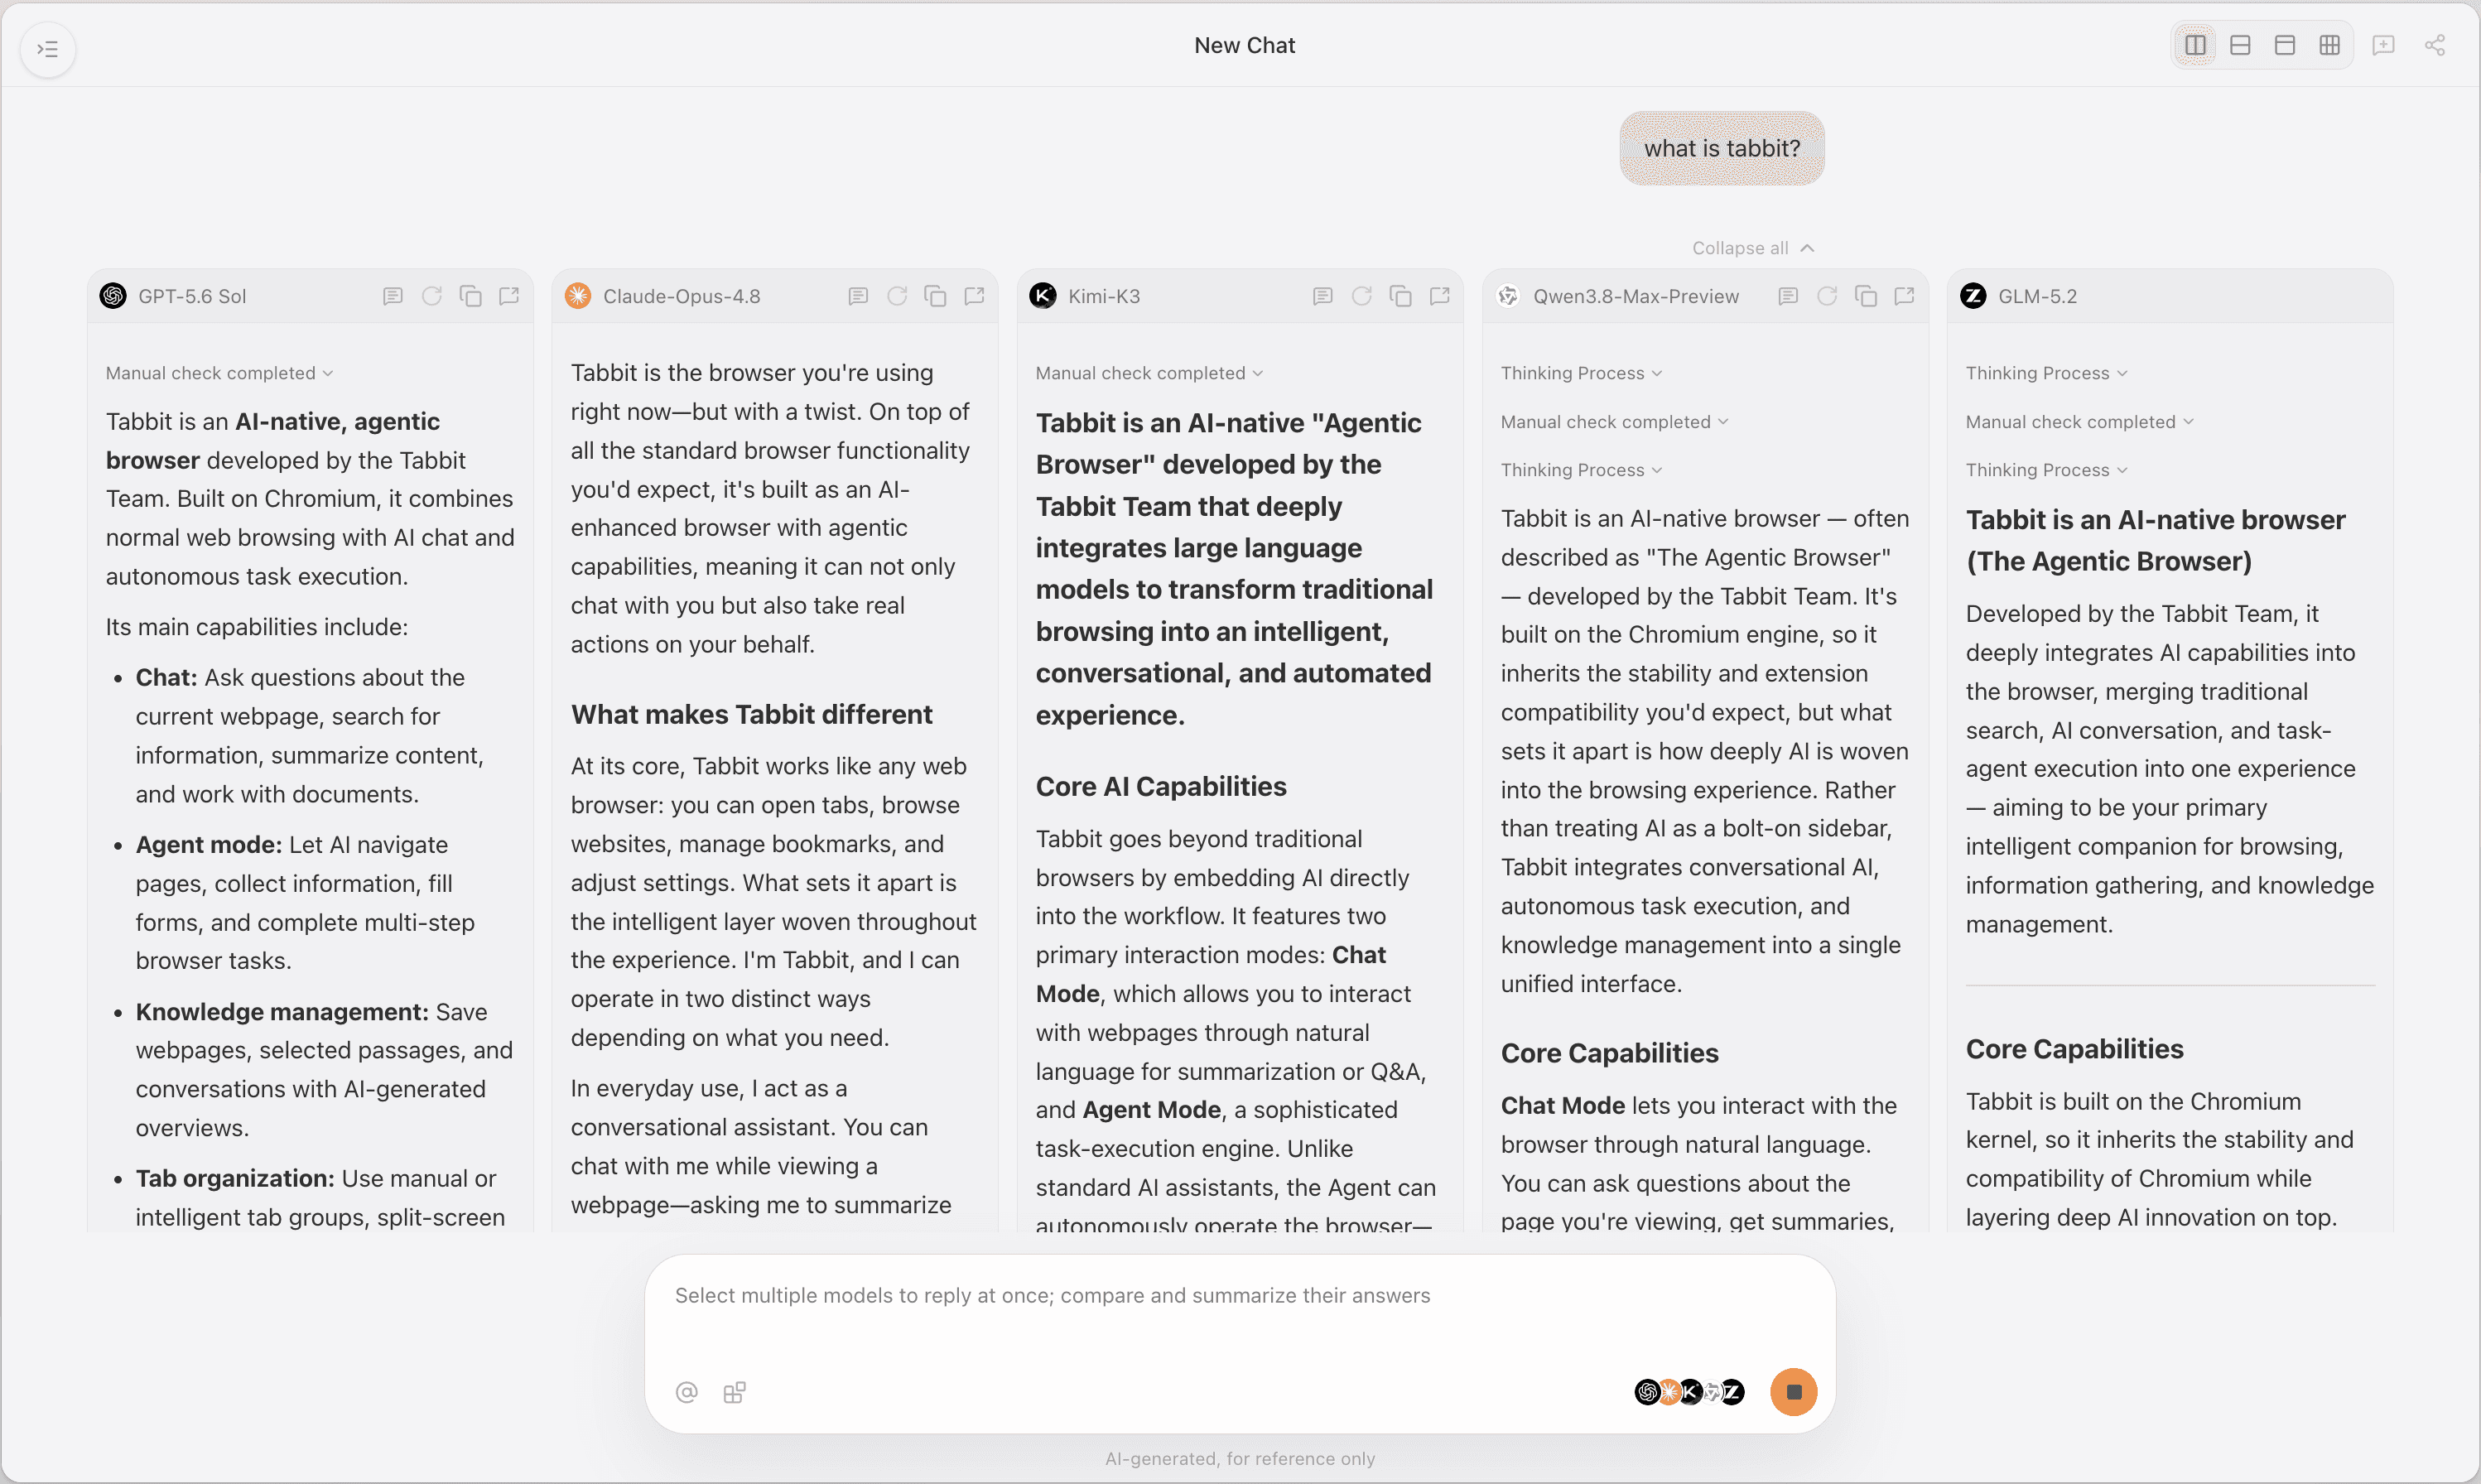
For a quick comparison, open Tabbit's model selector and select multiple models if that option is available to your plan. Submit the same short brief and compare the labelled responses. The international membership page lists simultaneous multi-model replies under Standard, unlocked by setting Tabbit as the default browser. The domestic membership page also lists the capability, but model availability and plan details should be checked in the edition you use. No fixed GPT, Claude, or Gemini lineup is guaranteed here.
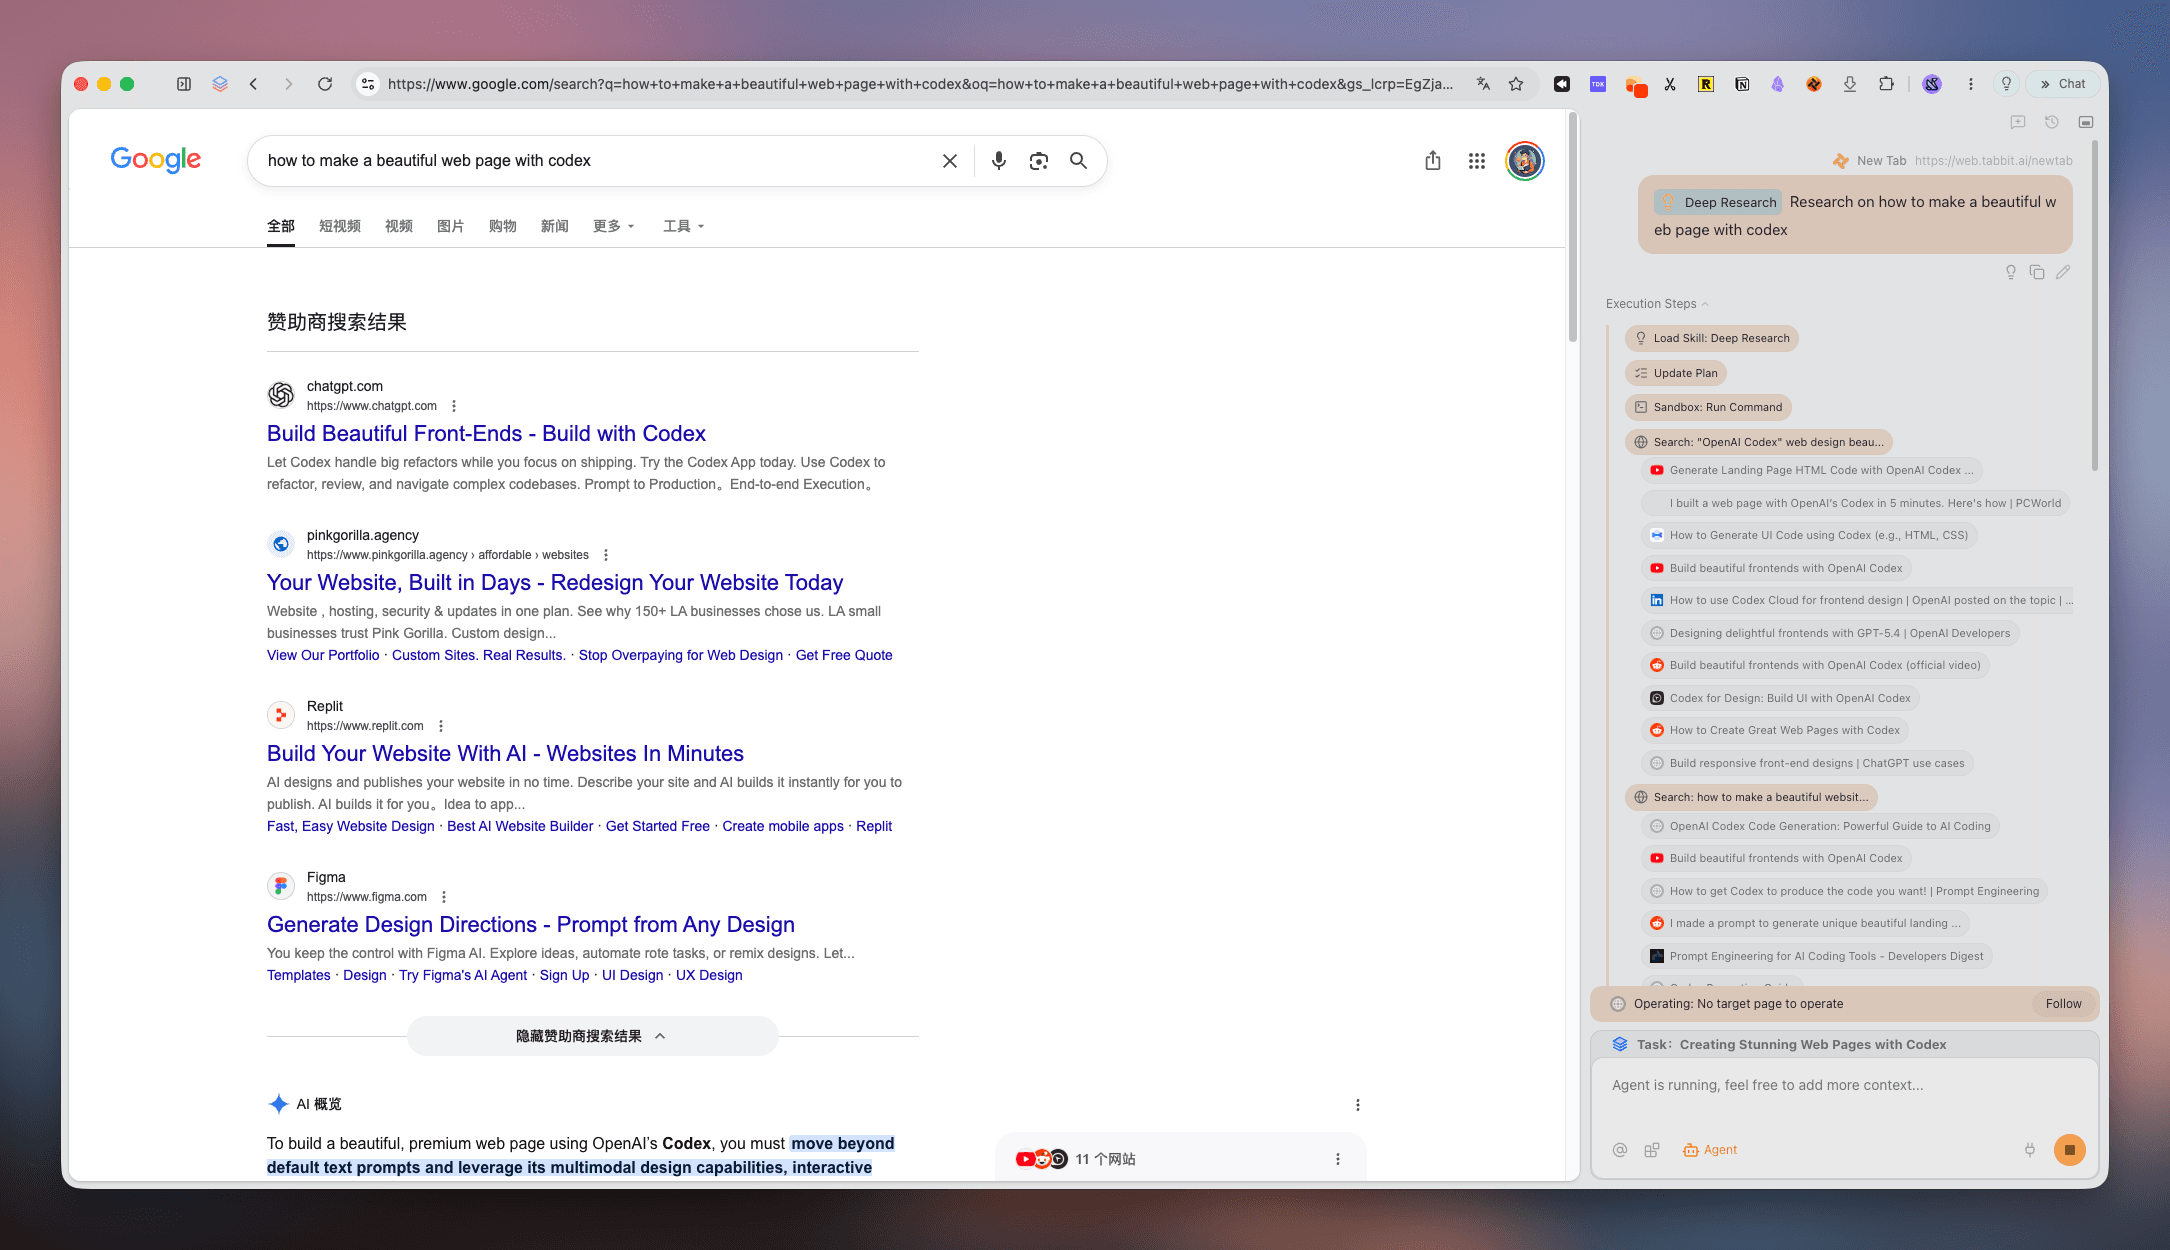
For website research, switch to Agent Mode and describe the browser task explicitly. Ask it to open ChatGPT, Claude, and Gemini, check whether each research control is available, and use the shared brief only where access permits. Several websites can remain open while provider-side research runs. The Agent may perform browser actions sequentially; this guide does not establish simultaneous execution or guaranteed completion. Our browser automation guide explains the broader distinction between describing a task and verifying its outcome.
Open https://chatgpt.com/, https://claude.ai/, and https://gemini.google.com/
in separate tabs for this research task. Reuse only the intended signed-in accounts.
First report each site's login state, available research mode, and visible quota.
Stop on login, CAPTCHA, payment, permission, or quota blocks and tell me what is needed.
Do not buy a subscription or change account settings.
Where access permits, select the site's research mode and use Research brief v1.
Show me any proposed plan or scope changes before starting that site's research.
After I approve the plans, start the eligible jobs and record their conversation URLs.
Track each site separately. Do not report success until its report is complete.
Collect the original reports and cited source URLs without merging them yet.
Do not share private files between providers or publish any result.
This prompt is a proposed orchestration template, not a tested three-site recipe. If a control cannot be operated reliably, do that step manually and let the Agent continue with collection. You can use @ references to supply selected tabs or files to a Tabbit conversation, as documented on the official site, but inspect exactly which context is attached. Opening a tab alone does not synchronize the website's chat history with other tools. See what Tabbit Browser does for the product overview.
6. Ask for a synthesis that preserves uncertainty
Give the synthesizer the verified source register and the original reports. Ask it to distinguish directly supported claims from recommendations. Restrict the final answer to evidence in the register, and keep an unresolved section rather than filling gaps from memory.
Using brief v1 and the attached source register, write the decision memo.
Cite source IDs beside material claims and link each ID to its original URL.
Separate verified facts, interpretation, and unresolved questions.
Do not count agreement between models as independent evidence.
Preserve conflicts about dates, plans, roles, regions, and definitions.
If the evidence cannot support a recommendation, say what must be checked next.
Before sharing, open the sources supporting your conclusion and check whether the memo preserved their conditions. A second model can find omissions, but it cannot replace that check. For source-heavy projects, browser research organization is a useful companion to the method here.
Choose the smallest workflow that answers the question
| Situation | Start with | Add another tool when |
|---|---|---|
| A quick factual question | One search and its primary source | Evidence conflicts or the scope expands |
| Framing an unfamiliar topic | Tabbit multi-model replies, if available | You need sourced, multi-step investigation |
| A consequential comparison | One native research report plus verification | A reviewer can challenge gaps or assumptions |
| Comparing provider research outputs | Three website runs with the same brief | Each account has access and the comparison justifies the time |
| A login, quota, or permission block | Record the block and use accessible evidence | The account owner resolves it |
For a small question, three full research runs can create more reading than they save. Start with one source-based answer. Add a reviewer when a missed assumption could change the decision; run all three when comparing their reports is itself useful.
When you do use all three, the durable result is a checked source register and a decision memo that another person can follow. Keep the brief and reports with them. If repeated tab work is the bottleneck, try one bounded Tabbit Agent task first and verify every status before expanding the workflow.

FAQ
Can Tabbit run ChatGPT, Claude, and Gemini Deep Research at once?
Agent Mode can help coordinate browser tasks, but each website needs its own eligible account, available research feature, and quota. Opening three tabs does not prove three research jobs started. This guide does not claim an end-to-end three-site research run was tested.
Are Tabbit multi-model replies the same as using the three websites?
No. Built-in replies use models available through Tabbit. They do not automatically include ChatGPT, Claude, or Gemini website features, subscriptions, conversation histories, or connectors.
How do I keep context consistent across different AI tools?
Maintain a versioned research brief outside the chats. Give every tool the same scope, date range, source requirements, and input files, then record any changes before comparing outputs.
Which research features require a paid account?
Claude Research currently requires a paid Claude plan and web search enabled. ChatGPT and Gemini availability and limits depend on the account and plan. Tabbit has its own regional membership entitlements, separate from those websites.
Does agreement between three models verify a claim?
No. They may cite the same page, repeat an unsupported claim, or use different definitions. Check the underlying primary source and record whether it directly supports the statement.
What should I save when a research session ends?
Save the brief version, provider and mode, conversation URL, original report, source URLs, and verified conclusions. Keep unresolved disagreements and access failures visible so another researcher can resume the work.