
LongCat 2.5 is the practical starting point if your task includes screenshots or video, or if the official API bill matters most. DeepSeek V4 Pro is the stronger choice when you need published weights that you can host yourself. For text-only coding quality, the available evidence does not establish an overall winner.
The decisive difference is visible before any benchmark: LongCat's official API accepts images and video; DeepSeek's current V4 Pro API lists vision as unsupported. Both advertise a roughly one-million-token context, but equal context sizes do not mean equal capabilities. Sources were checked on November 3, 2026. (LongCat visual docs, DeepSeek API)
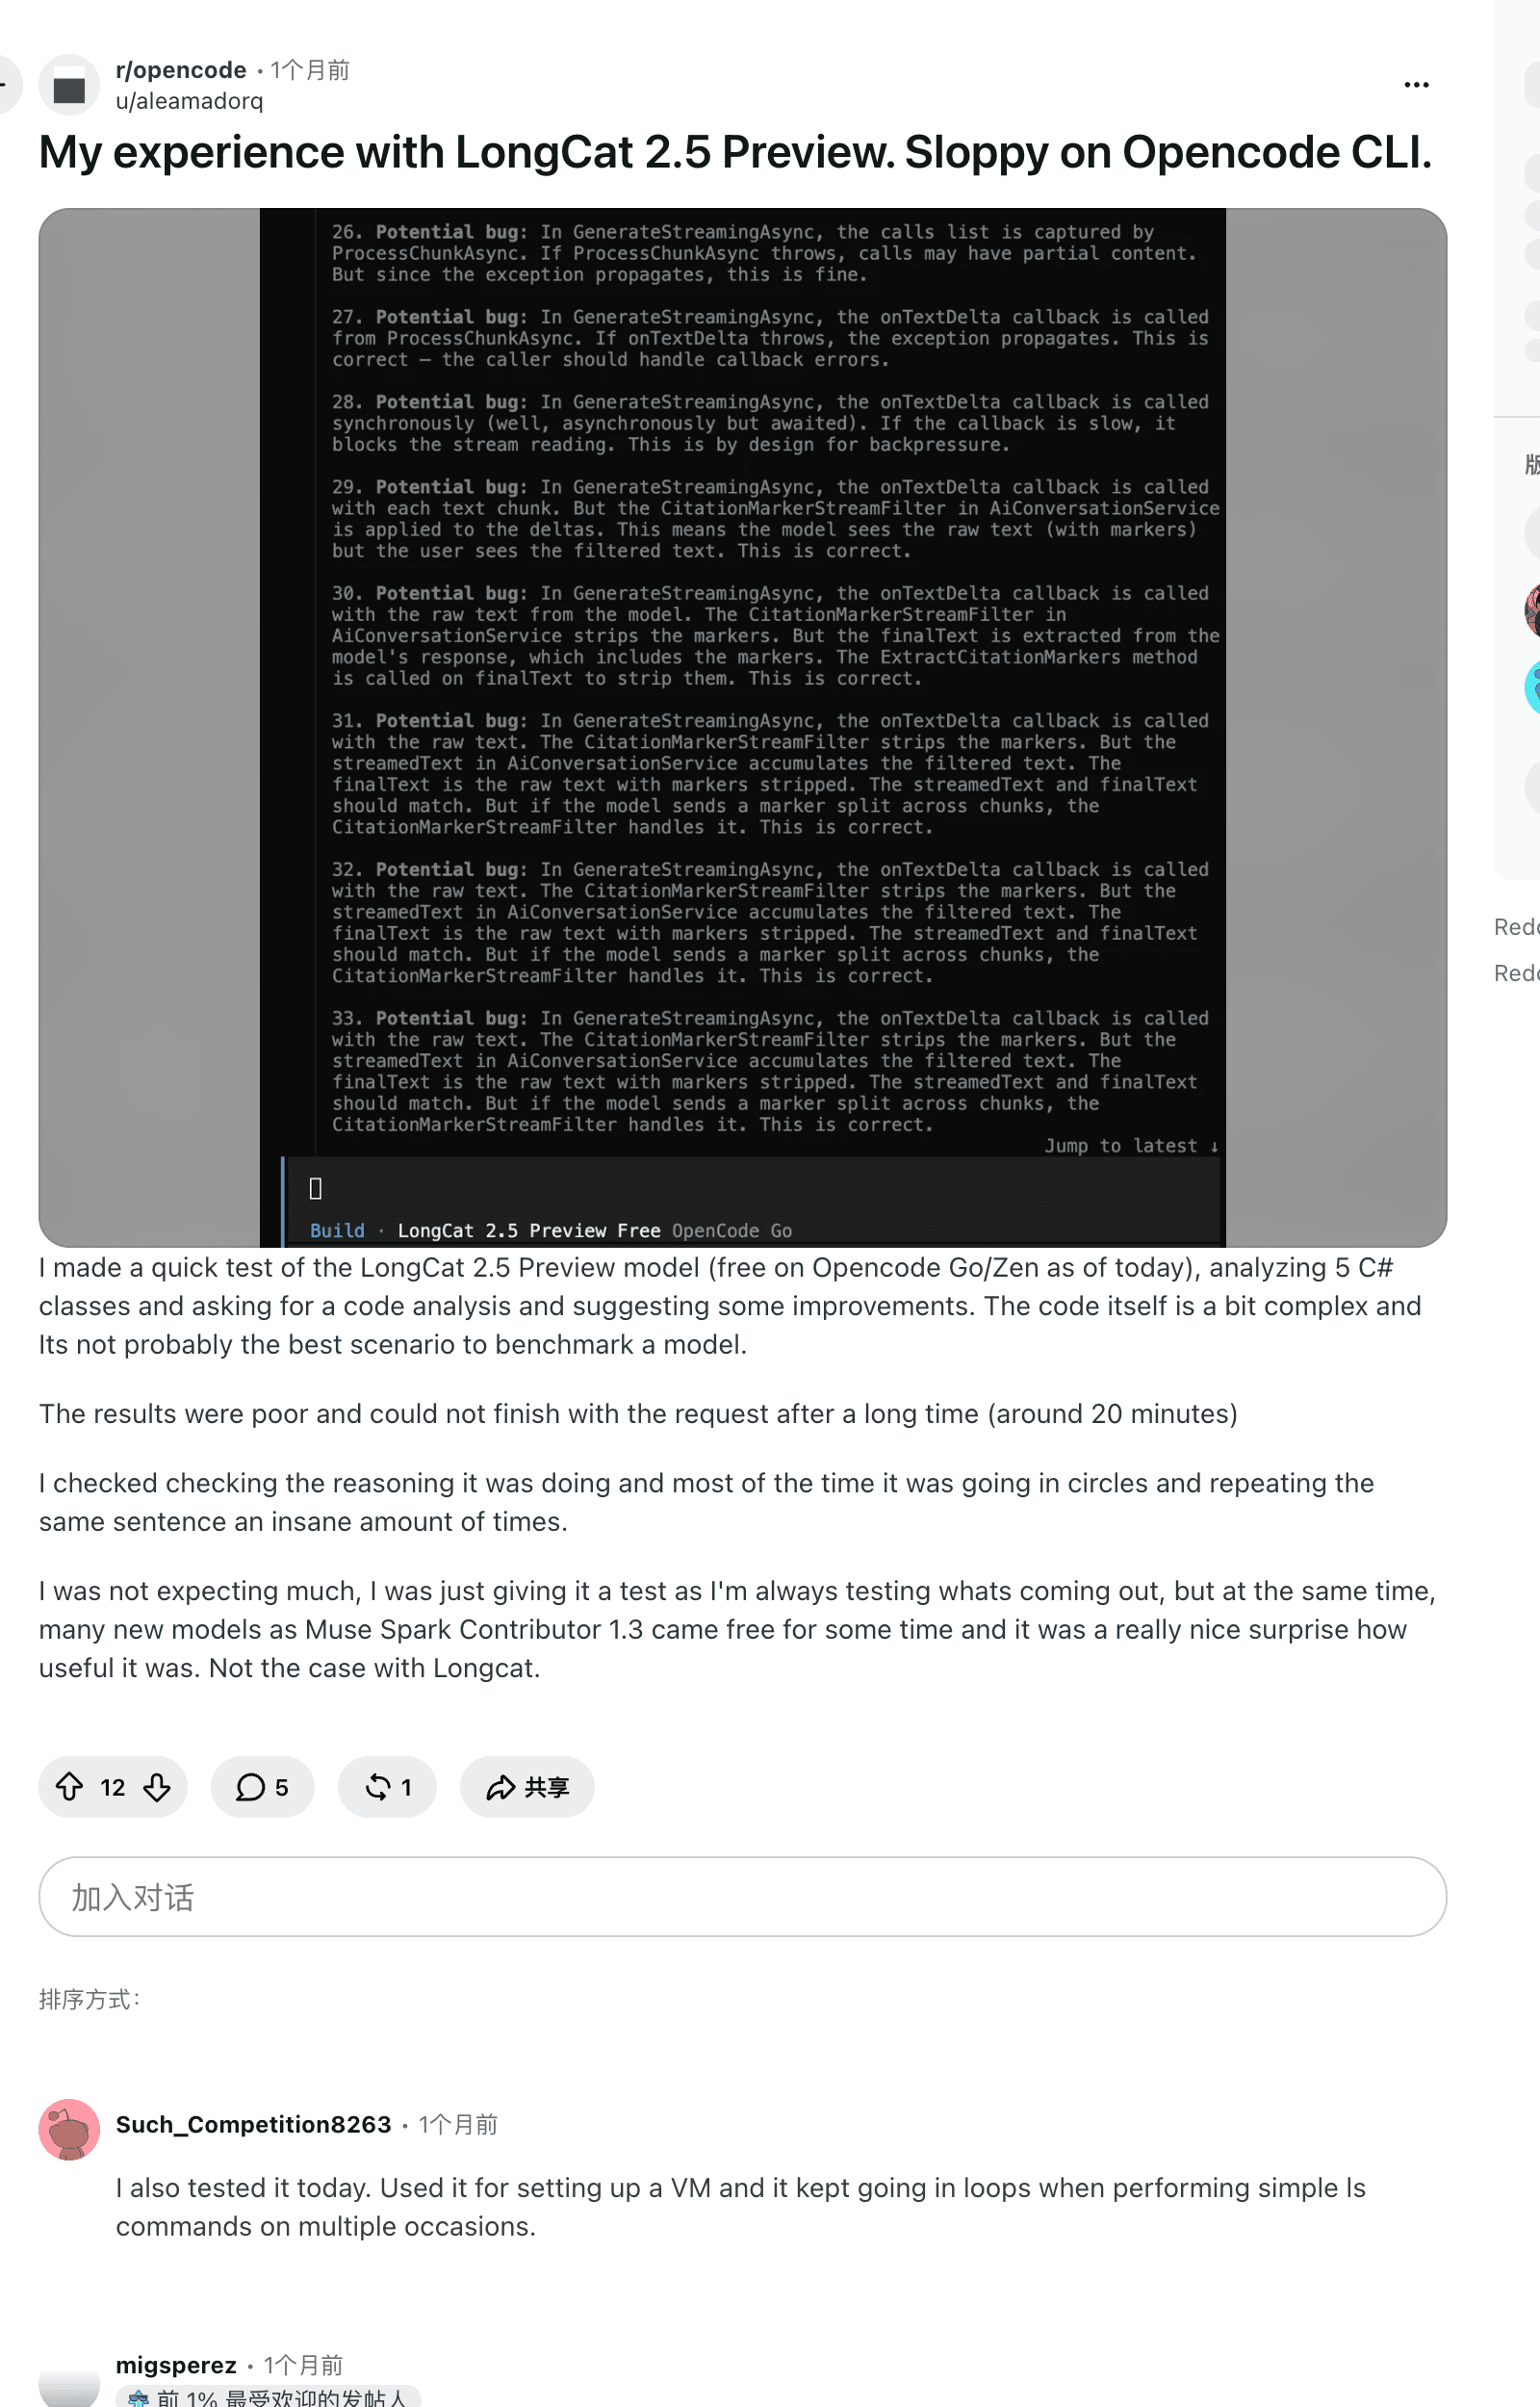
A developer who tried LongCat 2.5 Preview on five C# classes reported repeated reasoning and an unfinished task. That is a single preview run, not a test of the released model, but it shows why model selection should include the actual coding environment, not just the rate card. Later in this article we outline a repeatable comparison and where Tabbit Browser can help organize the source material. (Original Reddit post)
Key takeaways
LongCat 2.5 accepts image and video inputs in its official API. DeepSeek V4 Pro's official API is text-only.
LongCat's limited-time rates are $0.30 uncached input, $0.006 cached input and $1.20 output per million tokens. DeepSeek Pro costs more at both official rate periods.
DeepSeek publishes MIT-licensed V4 Pro weights. LongCat 2.5 weights were marked coming soon in the release material checked here.
Reports about LongCat 2.5 Preview are mixed. A preview result does not automatically describe the November 2 release.
One matched arithmetic prompt in Tabbit produced the correct total from both models. It does not establish a coding winner.
LongCat 2.5 vs DeepSeek V4 Pro at a glance
| Decision | LongCat 2.5 | DeepSeek V4 Pro | What it means |
|---|---|---|---|
| Version | LongCat-2.5, released November 2 | deepseek-v4-pro, currently V4-Pro-0813 | Pin the version and provider when evaluating. |
| Inputs | Text, images and video | Text; official API lists no vision | Choose LongCat for direct visual input. |
| Official context | 1,048,576 tokens | 1M tokens | Capacity is not a guarantee of recall. |
| Weights | Announced as coming soon | Published under MIT | Pro is the current choice for an open-weight deployment. |
| Official API input / output | $0.30 / $1.20 per million, limited-time | $0.66 / $1.98 off-peak; $1.32 / $3.96 peak | These are token rates, not completed-task prices. |
| Coding quality | Official and preview evidence available | Official evidence available | No verified matched test in this article. |
LongCat's release announcement describes 1.6 trillion total parameters and approximately 48 billion active per token. DeepSeek's V4 model card gives 1.6 trillion total and 49 billion active parameters for the V4 Pro family. Those numbers describe architecture, not a quality tie. LongCat's model parameters and prices, and DeepSeek's current API card, specify the remaining rows. The LongCat launch page was unreadable in our browser session; eesel's release report reproduces its coming-soon labels for GitHub and Hugging Face. Check the official repositories again before deployment.
The LongCat 2.0 overview covers the earlier model, while the DeepSeek V4 Pro overview explains its release and access. This comparison focuses on the choice between these two versions.
Visual input changes the task you can send
LongCat 2.5 can receive an image as base64 data or a public URL. Its documented video input uses a public URL. The official limits are 10 MB per image, up to 50 images per request, and 100 MB per video, up to 10 videos per request, each shorter than 3,600 seconds. It returns text rather than an edited image. Check the visual documentation for formats and limits.
That matters for a screenshot-to-interface task. LongCat can inspect the screenshot directly, then describe the intended layout or produce code. With the official V4 Pro endpoint, the equivalent workflow needs a separate vision step or a human-written description. A multimodal pipeline built around another service may still use V4 Pro for subsequent text reasoning; the extra step changes latency, cost and potential errors.
Do not confuse V4 Pro with DeepSeek V4.1 Flash. DeepSeek's pricing page lists vision for Flash, but not Pro. Its legacy Flash aliases now route to V4.1 Flash. The same page continues to list deepseek-v4-pro as V4-Pro-0813, so the Flash routing note should not be applied to Pro.
What coding evidence actually shows
Meituan's release reports agentic coding and visual results for LongCat 2.5. The benchmark table mixes the company's own runs and figures taken from other reports, so differences in harness and configuration matter. DeepSeek's model card also reports benchmark results, but a score from one vendor's setup cannot safely be joined with a different vendor's score to prove a direct win.
A useful warning comes from preview users. In the C# example, u/aleamadorq said LongCat 2.5 Preview repeated itself and failed to finish after roughly 20 minutes. The post does not include the full code, prompt or repeated trials. It cannot isolate the model from the provider and OpenCode environment.
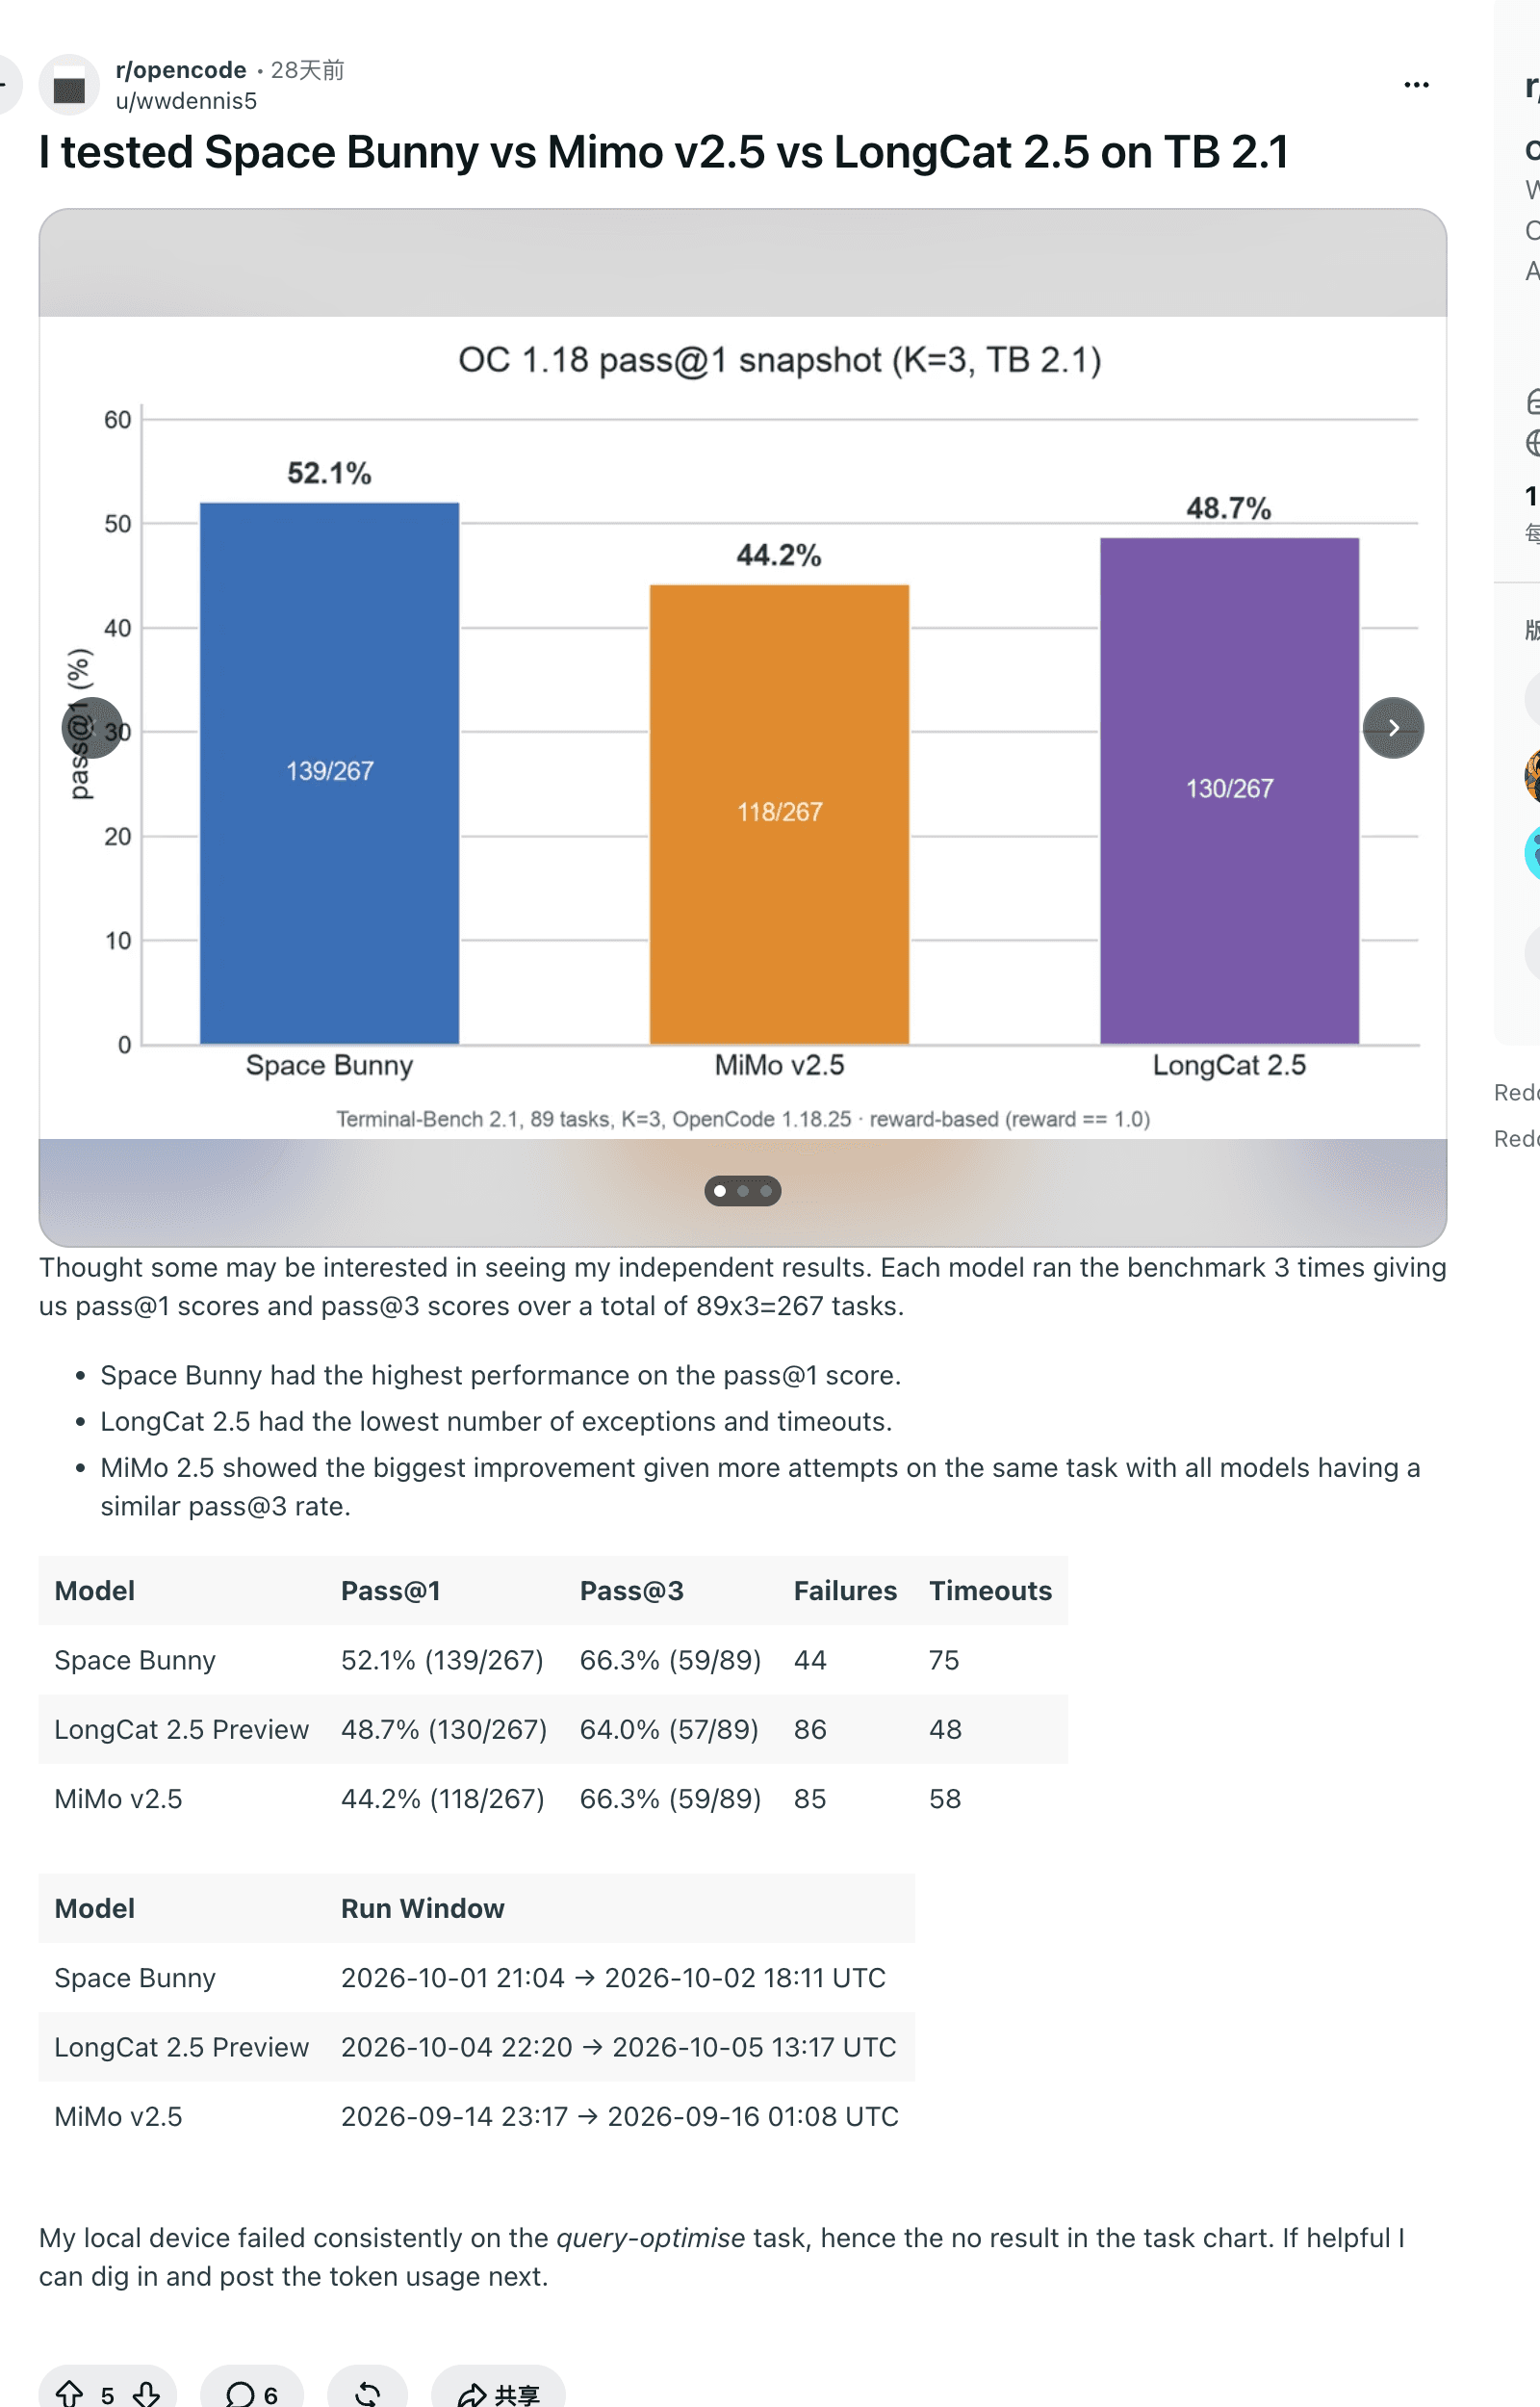
Another user reported a Terminal-Bench 2.1 run with 89 tasks and three attempts per model. Their LongCat 2.5 Preview result was 130 passes in 267 attempts, or 48.7% pass@1. The comparison did not include DeepSeek V4 Pro, and the author noted a local-device failure on one task. This is useful evidence of a particular setup, not a head-to-head result for this article. (Original benchmark post)
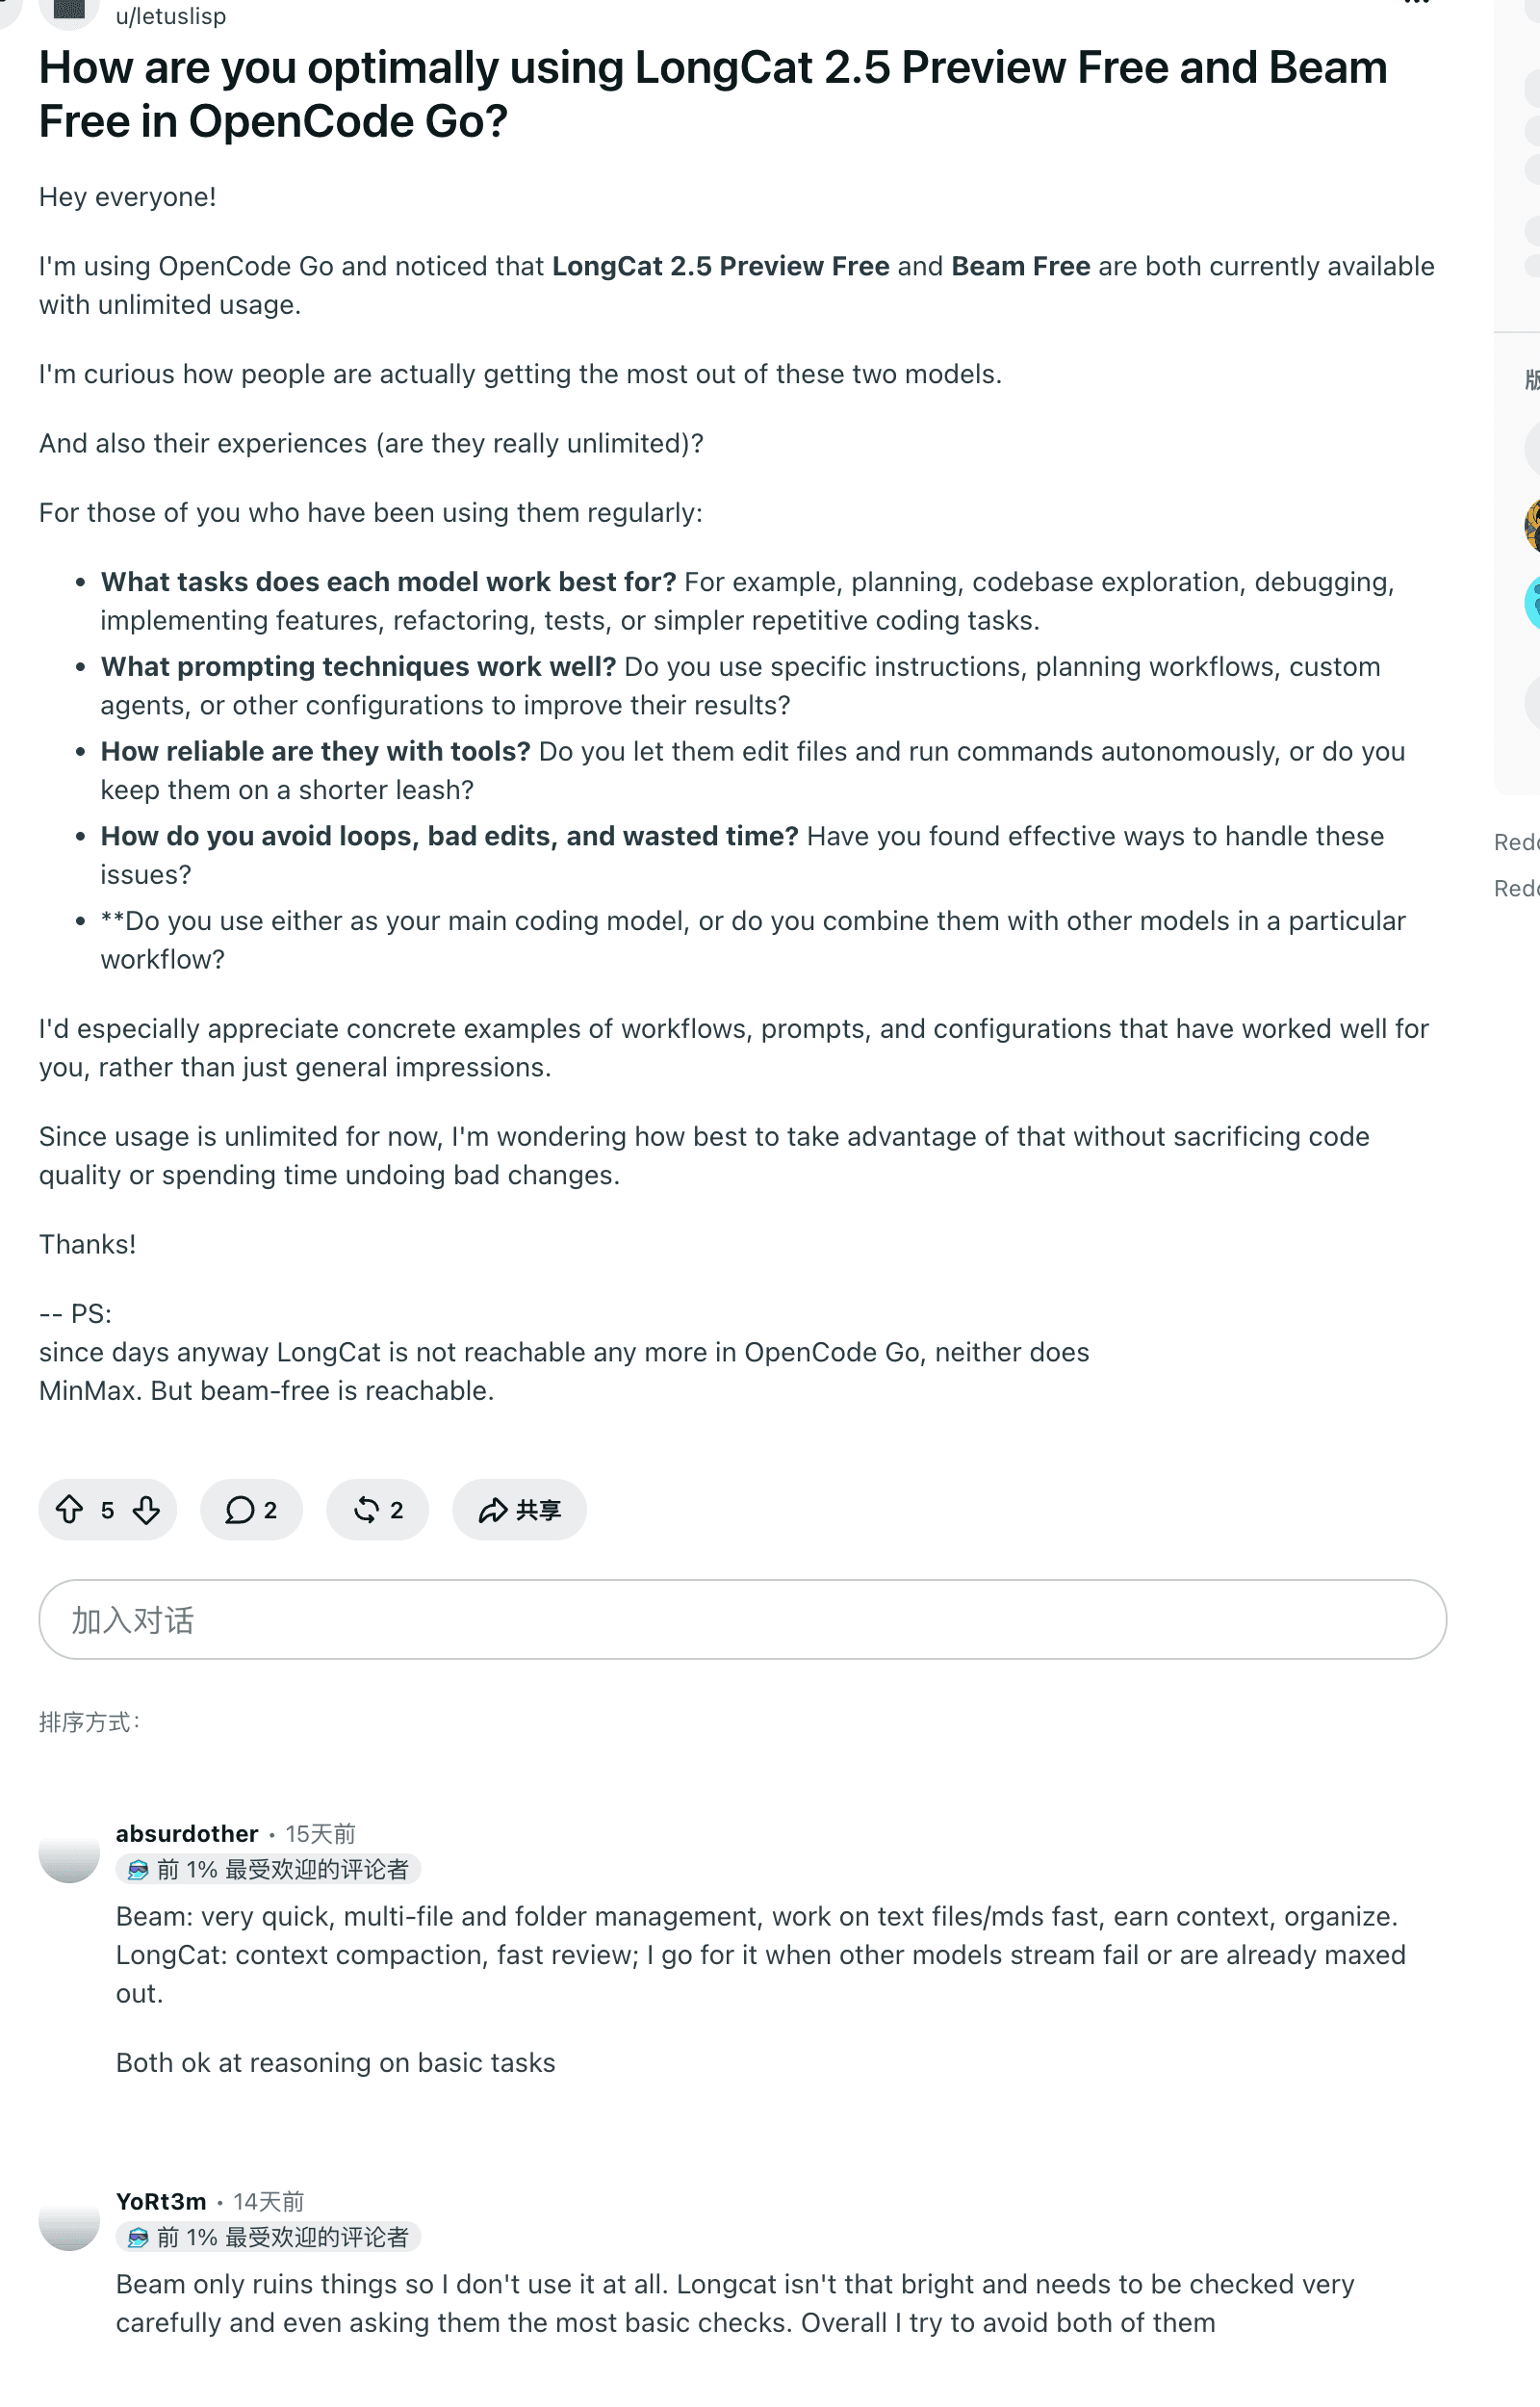
A different OpenCode discussion has one user choosing the preview for context compaction and fast reviews, while another says its work needs careful checking. Neither comment establishes a success rate. Both suggest a sensible trial: start with a bounded task, review changes and run tests before granting broader access.
API price: compare completed work, not only rates
The table below uses official API prices checked November 3, 2026. LongCat labels its prices limited-time. DeepSeek charges different peak and off-peak rates. Prices for third-party providers, subscriptions and Tabbit access are separate.
| USD per million tokens | LongCat 2.5 promotion | DeepSeek V4 Pro off-peak | DeepSeek V4 Pro peak |
|---|---|---|---|
| Uncached input | $0.30 | $0.66 | $1.32 |
| Cached input | $0.006 | $0.022 | $0.044 |
| Output | $1.20 | $1.98 | $3.96 |
DeepSeek defines peak as 01:00–04:00 and 06:00–10:00 UTC on weekdays, excluding Chinese public holidays. Other periods are off-peak. Check the DeepSeek price page and LongCat price page again before budgeting.
For a hypothetical request with 1 million uncached input tokens and 250,000 output tokens, with no cache or tool charges:
LongCat:          1 × $0.30 + 0.25 × $1.20 = $0.60
DeepSeek off-peak: 1 × $0.66 + 0.25 × $1.98 = $1.155
DeepSeek peak:     1 × $1.32 + 0.25 × $3.96 = $2.31
The arithmetic assumes identical token counts and one successful run. If one model needs more output or retries, the cost per accepted result changes. Image processing, tools, taxes, discounts and provider-specific billing can also change the bill. DeepSeek separately prices Search and Fetch requests; do not silently include them in token rates.
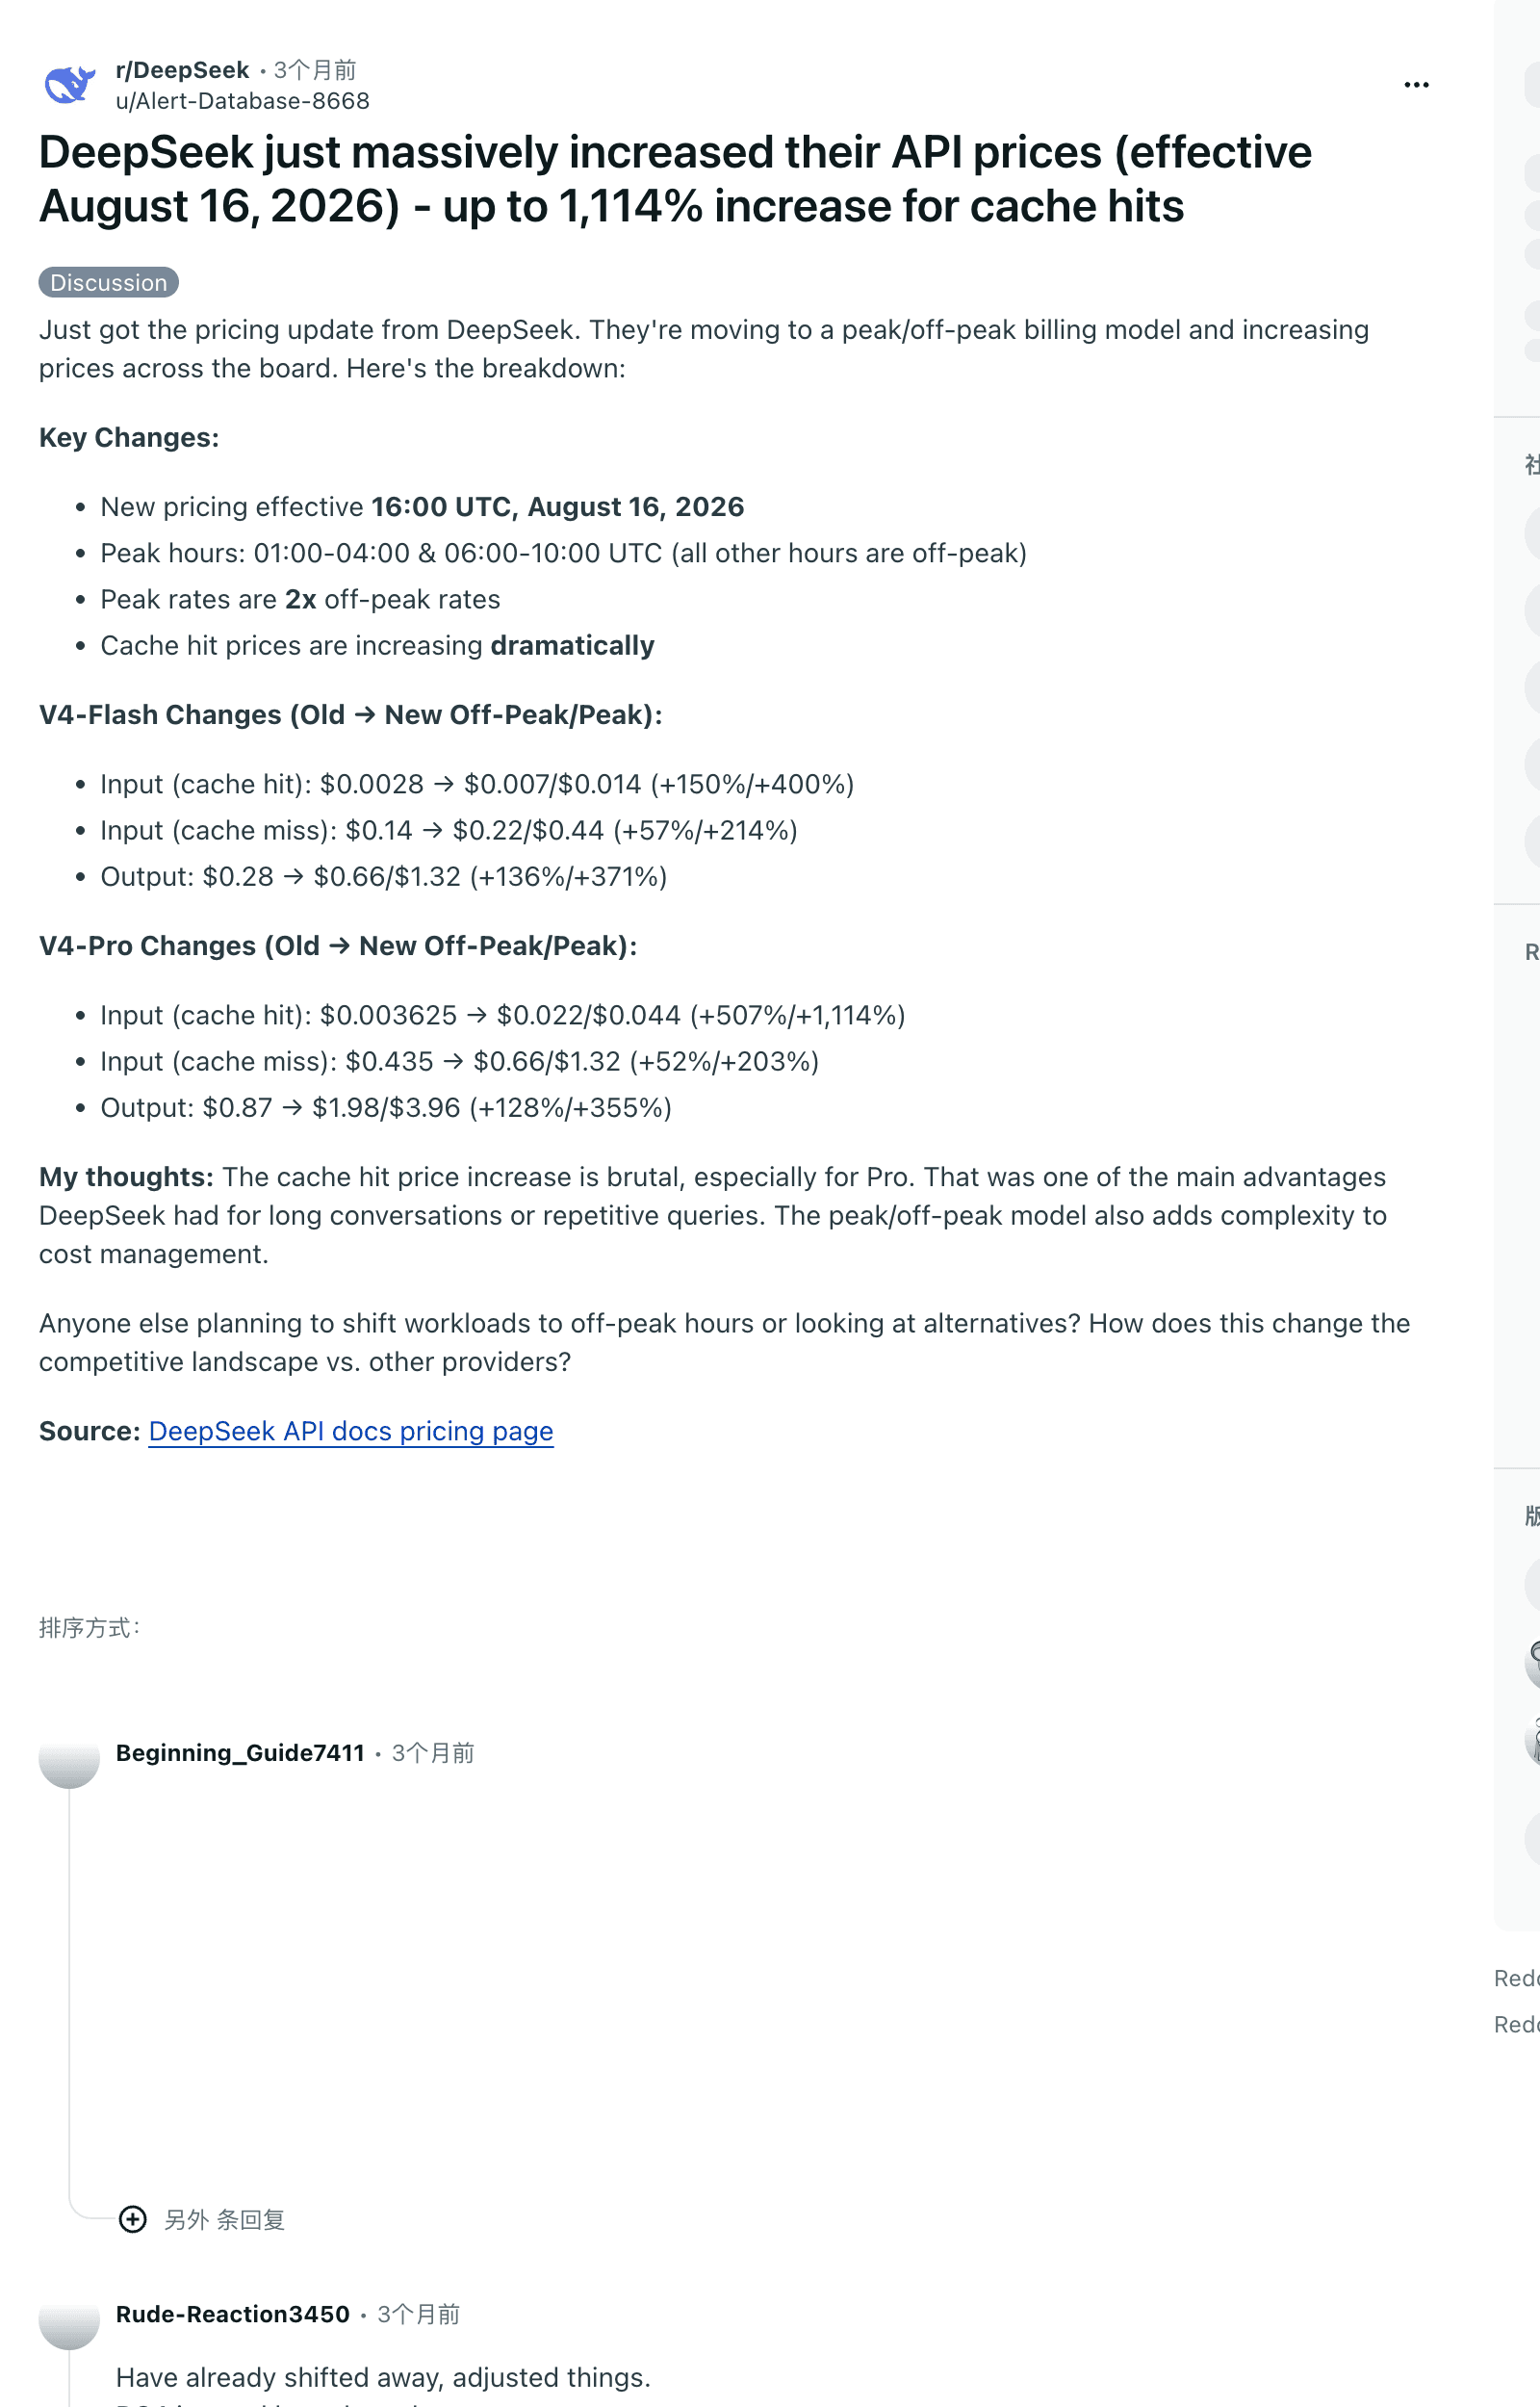
A Reddit discussion illustrates why cached input deserves its own row: a user worried that the Pro cache price increase would affect long conversations. The post is a historical reaction, not the authority for today's rates.
Test the decision in your own environment
Use the same repository revision, task description, tools, permissions and stopping criteria for each model. Record the provider, model ID, date, reasoning setting, token usage and whether tests passed. Give each run a fresh copy of the same repository. Compare the diff as well as the final answer.
A practical first task is a small bug with a known failing test. Ask the agent to explain the failure, make the smallest fix and run the existing tests. Check whether it modified unrelated files, whether it repeated tool calls, and whether the test passes independently. Repeat across several representative tasks before extrapolating. A single pass is not a reliability estimate.
For a visual task, compare LongCat's direct screenshot input with a separately documented image-to-text step followed by V4 Pro. This is a workflow comparison, not a pure model-only contest. Record the extra step and its cost. For more on agent tools and boundaries, see what an agentic browser does and browser automation. For the distinction between a model and an agent with tools, see what an AI agent is.
Use Tabbit to organize the comparison
Tabbit Browser can keep the vendor documentation and the test results together while you review them. Open the LongCat price and visual-input pages alongside the DeepSeek API card, group the tabs, then ask the sidebar to summarize the stated limits. Verify each number against the source page before using it in a budget. The Tabbit browser guide explains the browser workflow.
On November 3 we ran the same synthetic price calculation once per model in separate Tabbit Dev conversations, using Chat mode with no referenced files. Both displayed the selected model name and returned the expected $0.7824 total, with the three components. Both responses were in Chinese in this account's interface. Each also mentioned possible rounding or minimum charges; those statements are not verified provider billing rules.
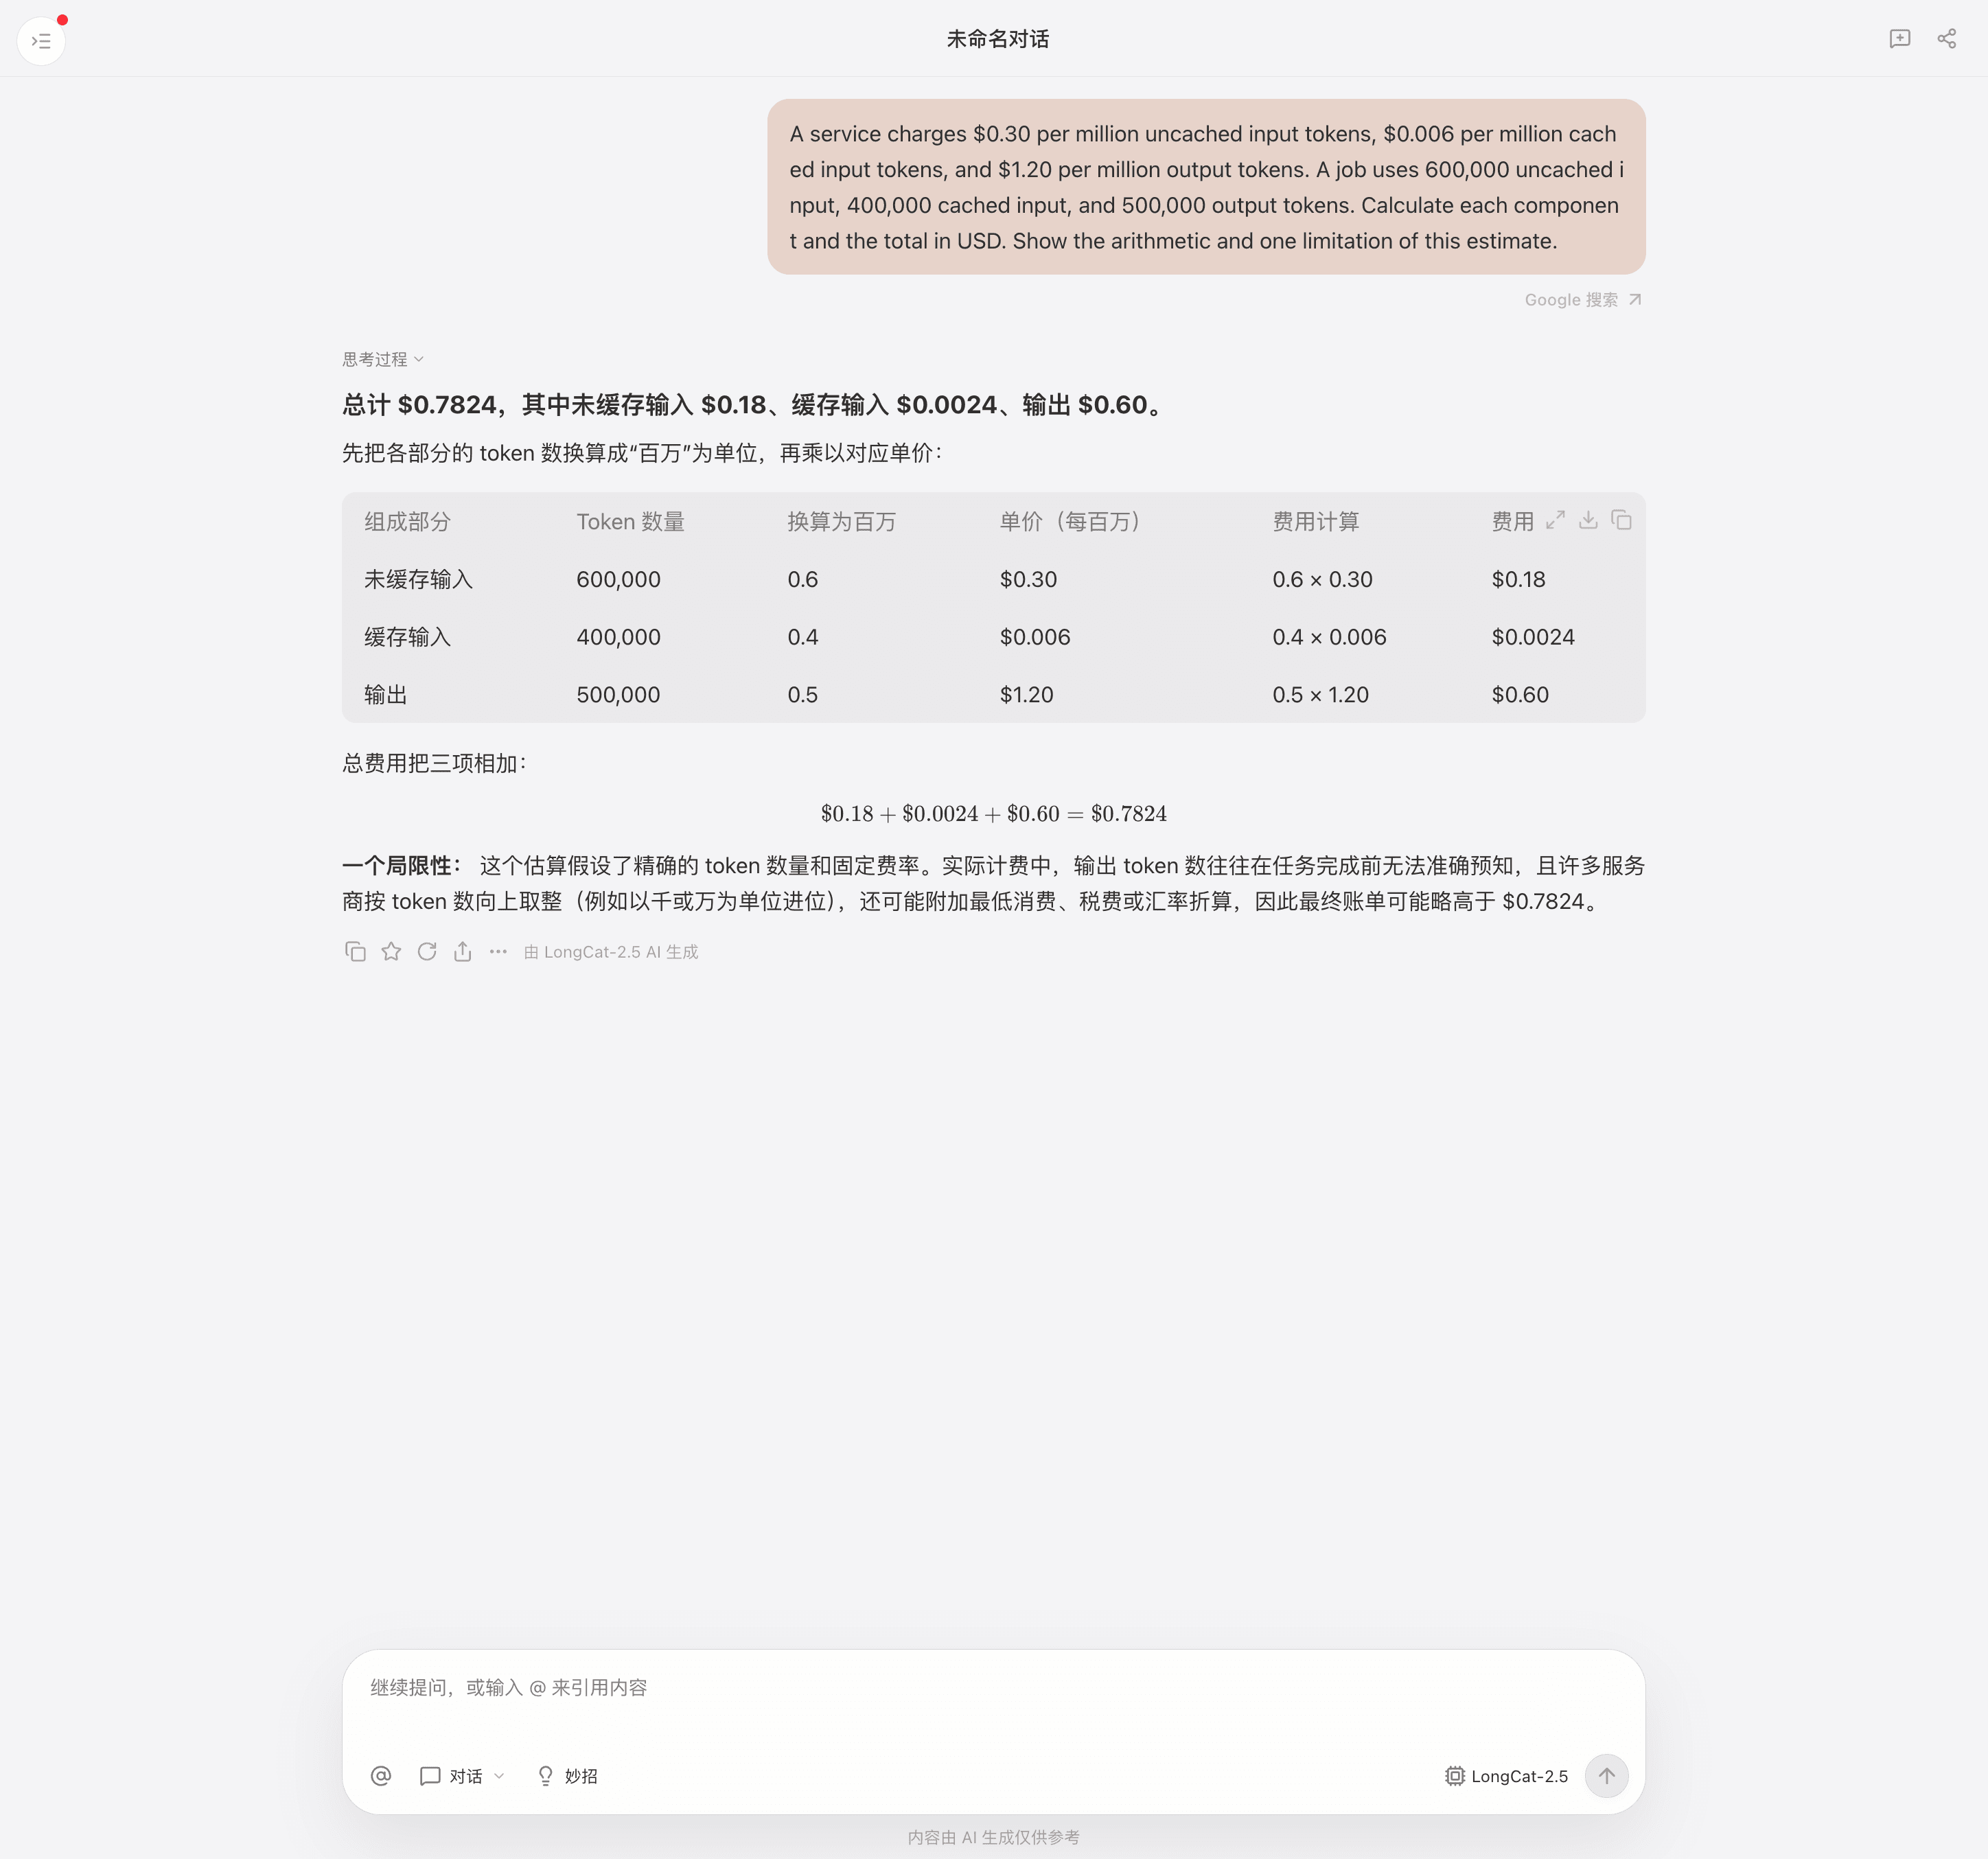
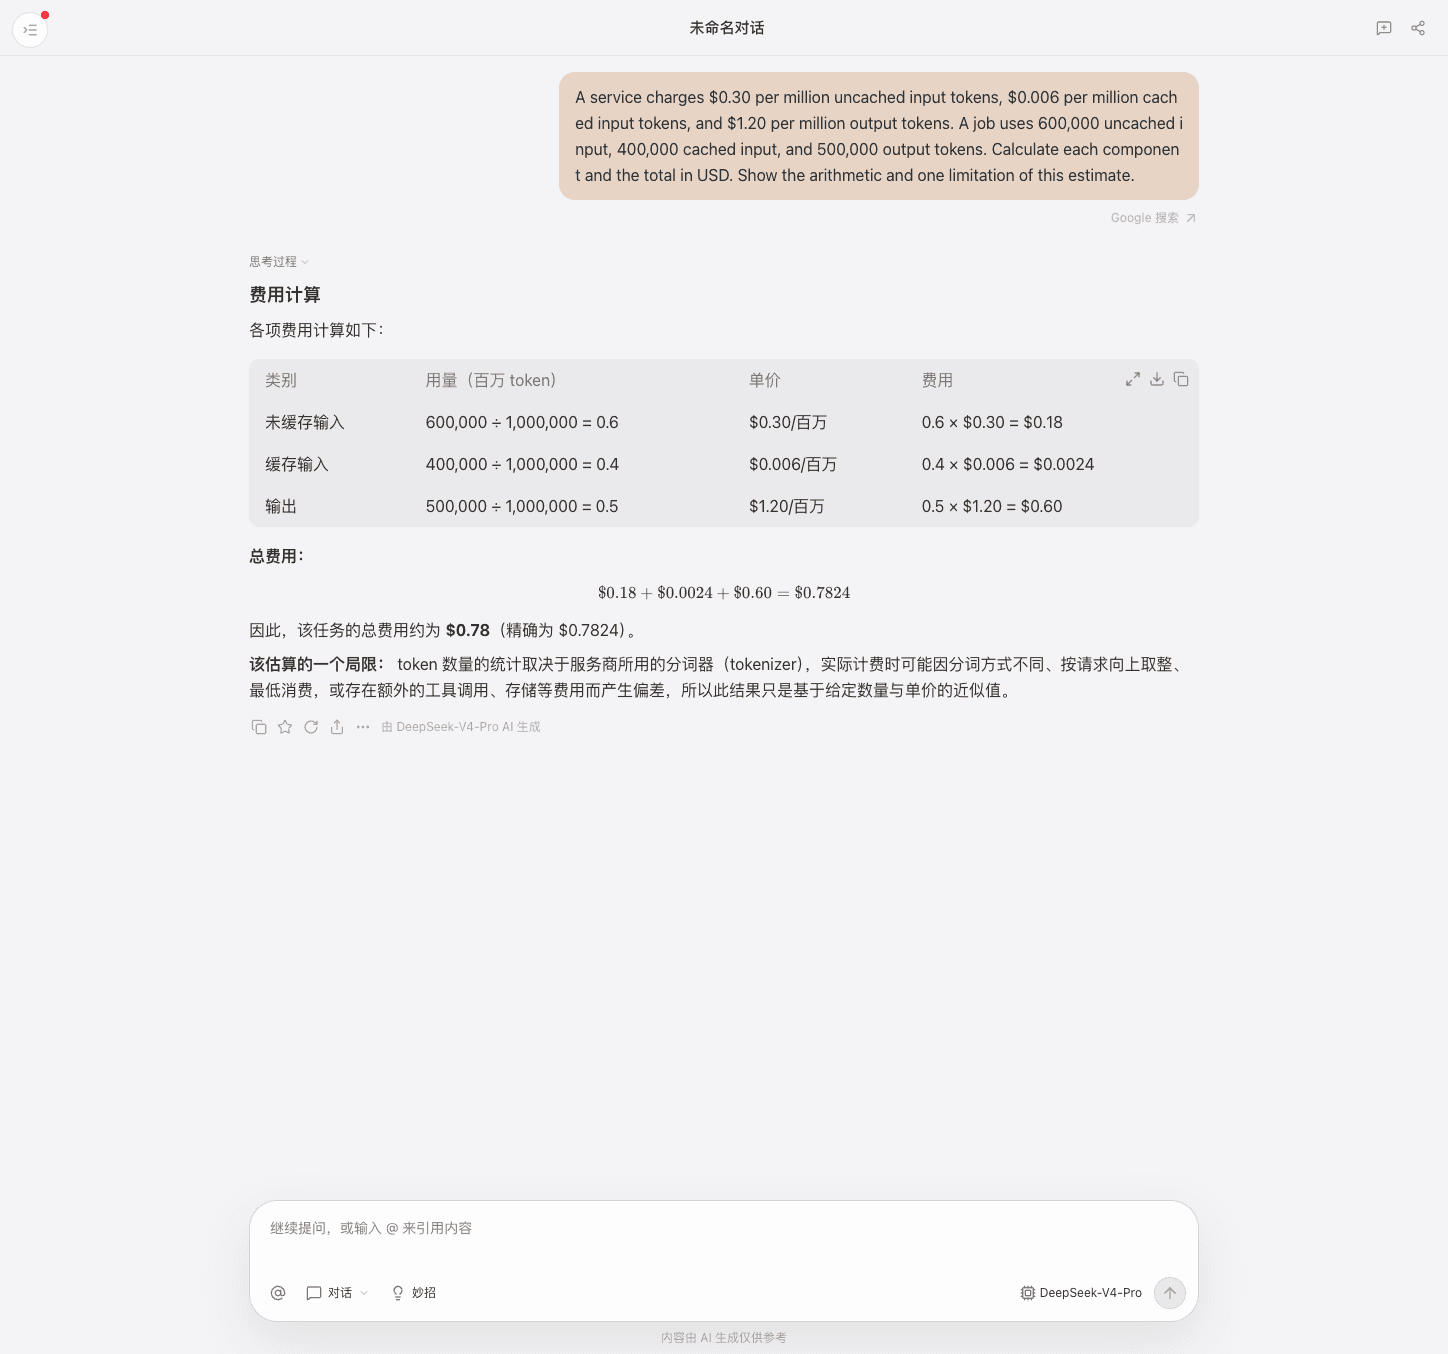
This one-task sample does not measure coding, vision, speed or reliability. The interface showed model labels, but not the exact backend version or reasoning configuration. Availability, quotas and charges depend on the account. See the AI browser comparison for the broader client choice.
 Tabbit Browser
Which one should you choose?
| Your constraint | Starting choice | Check before committing |
|---|---|---|
| Screenshot or video as model input | LongCat 2.5 | File format, privacy terms and actual output quality. |
| Open weights and self-hosting | DeepSeek V4 Pro | Hardware, inference stack, license and deployment cost. |
| Lowest official API rate at current prices | LongCat 2.5 | Promotion duration, cache use, retries and total tokens. |
| Text-only coding agent | Test both | Same repository, harness, effort, budget and acceptance tests. |
| An existing DeepSeek integration | V4 Pro may reduce migration work | Current endpoint, provider, peak window and whether a vision step is needed. |
Start with LongCat for visual input and the current promotional rate. Start with V4 Pro if open weights are non-negotiable. For an autonomous coding workload, run the same tasks and price the accepted result before moving production traffic. Tabbit can help you review the documentation and organize those tests; the model picker must still be checked on the account you intend to use.

FAQ
Which should I choose, LongCat 2.5 or DeepSeek V4 Pro?
Start with LongCat 2.5 for image or video input and lower official API token rates during its promotion. Consider DeepSeek V4 Pro for its published open weights or when your own text-only evaluation justifies its higher rate. A reliable general winner requires matched tests.
Can DeepSeek V4 Pro understand images?
DeepSeek's official API pricing page lists vision as unsupported for V4 Pro. LongCat's documentation says LongCat 2.5 accepts images and videos as input.
Is LongCat 2.5 cheaper than DeepSeek V4 Pro?
On November 3, 2026, LongCat's limited-time official API rates were lower for uncached input, cached input and output than both DeepSeek V4 Pro peak and off-peak rates. Actual task cost also depends on token use, retries, tools and provider.
Can I self-host these models?
DeepSeek publishes V4 Pro weights under the MIT license. LongCat's release page says its 2.5 weights are coming soon, so check the official repository for a later release and license before planning a deployment.
Do both models have a one-million-token context?
The official DeepSeek API lists a 1M context for V4 Pro. LongCat's documentation lists a 1,048,576-token context for LongCat 2.5. A long context limit does not establish retrieval accuracy across the entire window.
Do preview reports establish how the released LongCat 2.5 performs?
No. Preview users reported both useful narrow workflows and loops or unwanted changes. Those observations concern a preview and particular tools, so test the released model and your own harness before relying on them.