
LongCat-2.5 costs $0.30 per million uncached input tokens, $0.006 per million cached input tokens, and $1.20 per million output tokens on LongCat's international pay-as-you-go API. These are limited-time discounted rates checked November 3, 2026; the provider has not stated an end date on the rate card. This is an API quote, not a Tabbit or third-party subscription price.
The key number is 98%: a cached input token costs 98% less than an uncached one. An agent that repeatedly sends the same context can benefit, but the discount applies only to tokens actually reported as cache hits—not to output or the whole task. A developer discussing the launch on Hacker News pointed to cache hit rate and speed as uncertainties when comparing models at the same price. That is a comparison criterion, not a measurement of your workload.
This guide separates the official bill from pack quotas, provider offers and client subscriptions. It also shows two hypothetical budgets and a single Tabbit Browser test of the calculation.
LongCat 2.5 API pricing at a glance
USD per million tokens, checked November 3, 2026. The older column is the LongCat 2.0 documentation snapshot; it is not proof that 2.0 is still available for new first-party requests. The current pay-as-you-go guide lists 2.5.
| Billing category | LongCat 2.0 documented discount | LongCat 2.5 discount | Difference in displayed rate |
|---|---|---|---|
| Uncached input | $0.30 | $0.30 | $0 |
| Cached input | $0.006 | $0.006 | $0 |
| Output | $1.20 | $1.20 | $0 |
The identical displayed rates do not establish identical task cost. A model can generate different output, hit cache differently or require more attempts. The promotion may also change: check your account before committing a budget. The LongCat 2.0 overview covers the predecessor; its published weights and separate provider routes should not be assumed to apply to 2.5.
Key takeaways
The promotional cached-input rate is 2% of the ordinary input rate. Measure cache hits instead of assuming that every repeated token qualifies.
Output costs four times as much per token as uncached input and 200 times as much as cached input at the listed rates. Reasoning is part of output usage, not a second line to add again.
Pay-as-you-go and a 30-day Token Pack use different accounting. Official pack documentation says cache hits do not consume the pack's quota.
A successful HTTP response can still fail your acceptance checks. Compare total spend per accepted result, including billable retries.
A model API, a third-party gateway and a browser product have separate prices, limits and data terms.
Why cache hits matter
The official billing formula divides input into cached and uncached categories. Count a token once, then add output:
API token cost = (uncached input × 0.30
                + cached input × 0.006
                + output × 1.20) / 1,000,000
For one million input tokens, an 80% cache hit assumption means 200,000 uncached and 800,000 cached tokens. Input costs $0.0600 + $0.0048 = $0.0648, compared with $0.30 if none were cached: a 78.4% input saving, not a 98% saving on the entire bill. Output and other charges remain outside that calculation.
Repeated instructions, files and tool results can make caching relevant for coding agents. But the ratio depends on the actual request history and provider behavior. Check usage fields on real calls and keep changing content separate from reusable context where your integration supports it. A cache-heavy session is not automatically a cheap session if it produces a long response or repeatedly runs tools.
The Responses API reference reports cached tokens as part of input and reasoning tokens as part of output. Do not add reasoning_tokens to output a second time. The documented reasoning effort and thinking controls are settings, not a promise that one level will solve your task with fewer tokens.
Two workload estimates
These examples use the promotional first-party USD rates above. Token counts are assumptions, not measured results. Each row is within the documented combined context window; charges for external tools, taxes, gateway fees and retries are excluded.
| Workload | Uncached input | Cached input | Output | Estimated token cost per task | 1,000 tasks |
|---|---|---|---|---|---|
| Short document summary | 20,000 | 0 | 2,000 | $0.0084 | $8.40 |
| Repeated-context agent request | 200,000 | 800,000 | 40,000 | $0.1128 | $112.80 |
The first calculation is 20,000 × $0.30 / 1M + 2,000 × $1.20 / 1M. The second is $0.0600 + $0.0048 + $0.0480. One request is not necessarily one complete agent job: several calls, tool outputs and retries may be needed. The model parameters define the 1,048,576-token context as input plus output, so a 1M-token input leaves much less room for the answer.
Before a production trial, record request counts, input, cached input, output, accepted results and total invoice. Then calculate:
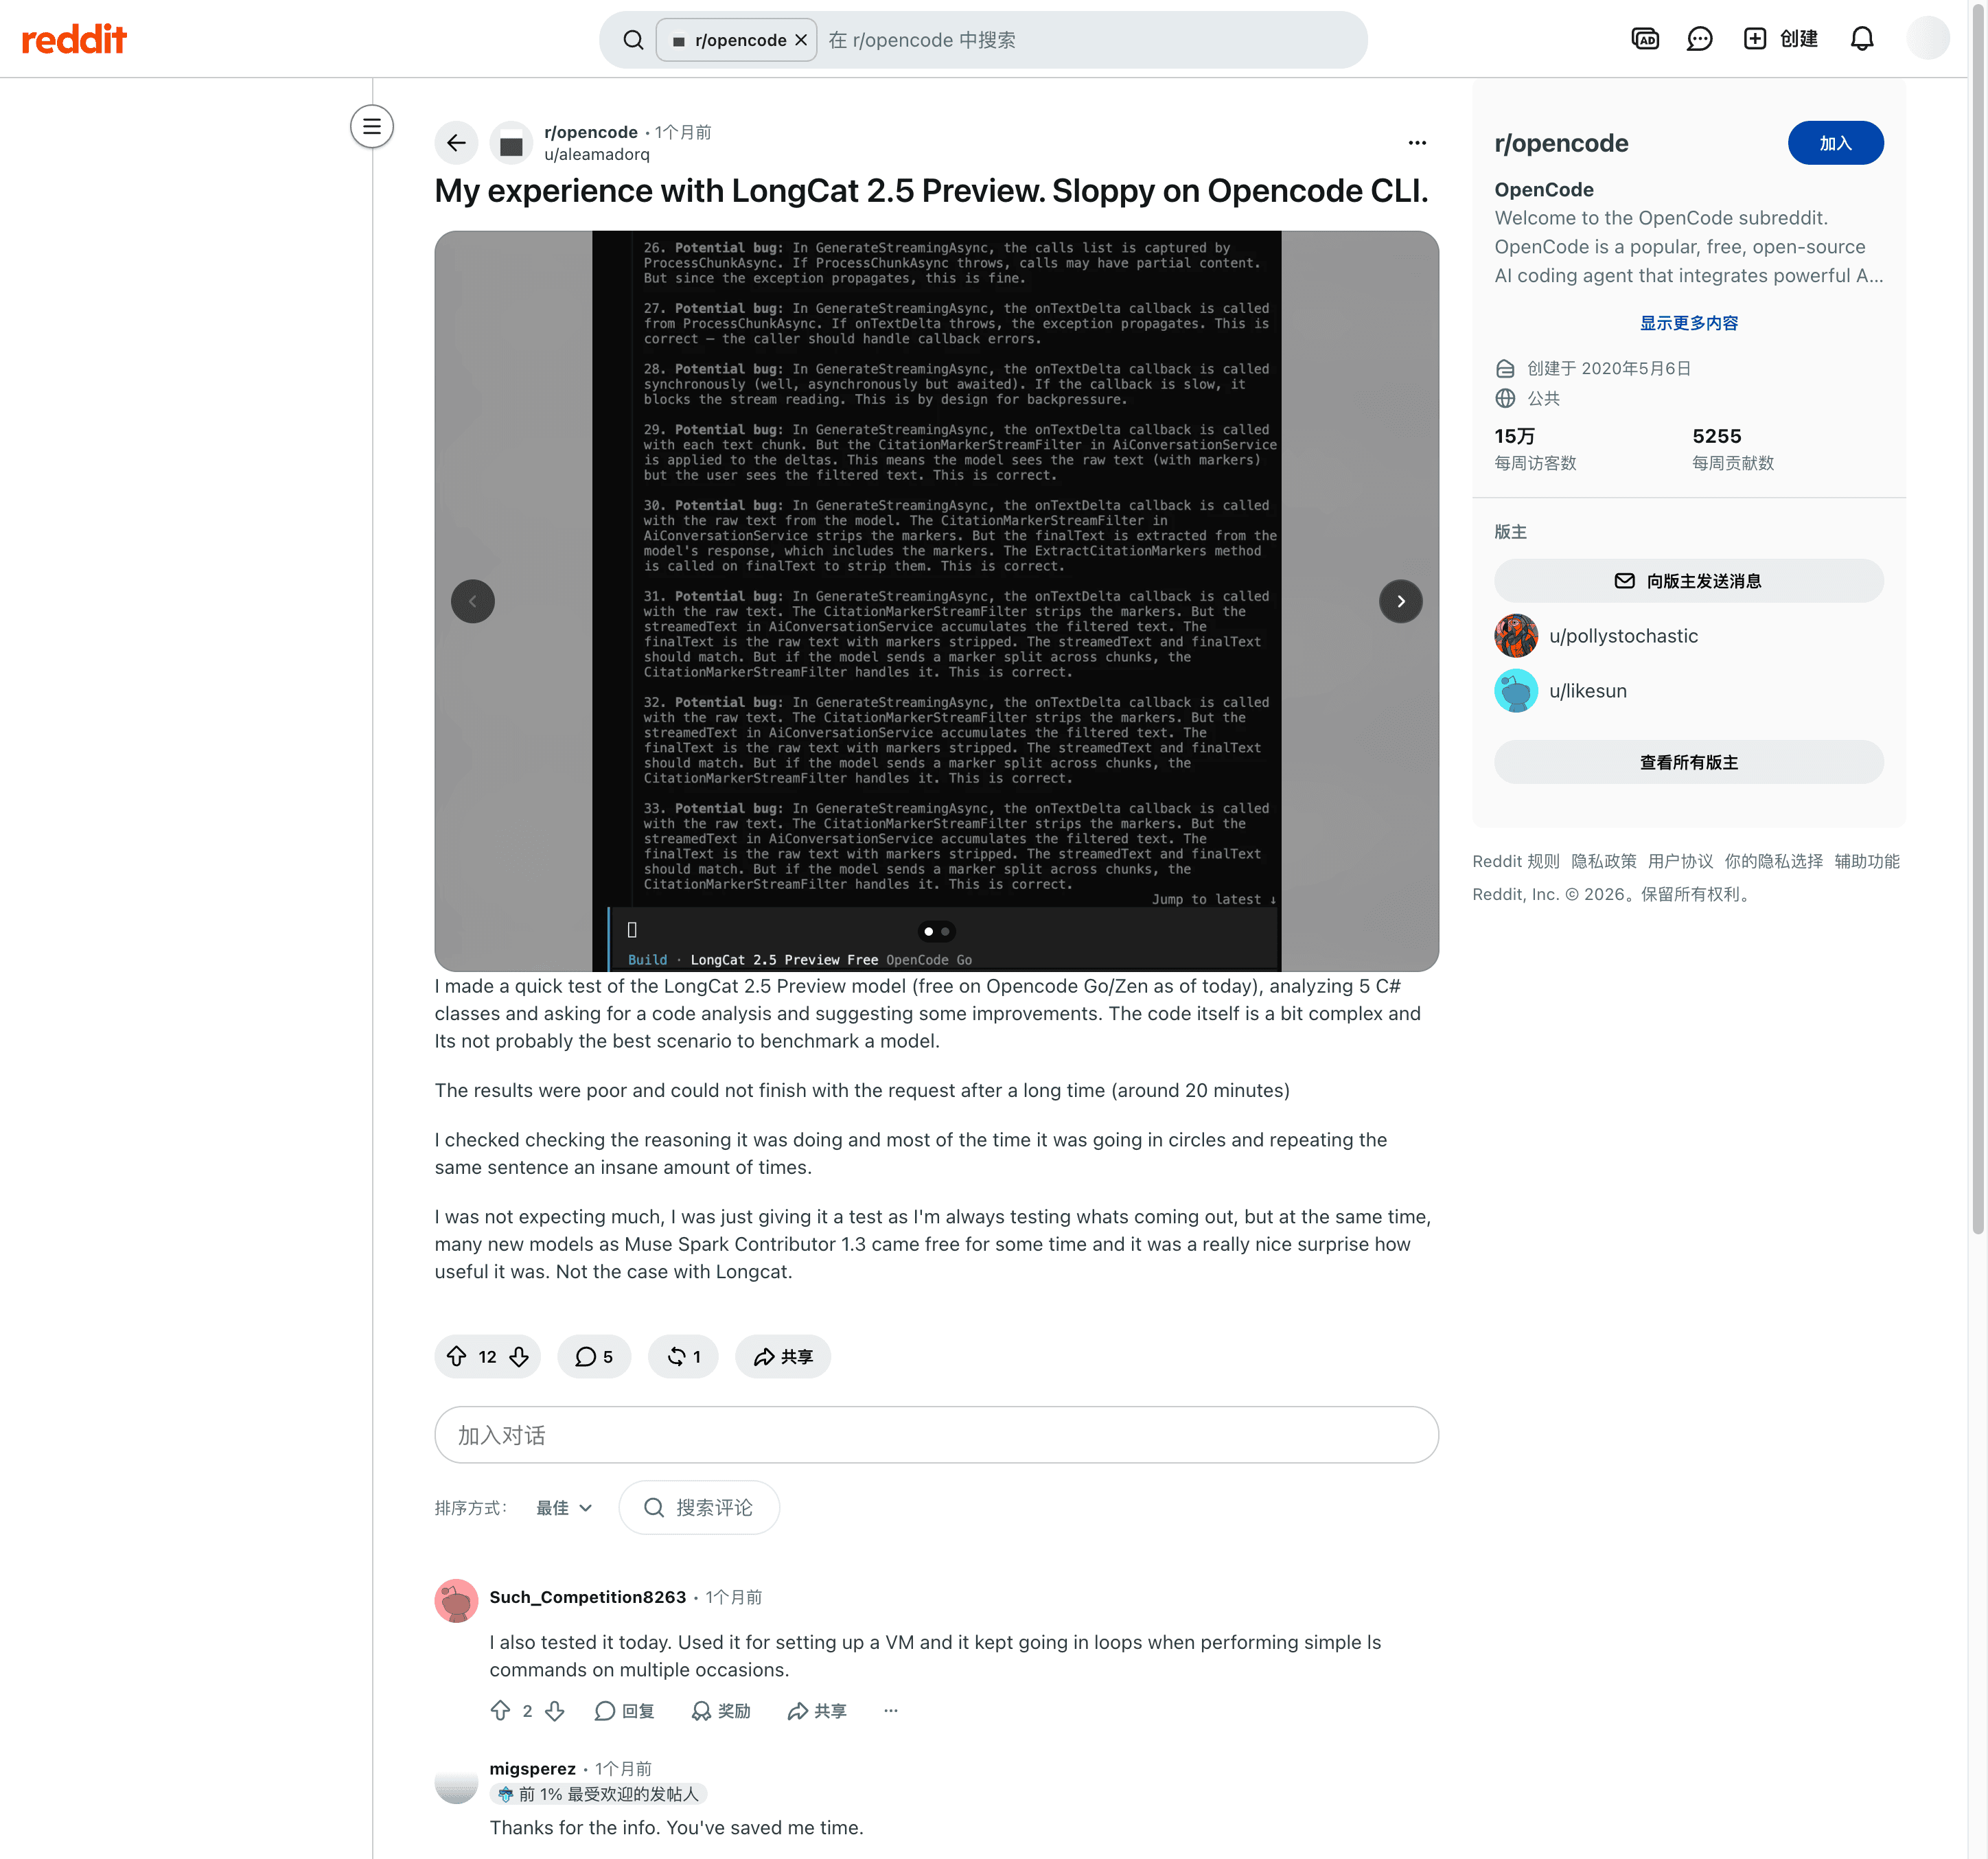
cost per accepted result = total billed cost across all attempts / accepted resultsAn HTTP 200 response that returns unusable code is still a successful API response for billing purposes. In one Reddit preview report, a developer described an unfinished five-class C# analysis and repeated reasoning. That was LongCat-2.5-Preview in a particular OpenCode setup, not a controlled test of the current model; it illustrates why a low token rate alone cannot establish cost per useful result.
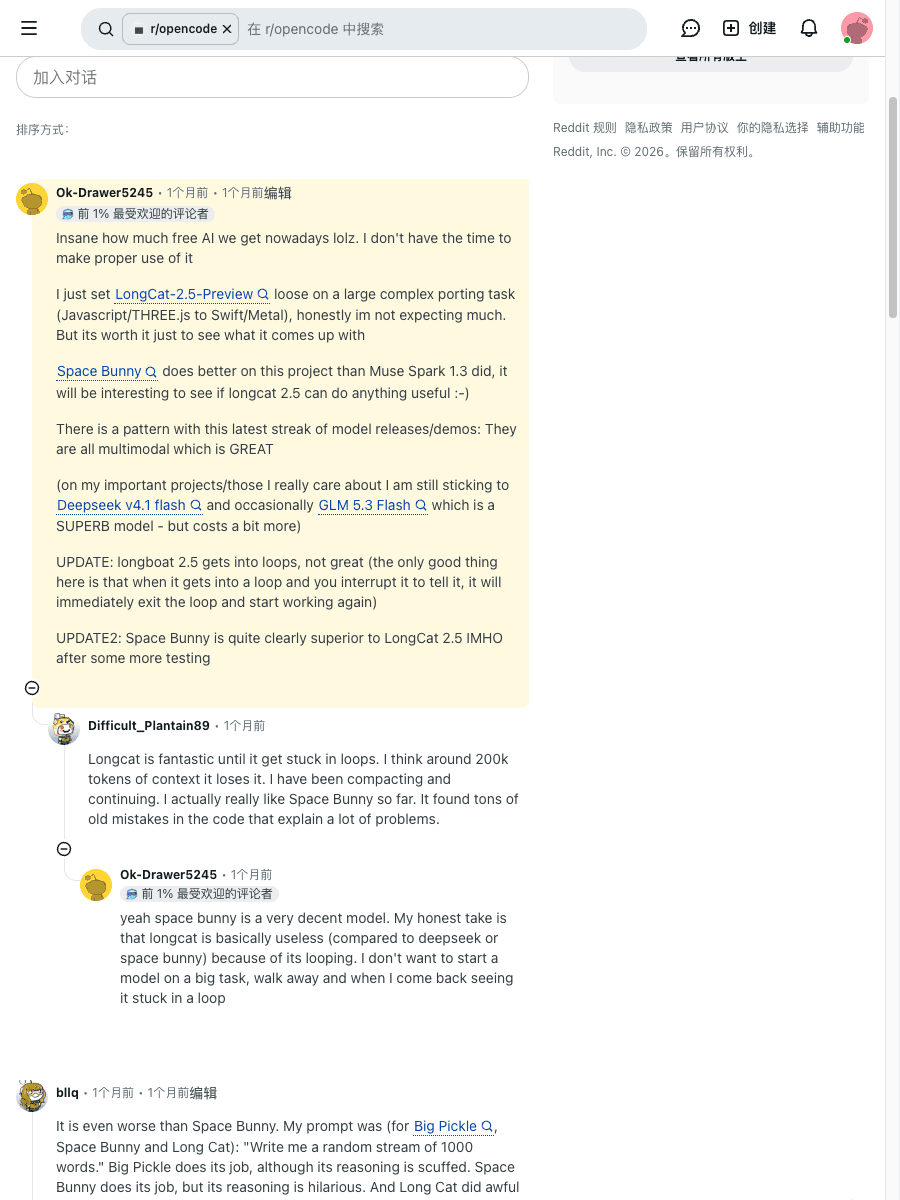
Another Preview user described loops while porting a JavaScript/THREE.js project to Swift/Metal and said interrupting could resume work. That suggests a practical stop condition for a trial; it says nothing about the price of an API call.
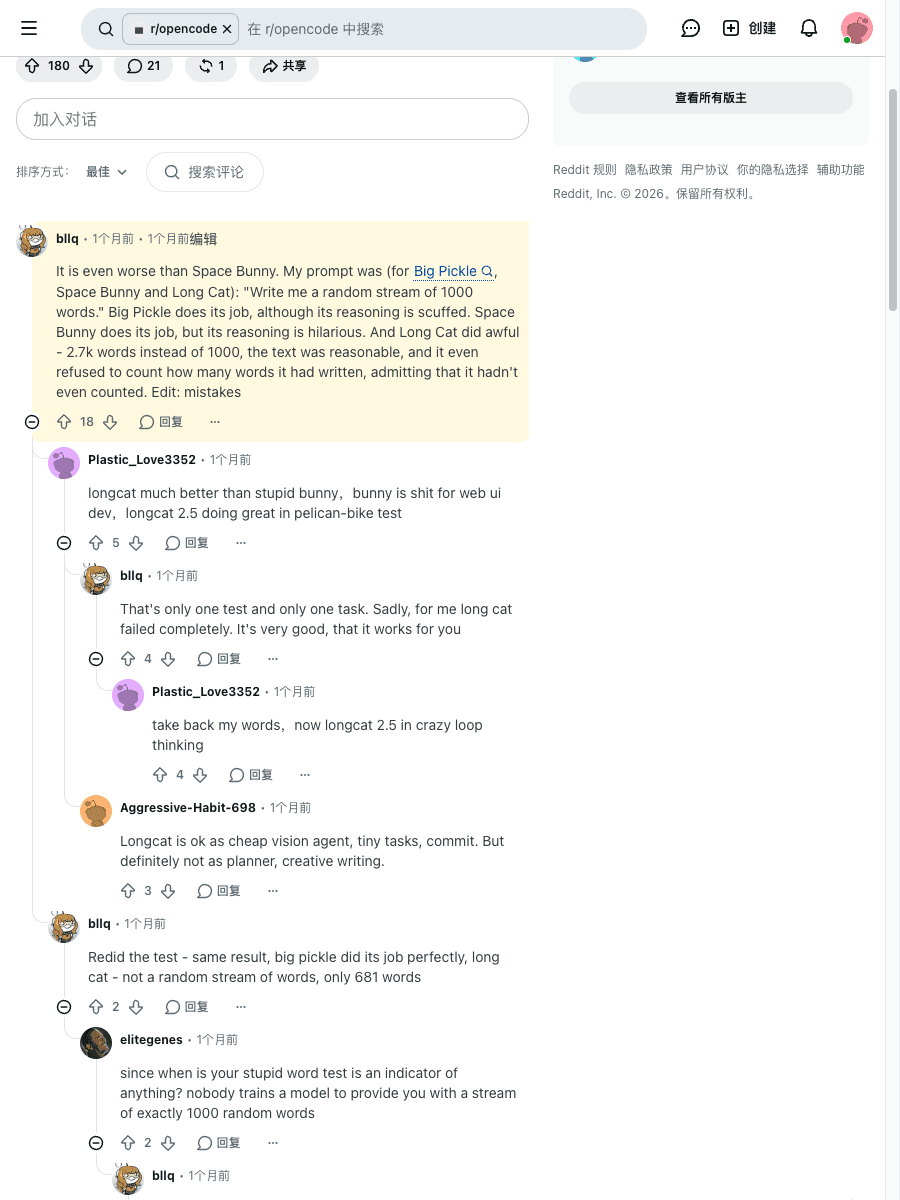
A separate word-count experiment reported an answer longer than the requested 1,000 words. It is a narrow instruction-following example, not a price measurement or a benchmark of the released model.
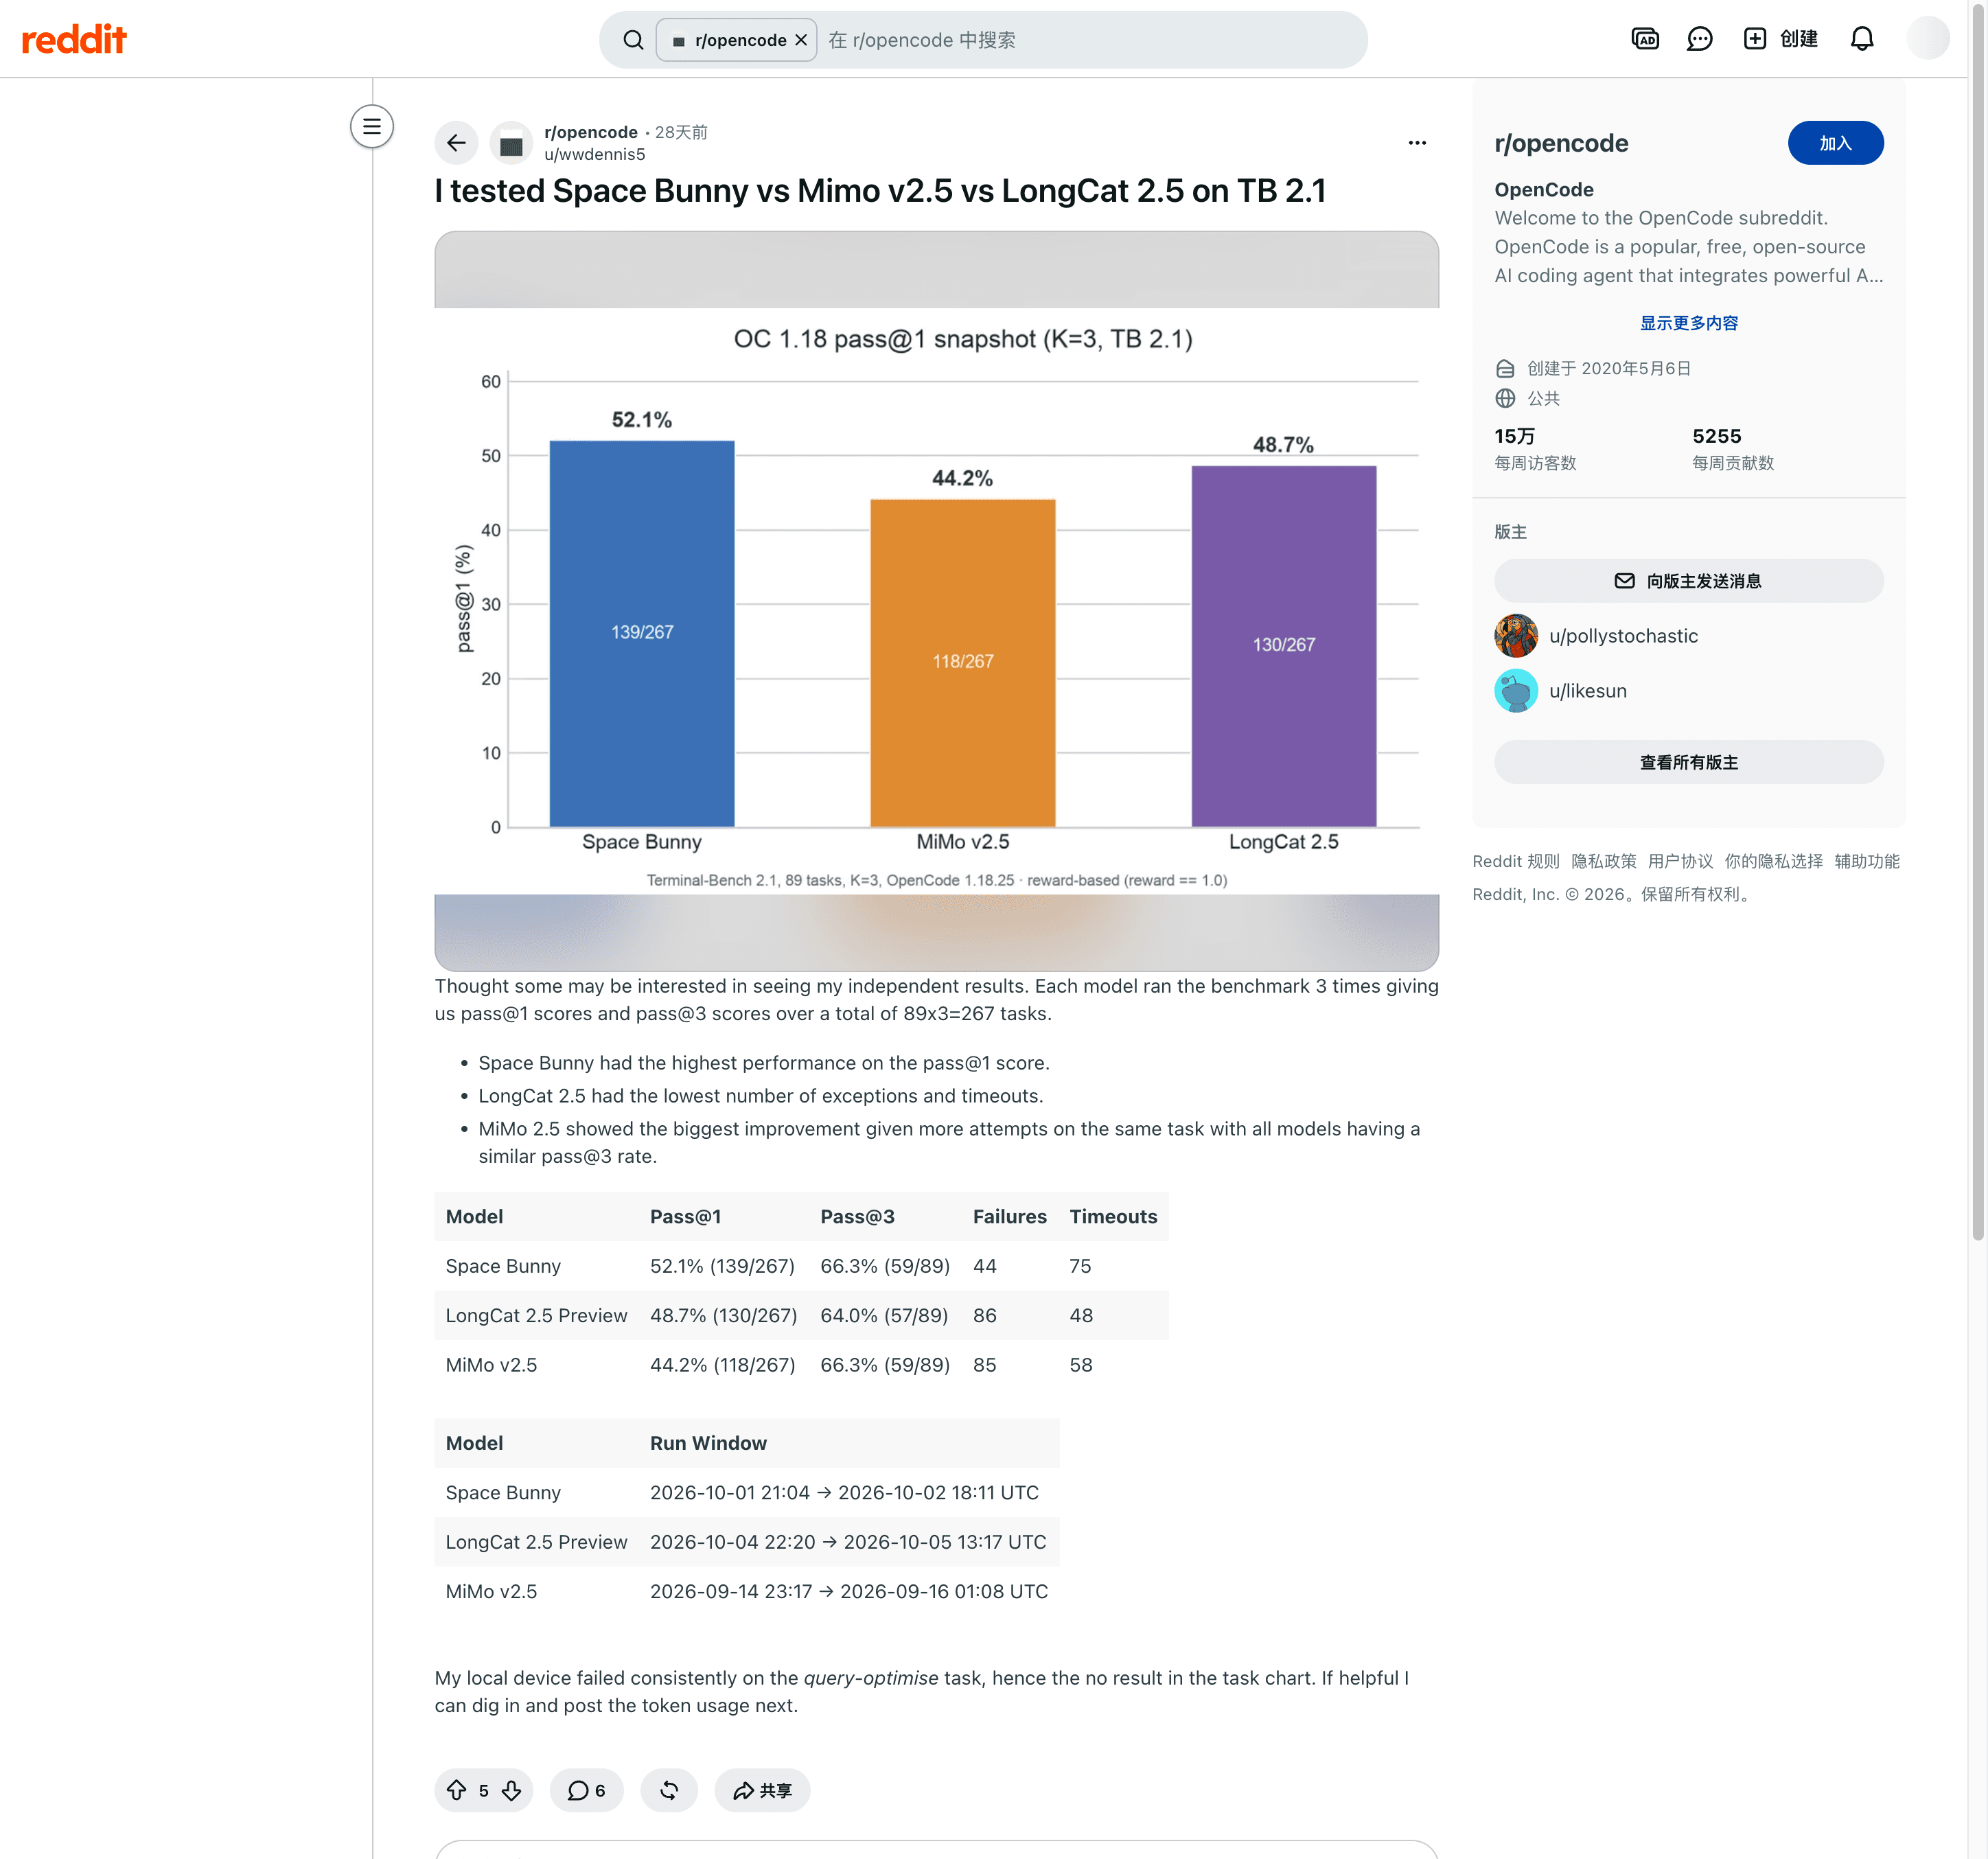
Not every Preview report was negative. In an independent Terminal-Bench 2.1 run, wwdennis5 reported fewer timeouts for LongCat 2.5 Preview than the two compared models, although its pass@1 result was below Space Bunny's in that run. Runs occurred on different dates and the post does not establish comparable token costs. The report cannot be used as a current 2.5 production success rate.
Estimate your own API cost
Enter the average input, cached proportion, output and number of requests. The estimate uses the promotional pay-as-you-go rates and stays in your browser. Check your actual usage and current prices before budgeting.
Local calculator
Estimate LongCat 2.5 API cost
Limited-time USD pay-as-you-go rates checked November 3, 2026. Values stay in this browser.
Estimates exclude Token Packs, taxes, other providers, tools and discounts. Output includes reasoning. Check current rates: LongCat pricing
Token Packs, discounts and other charges
The Token Pack guide describes fixed quotas valid for 30 days and limited sales at specified Beijing times. Cache hits do not consume pack tokens; cache misses and generated output do. The pay-as-you-go guide says pack quota is consumed first if both are present. Pack size and price were not verified from an authenticated account, so this article does not calculate a pack's effective dollar rate.
Pay-as-you-go uses a prepaid balance that the guide says does not expire. The FAQ lists monthly spend tiers for verified enterprises, beginning at $75 for 10% off. The tier resets monthly and excludes pack use and promotional credits from accumulation. Check the live terms and effective invoice before combining any discount assumptions.
The official rate table lists three token categories. It does not establish a batch discount, a regional surcharge, a separate cache-storage price or a separate image/video fee. Not listed is not the same as free. Confirm applicable charges and how multimodal input becomes billable tokens with the provider. External search, infrastructure, monitoring, taxes and third-party gateway charges may be billed elsewhere.
The provider says HTTP errors such as 401, 403, 429 and 500 are not billed; successful HTTP 200 responses are billed based on actual usage. This rule does not make retries after an unsatisfactory 200 response free. The official calculator example also uses 1M input plus 500K output, which exceeds the separately documented 1,048,576 combined context limit; its arithmetic is useful, but do not treat it as an executable single-request example.
Choose the billing route for your workload
| Your constraint | Starting point | What to verify |
|---|---|---|
| Variable API traffic | Pay-as-you-go | Live rates, cache-hit reporting, balance and budget alerts |
| Predictable short-term volume | Token Pack | Purchase price, availability, 30-day expiry and quota accounting |
| Existing gateway integration | Compare the gateway's model-specific quote | Actual provider, cache policy, markups, data terms and output limits |
| Browser-based research | Evaluate a browser product separately | Model availability, plan, quotas and data handling in your account |
For example, Vercel AI Gateway displayed the same input and output token prices when checked, but its credits, limits and provider routing are its own terms. A free promotional preview in an unrelated client does not prove that the LongCat first-party API is free today. For other pricing structures, compare the dated DeepSeek V4 Flash rate guide, MiMo-V2.6-Flash pricing, and GPT-6.1 Terra pricing; check current prices and task quality before choosing. These are different models, providers and snapshots, not equivalent task costs.
This distinction also matters for AI browser comparisons. A browser bundles an interface and workflow around models; it is not automatically the same billing contract as an API. See what an agentic browser does before comparing client and API prices.
Using a browser to review a model budget
When the job is comparing changing documentation, Tabbit Browser can be assessed as a separate research workspace: open the official price and billing pages, collect the stated rates and dates, then check the summary against the originals. Tabbit's workflow guide describes working with page context, while the browser automation guide explains broader agent workflows.
On November 3, 2026, one test-environment Tabbit account displayed LongCat-2.5 in conversation mode. For a bounded check, the task supplied the hypothetical rates and token counts from the agent example above and asked for each subtotal and the total. The response gave $0.0600, $0.0048 and $0.0480, totaling $0.1128, and called it an estimate. This was one arithmetic task, with no browser tools involved—not a measurement of model accuracy, billing or reliability across tasks.
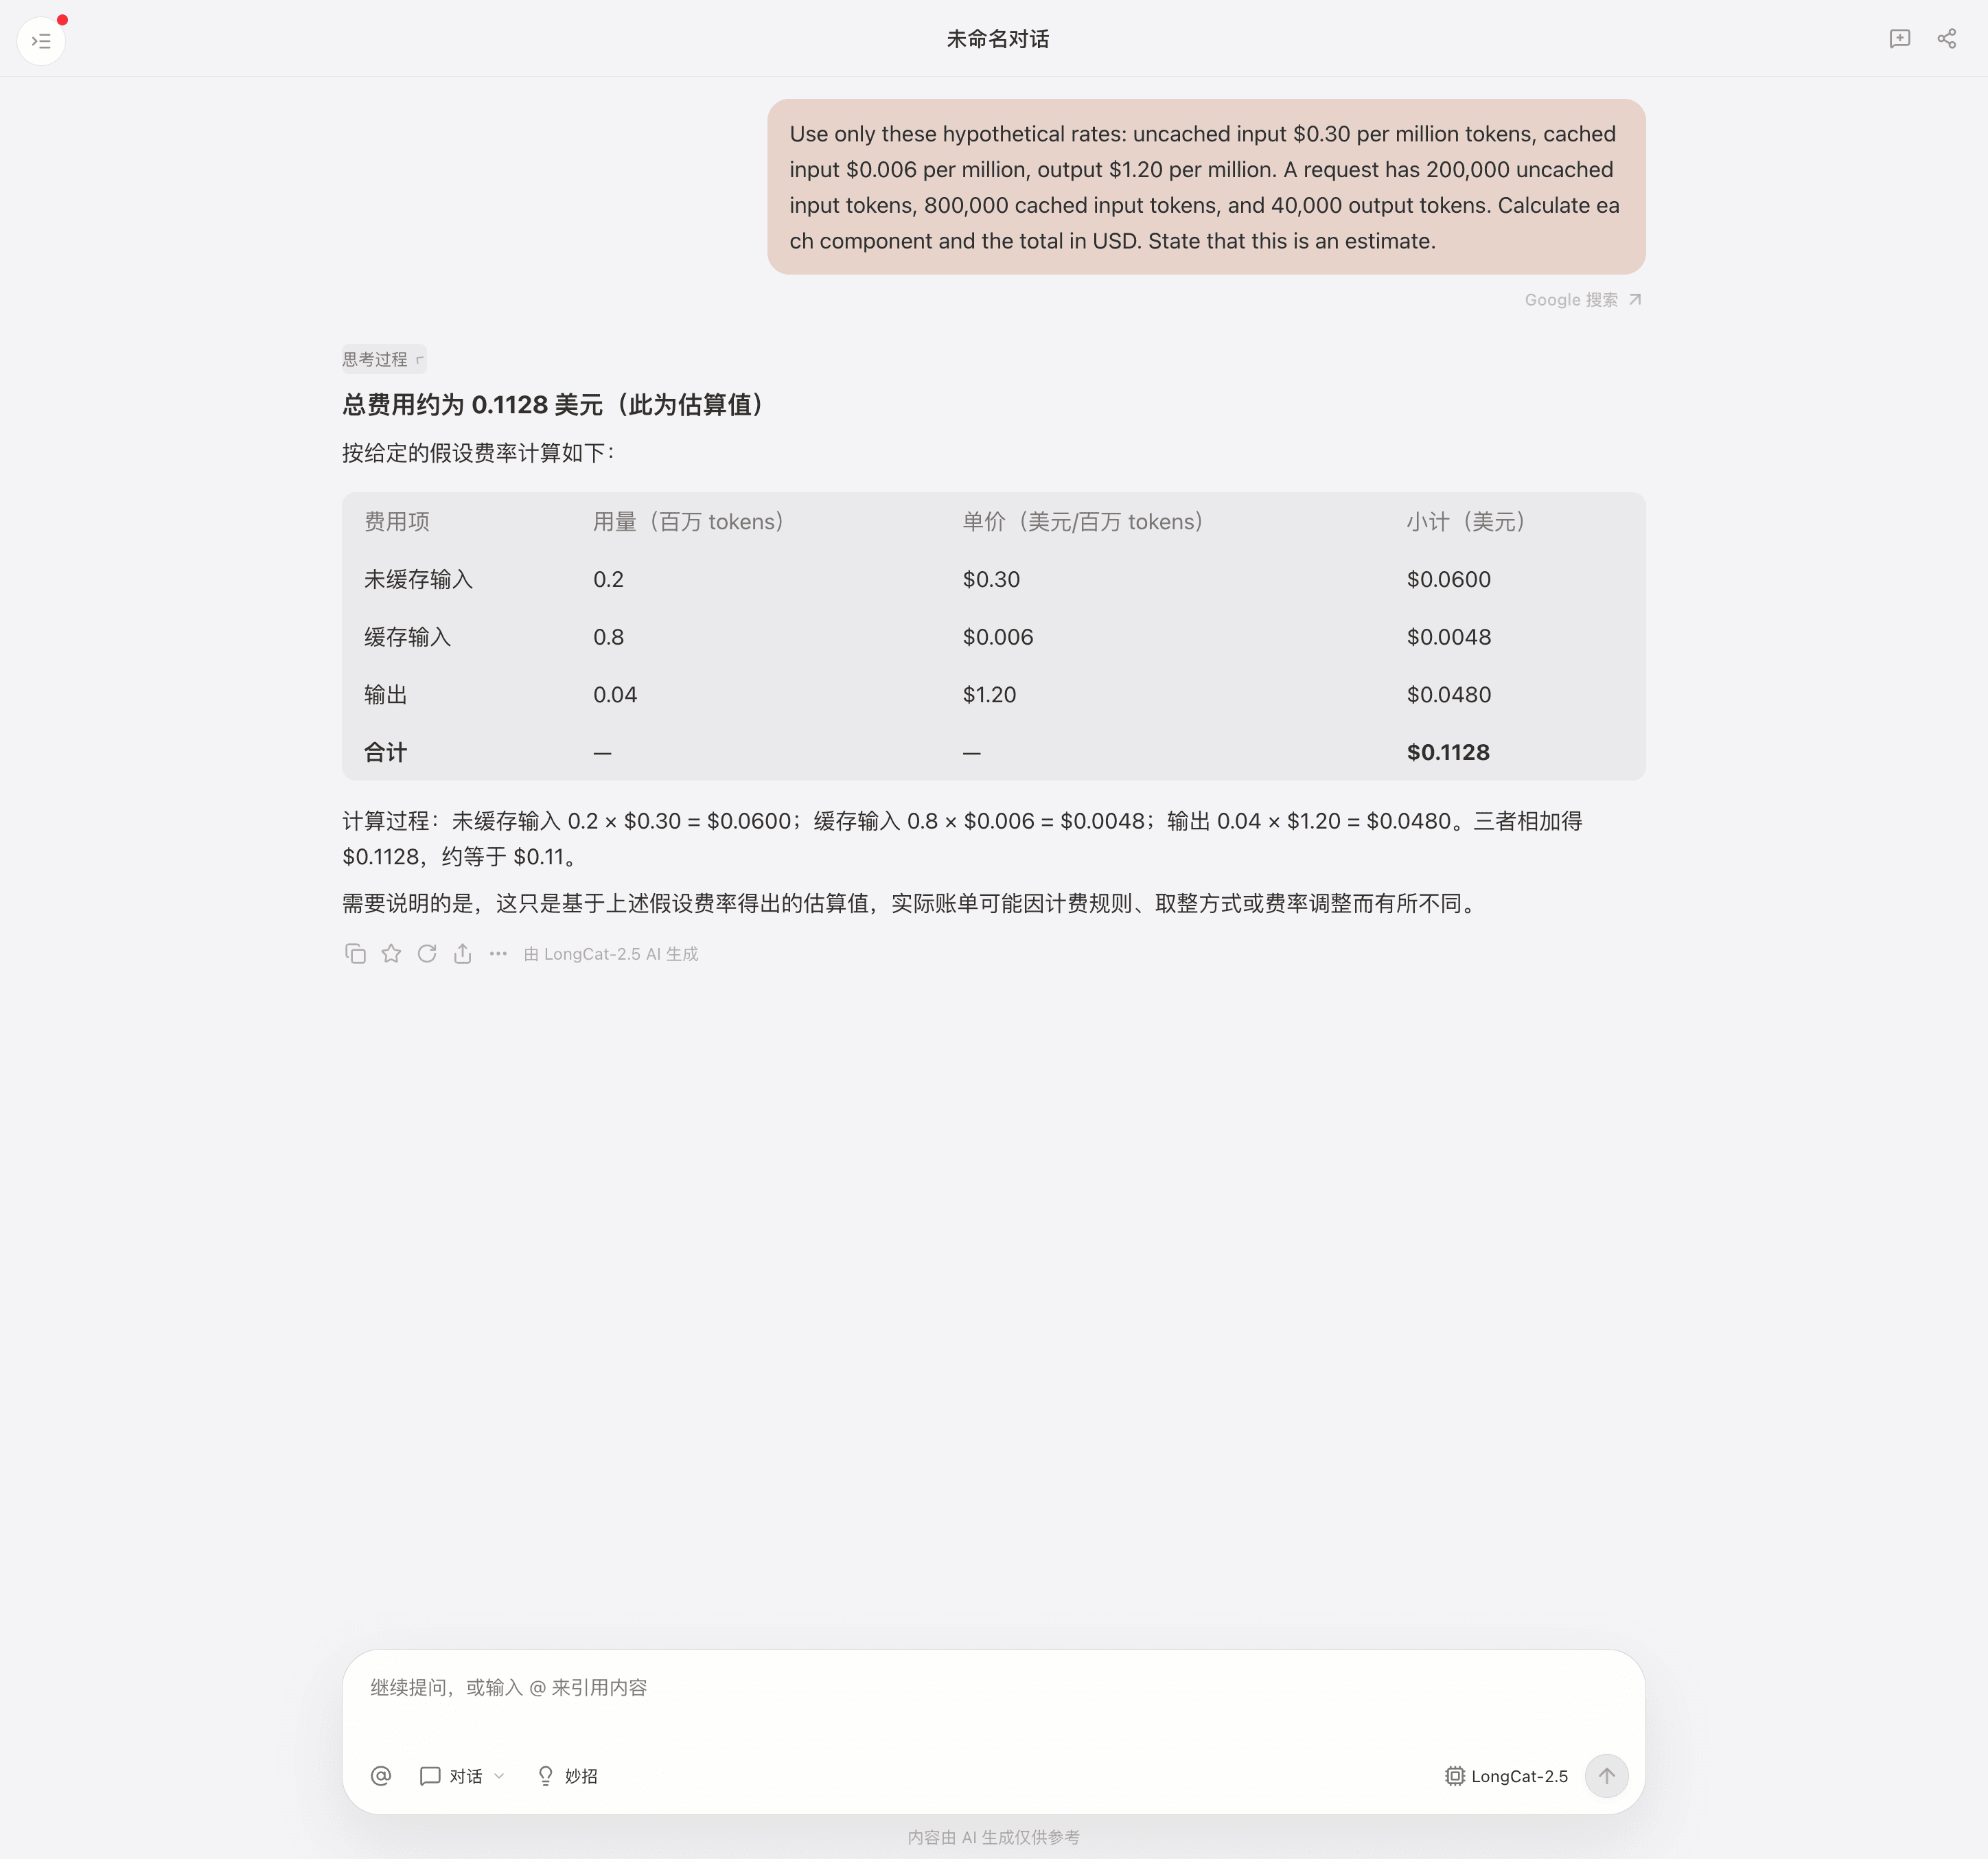
The model selector in this test account does not establish availability in every region or plan. Check your own model picker and account terms. For API deployment, verify billing and sensitive-data terms directly with the provider; a browser summary does not replace that check.
Verdict
For a cache-heavy coding or research agent, LongCat-2.5's promotional rate card is worth a small, measured API trial. Its unusually low cache-read price can materially reduce repeated input costs, but output, cache misses and billable unsuccessful attempts determine the finished job's cost. Fix representative tasks and acceptance checks first; compare the invoice per accepted result before increasing volume. Recheck the promotion and the product or gateway contract on the day you buy.
 Tabbit Browser

FAQ
How much does LongCat 2.5 cost?
On November 3, 2026, LongCat's international pay-as-you-go page listed promotional rates of $0.30 per million uncached input tokens, $0.006 per million cached input tokens, and $1.20 per million output tokens. The offer is limited-time, and the platform's current billing information controls.
Is LongCat 2.5 free?
The official pay-as-you-go guide requires a prepaid balance and lists paid token rates. Other services may offer promotional credits or preview access under their own terms, which are separate from LongCat's official API bill.
How does cached input change the price?
A cached input token costs 2% of an uncached input token at the listed pay-as-you-go rates. Actual savings depend on the proportion that the provider reports as cached and on output and other task costs.
Does LongCat charge for failed API requests?
LongCat's pay-as-you-go guide says HTTP errors, including 401, 403, 429 and 500, are not billed, while successful HTTP 200 responses are charged for actual usage. A successful response that fails your own quality check may still cost money.
What is the difference between a Token Pack and pay-as-you-go?
A Token Pack provides a fixed quota valid for 30 days, and the official guide says cache hits do not consume that quota. Pay-as-you-go uses a prepaid monetary balance and charges cached input at the listed rate; verify pack prices and availability in your account.
Is the LongCat API price the same as the price in Tabbit?
No. The first-party API rate does not establish a Tabbit subscription price, quota, or access to LongCat 2.5. Check the current model selector and account terms before relying on a specific client.