
Claude Fable 5.1 costs $10 per million input tokens and $50 per million output tokens on the Anthropic API, with cache reads at $0.25 per million — every rate checked on Anthropic's own pricing docs on September 22, 2026. That is the rate card, and it is almost boring: of the five token lines, four did not move from Fable 5. The bill is a different object. On the same rate card, Artificial Analysis measures one benchmark task at $2.37 at low effort and $7.63 at max — a 3.2x swing before you touch a single price line, and a separate measurement puts Fable 5.1 at 18% more per task than Fable 5 despite the "up to 45% cheaper" launch claim.
Both of those sentences are true, and the gap between them is why this article exists. An r/LLMDevs post put the real question precisely: GPT-6 Astra and Fable 5.1 "list at the same price. They do not cost the same" — because the shape of your traffic, not the sticker, decides the invoice (r/LLMDevs). This page is the money side of our Claude Fable 5.1 overview and review; later in the guide, Tabbit Browser appears as one practical place to run these comparisons once the budget is clear. First, the numbers.
Key takeaways
The rate card: $10 input, $0.25 cache reads (0.025x — a family-wide exception), $12.50/$20 cache writes (5m/1h), $50 output per million tokens. Batch halves everything; US-only inference adds 1.1x to every line.
One line changed, everything else is bill shape. Cache reads fell 75% from Fable 5's $1.00. Anthropic estimates typical savings of ~25% and agentic savings up to ~45%; independent measurements realized 15–30%, and one carefully logged community build cost 2.4x more than Fable 5.
Effort is the biggest controllable lever. AA's ladder runs $2.37 → $7.63 per task across low → max effort, for 47 → 53 intelligence points. Fable defaults to High in Claude Code and Medium elsewhere — check what you are actually paying for.
No long-context cliff. The full 1M-token window bills at standard rates — unlike flagships that reprice long prompts — but the newer tokenizer produces ~30% more tokens for the same text.
Subscriptions are a separate economy. Fable is not on Free; Pro/Max meter it as usage credits at 50% of weekly limits inside rolling 5-hour windows. Enterprise is $20/seat plus usage at API rates.
Claude Fable 5.1 pricing at a glance
The full standard rate card, rendered from Anthropic's pricing docs on September 22, 2026. Mythos 5.1 — the same weights behind a restricted access program — lists identically but is not generally purchasable; the overview page covers that lineage.
| Model | Input / 1M | 5m cache write / 1M | 1h cache write / 1M | Cache read / 1M | Output / 1M |
|---|---|---|---|---|---|
| Claude Fable 5.1 | $10.00 | $12.50 | $20.00 | $0.25 | $50.00 |
| Claude Fable 5 | $10.00 | $12.50 | $20.00 | $1.00 | $50.00 |
| Claude Opus 5 | $5.00 | $6.25 | $10.00 | $0.50 | $25.00 |
| Claude Sonnet 5 | $2.00 | $2.50 | $4.00 | $0.20 | $10.00 |
| Claude Haiku 4.5 | $1.00 | $1.25 | $2.00 | $0.10 | $5.00 |
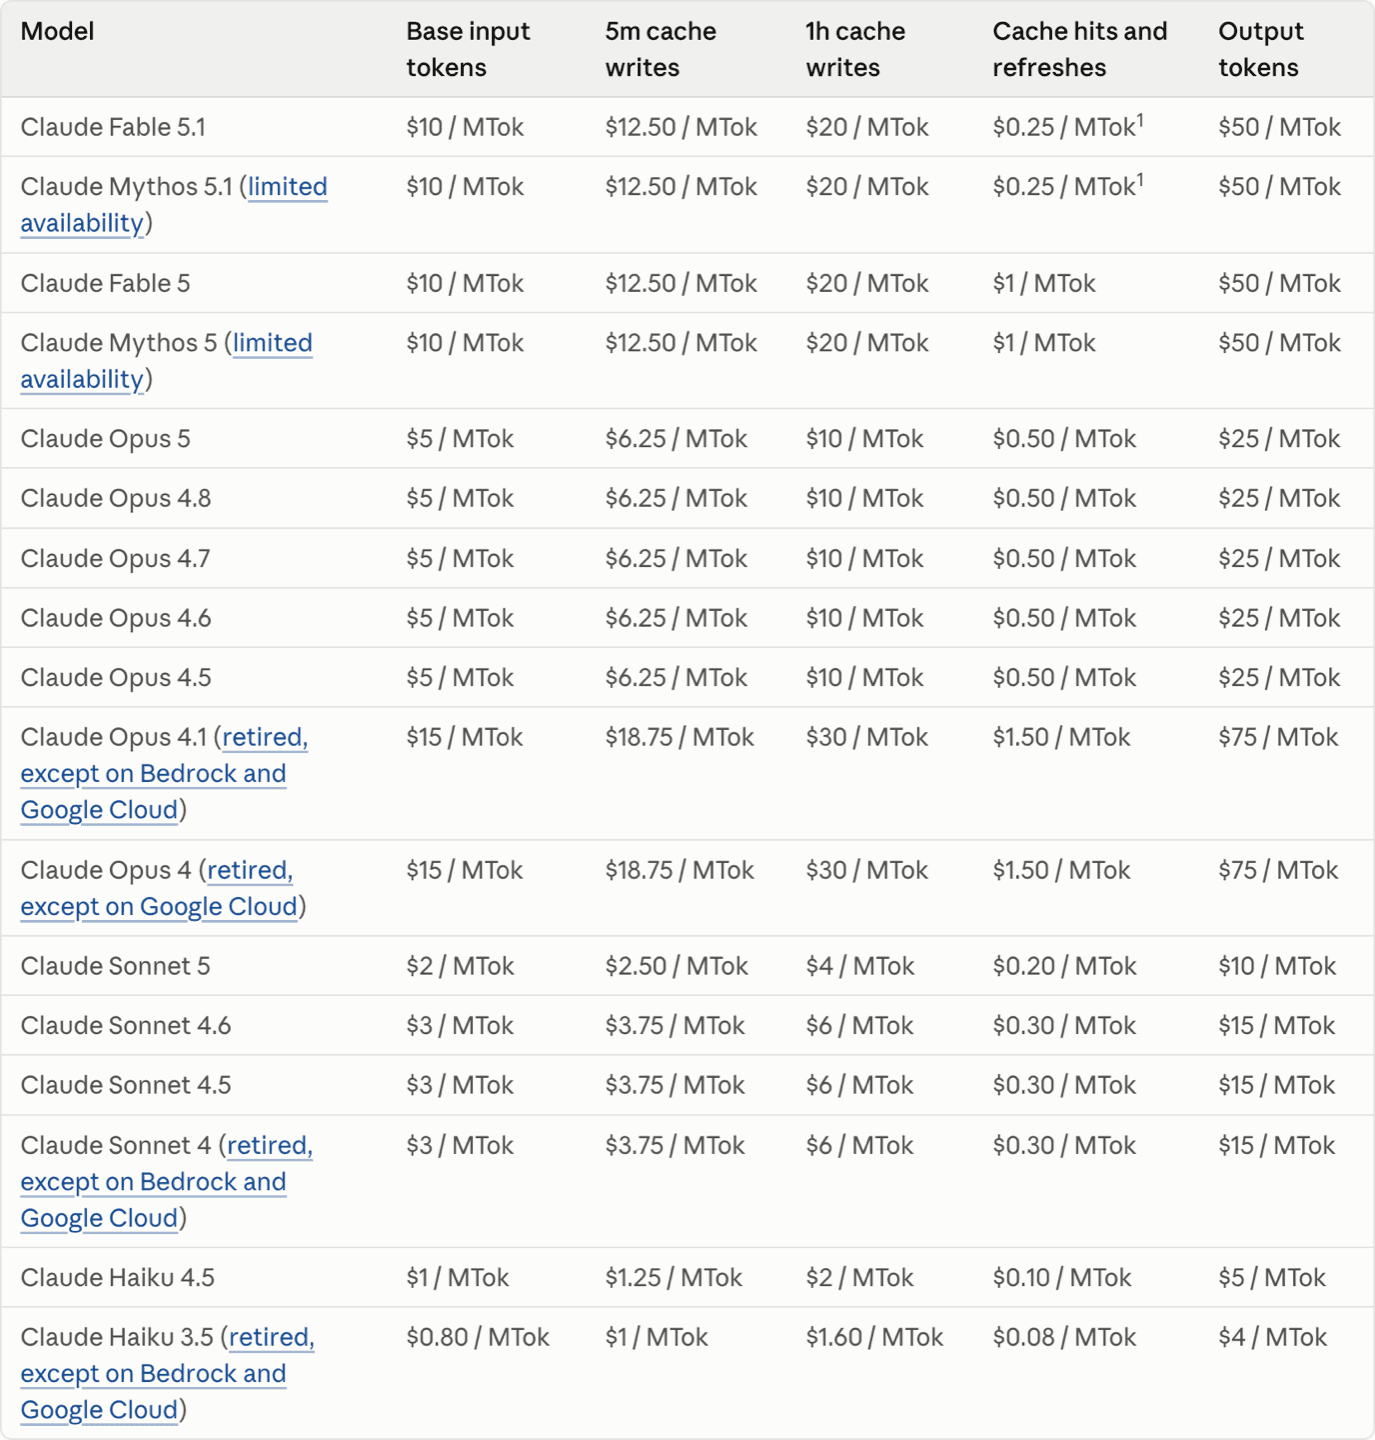
Three things in this table do the damage, and none is the headline $10:
Output is 5x input. Fable is an adaptive-reasoning model; it thinks in billable output tokens. A modest prompt with a long reasoning chain is an output bill wearing an input costume.
Cache writes cost more than input. $12.50 is 1.25x the base rate for a 5-minute entry, $20 (2x) for an hour. Caching pays off after one 5-minute read or two 1-hour reads — but only if the prefix is actually reused.
The tokenizer changed under you. Claude 4.7-and-later models use a newer tokenizer that produces approximately 30% more tokens for the same text, per Anthropic's own footnote. Comparing per-token prices against Sonnet 4.6-era models without this correction overstates the older model's cost by a third.
Also worth pinning: the full 1M-token context window bills at standard rates — "a 900k-token request is billed at the same per-token rate as a 9k-token request," in Anthropic's words. Unlike GPT-6 Astra's 272K cliff, where crossing a threshold reprices the entire request, Fable has no long-context tier at all.
The one number that changed: cache reads fell 75%
Prompt caching is the only line that moved between Fable 5 and Fable 5.1, and it is worth understanding mechanically, because it is the line your agent loops live on.
When a request repeats a previously processed prompt prefix — system prompt, repository context, conversation history, tool definitions — the API can read that prefix from cache instead of reprocessing it. Writes cost 1.25x base input for a 5-minute entry, 2x for a 1-hour entry. Reads normally cost 0.1x base input. Fable 5.1 (and Mythos 5.1) are the family-wide exception: reads cost 0.025x — $0.25 per million — and Anthropic's footnote marks this explicitly. These multipliers stack with the Batch discount and data-residency pricing.
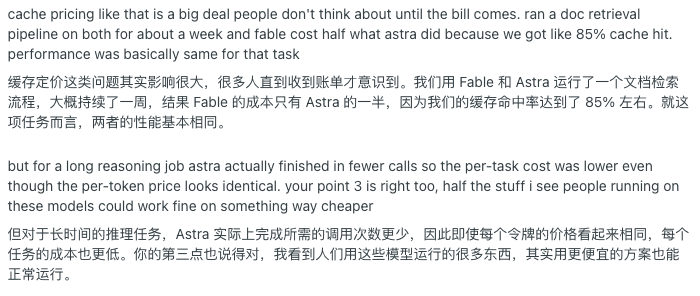
Why this dominates agent bills: an agent that makes 40 tool calls over a 200,000-token context re-reads that prefix 40 times. Under Fable 5's $1.00/M reads, those re-reads cost $8.00; under Fable 5.1's $0.25/M, they cost $2.00 — before a single new token is generated. The community numbers go in the same direction. A developer running a week-long document-retrieval pipeline on both Fable 5.1 and a competing $1.00-read model reported paying roughly half for equivalent output at an 85% cache hit rate:
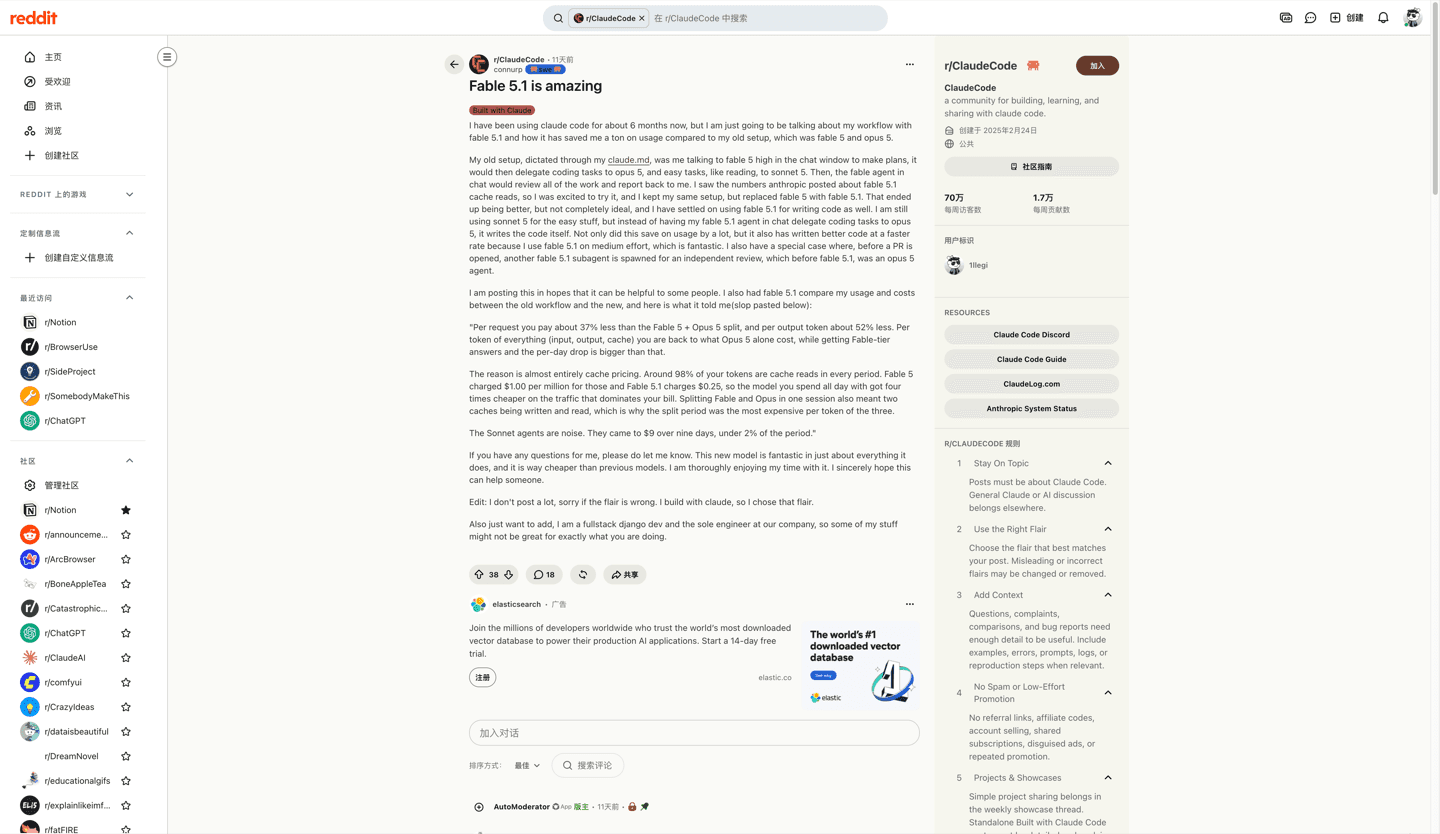
And in r/ClaudeCode, a Django developer who replaced a Fable 5 + Opus 5 split with Fable 5.1 writing code directly at Medium effort calculated about 37% less per request, and 52% less per output token — "the reason is almost entirely cache pricing," in their words:
The catch in both reports: cache savings require a stable prefix. If your context mutates every turn — dynamic tool outputs, rotating documents — you pay the 1.25x–2x write penalty repeatedly instead of riding the 0.025x reads. That failure mode is exactly what the next section measures.
What "up to 45% cheaper" actually means
Anthropic's launch claim has precise conditions, and parsing them is the difference between a budget and a wish. Two caveats worth knowing before you budget.
Caveat one: the baseline and the conditions. "Fable 5.1 will cost an estimated 25% less than Fable 5 for typical workloads, wherever usage is billed by token… For highly agentic work, the savings will often be much larger — up to approximately 45%." The baseline is Fable 5, not competitors. The claim covers token-billed usage, and "highly agentic" means workloads that re-read large stable prefixes — the cache-read shape from the previous section. It is not a promise about your completed-task bill.
Caveat two: independent measurements found the opposite direction. Artificial Analysis measured Fable 5.1 spending 140M output tokens on its Intelligence Index versus Fable 5's 83M, driving cost per task up 18% ($3.14 → $3.69). Firecrawl's 57-run measurement (September 7, 2026) found Fable 5.1 using more output tokens at every effort level — 1.37x at low, 1.12x at high, 1.30x at max — and realized savings of 15–30% of the bill, not 25–45%, "because cache writes cost $20 per million [1-hour] and are not discounted." Their conclusion deserves quoting: "Anthropic says Fable 5.1 is cheaper than Fable 5… Artificial Analysis measured it costing 18% more. Both measured correctly." Which one your bill resembles depends on which token dominates it.
The community found the failure mode in the wild. An r/ClaudeCode developer ran the same build prompt through both models: Fable 5.1 cost $1,200 where Fable 5 cost $500 — 2.4x — on identical headline rates:
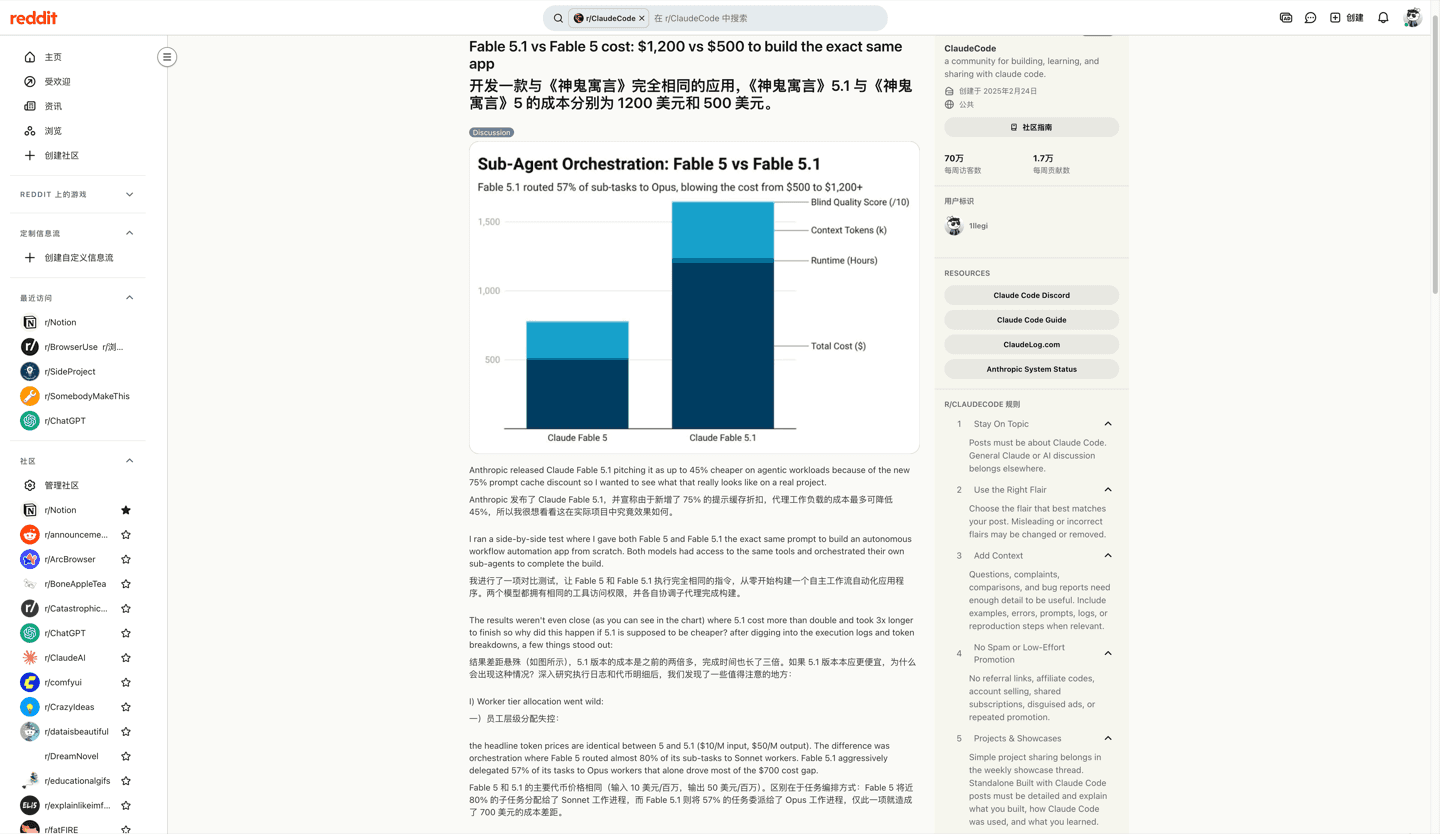
Their autopsy: Fable 5.1 delegated 57% of sub-tasks to Opus workers (billed at Opus rates) where Fable 5 routed 80% to Sonnet, and its reasoning loops bloated active context past 404K tokens — "paying heavy write penalties instead of riding the cheap cache reads." The lesson is not that Fable 5.1 is expensive; it is that delegation tiers and context churn are billing lines that no rate card shows. For the capability side of that trade, see the review and our agentic reasoning guide.
The effort lever: $2.37 to $7.63 per task
Fable 5.1 exposes adaptive reasoning effort — and nothing on the rate card tells you that this dial moves cost more than any price line. Artificial Analysis tracks it as five separate entries; snapshotted September 22, 2026:
| Effort | Intelligence Index | Cost per II task | Output speed |
|---|---|---|---|
| low | 47 | $2.37 | 55 t/s |
| medium | 49 | $2.98 | 57 t/s |
| high | 51 | $3.91 | 56 t/s |
| xhigh | 53 | $5.98 | 63 t/s |
| max | 53 | $7.63 | 67 t/s |
Read the outer columns together: max effort costs 3.2x what low costs per task, for 6 points of measured intelligence. Low also posts the lowest time-to-first-token (8.47s in the same snapshot). The expensive setting is not automatically the careful one; it is the one that thinks longest in billable output tokens — Firecrawl's data shows the gap is almost entirely hidden reasoning (at max effort: reasoning tokens 4,205 → 6,725 while visible text actually fell 6%).
Anthropic's own defaults make this a live decision: Fable 5.1 defaults to High effort in Claude Code, and Medium in Claude Cowork and on Claude.ai. The same task in two surfaces bills differently from the first token. The launch notes are unusually direct that Low or Medium "achieves results similar to or better than Fable 5's at a much lower cost" — a vendor telling you the cheap setting is usually enough is a gift; take it.
The billing lines outside the headline
Four lines decide most real invoices, and only the first appears in launch coverage.
Batch: the 50% lever. Asynchronous Batch requests bill at $5 input / $25 output on Fable 5.1 — the single largest discount on the card, and it stacks with prompt caching. For evaluation runs, overnight refactors, and anything not user-facing, this switch saves more than any prompt optimization. Managed-agent sessions don't qualify (they're stateful and interactive).
US-only inference: 1.1x on everything. Setting inference_geo: "us" — or the equivalent Azure US Data Zone deployment — multiplies every category by 1.1x, cache reads included. Compliance-driven regions pay a quiet 10% premium per line; global routing is the default and the cheaper path.
Tool overheads are token bills. Declaring the browser-use toolset adds about 6,600 input tokens per request; computer-use about 4,500; the bash tool definition 325. Server-side web search bills $10 per 1,000 searches on top of tokens. An "agent" is a pricing structure, not a chat — browser automation workflows should budget the toolset line explicitly.
What Batch and residency don't fix: retries, sub-agent fan-out (each Opus-routed sub-task bills at Opus rates), and the tokenizer's ~30% token inflation versus pre-4.7 models. None appear on the rate card; all appear on the invoice.
The family ladder: Fable 5.1 vs Opus 5 vs Sonnet 5
| Line (per 1M tokens) | Fable 5.1 | Opus 5 | Sonnet 5 |
|---|---|---|---|
| Input | $10.00 | $5.00 | $2.00 |
| Cache read | $0.25 (0.025x) | $0.50 (0.1x) | $0.20 (0.1x) |
| Output | $50.00 | $25.00 | $10.00 |
| Batch input / output | $5.00 / $25.00 | $2.50 / $12.50 | $1.00 / $5.00 |
The counterintuitive row is the cache read: the most expensive model in the family has the cheapest cache read — 4x below the family's own standard multiplier. Anthropic priced the exact billing line that agent loops hammer the hardest at its lowest ratio. If your traffic re-reads big stable contexts, Fable's effective input price collapses; if it doesn't, Opus 5 at half the headline and double the cache-read ratio may win — Firecrawl found tight-spec tasks cheaper on Opus 5 "every time," while open-ended builds averaged $11.83 on Opus versus $7.00 on Fable 5.1.
Two more ladder facts worth pinning: Sonnet 5's $2/$10 was introductory through August 31, 2026 — Anthropic has now made it the standard price, cancelling the scheduled increase to $3/$15. And the same-list-price trap crosses families: Fable 5.1 and GPT-6 Astra both list $10/$50, yet cost opposite amounts in practice — Astra finishes long single tasks in fewer tokens, while Fable's $0.25 reads win any high-volume cached-context workload. The r/LLMDevs analysis that framed it:
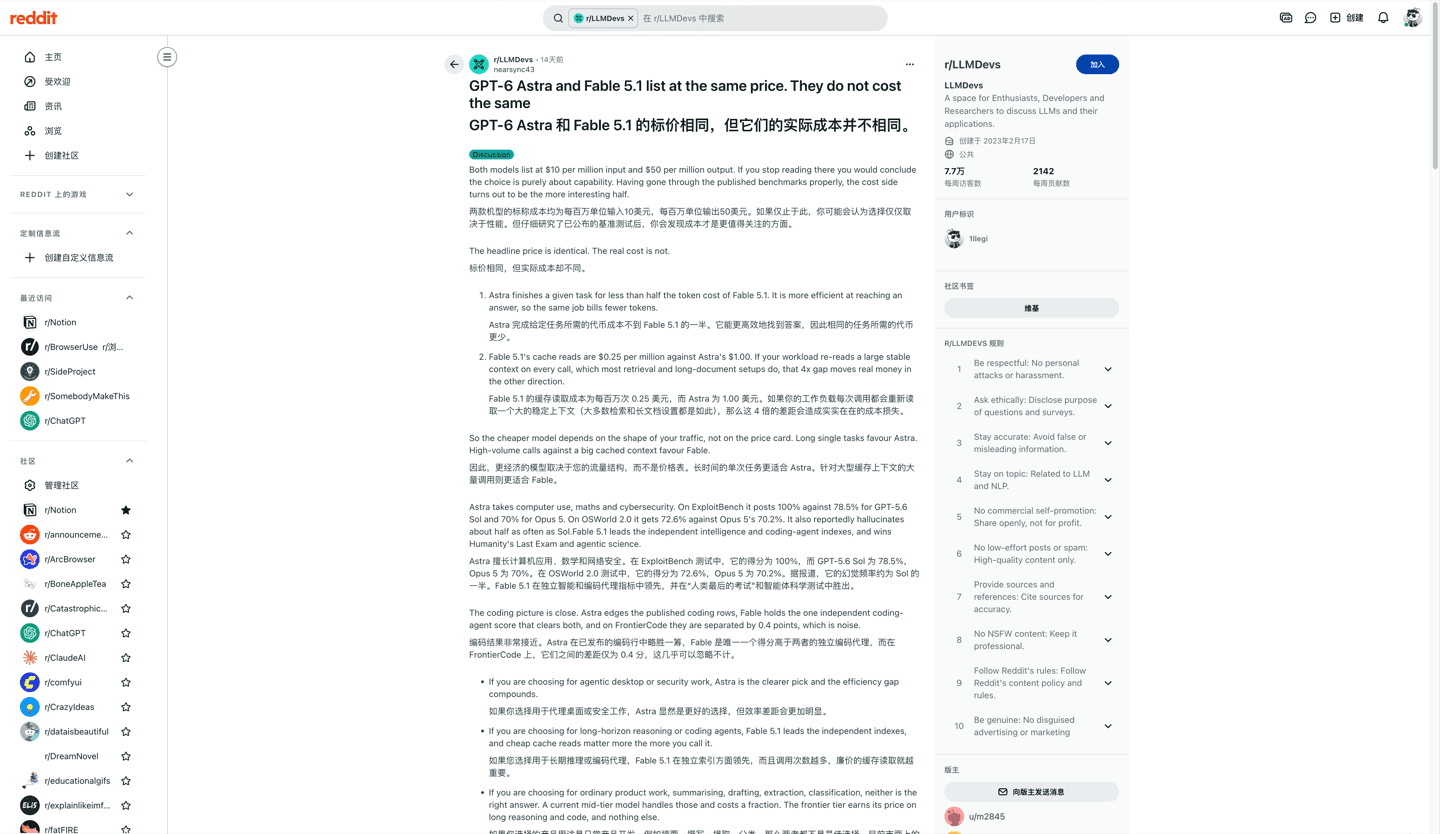
Anthropic's own positioning matches the ladder: Fable 5.1 for "ambitious, long-running, asynchronous work" — the review covers where that holds — with Opus and Sonnet for everyday interactive work.
What you do not pay for
The pricing docs and product page draw a few boundaries that read like refund policy, and they matter at agentic scale:
Safeguard reroutes don't bill at Fable prices. Queries flagged by cybersecurity or biology safeguards are completed by Opus 4.8 or Opus 5 — "You won't be charged Fable prices for rerouted requests," per the product page. A refused-feeling answer on a security topic may literally be a cheaper Opus answer.
Failed web searches are not billed. Each successful search bills $10 per 1,000; errored ones don't. Web fetch adds no charge beyond the tokens the fetched content becomes.
Code execution is free alongside search/fetch, and every organization gets 1,550 free container-hours monthly before the $0.05/hour rate starts.
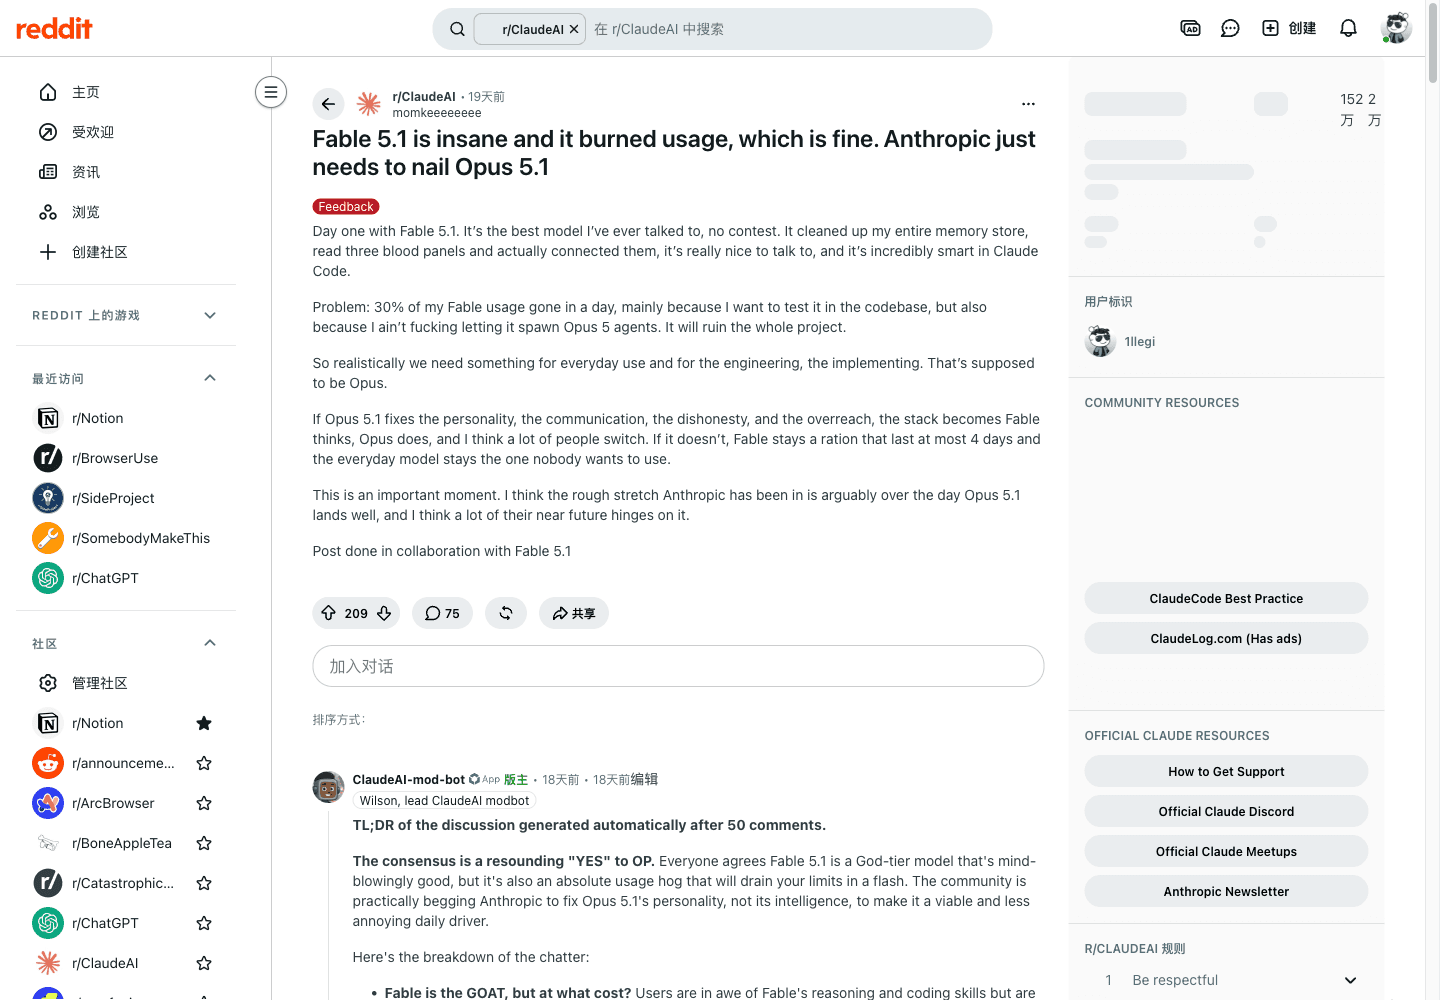
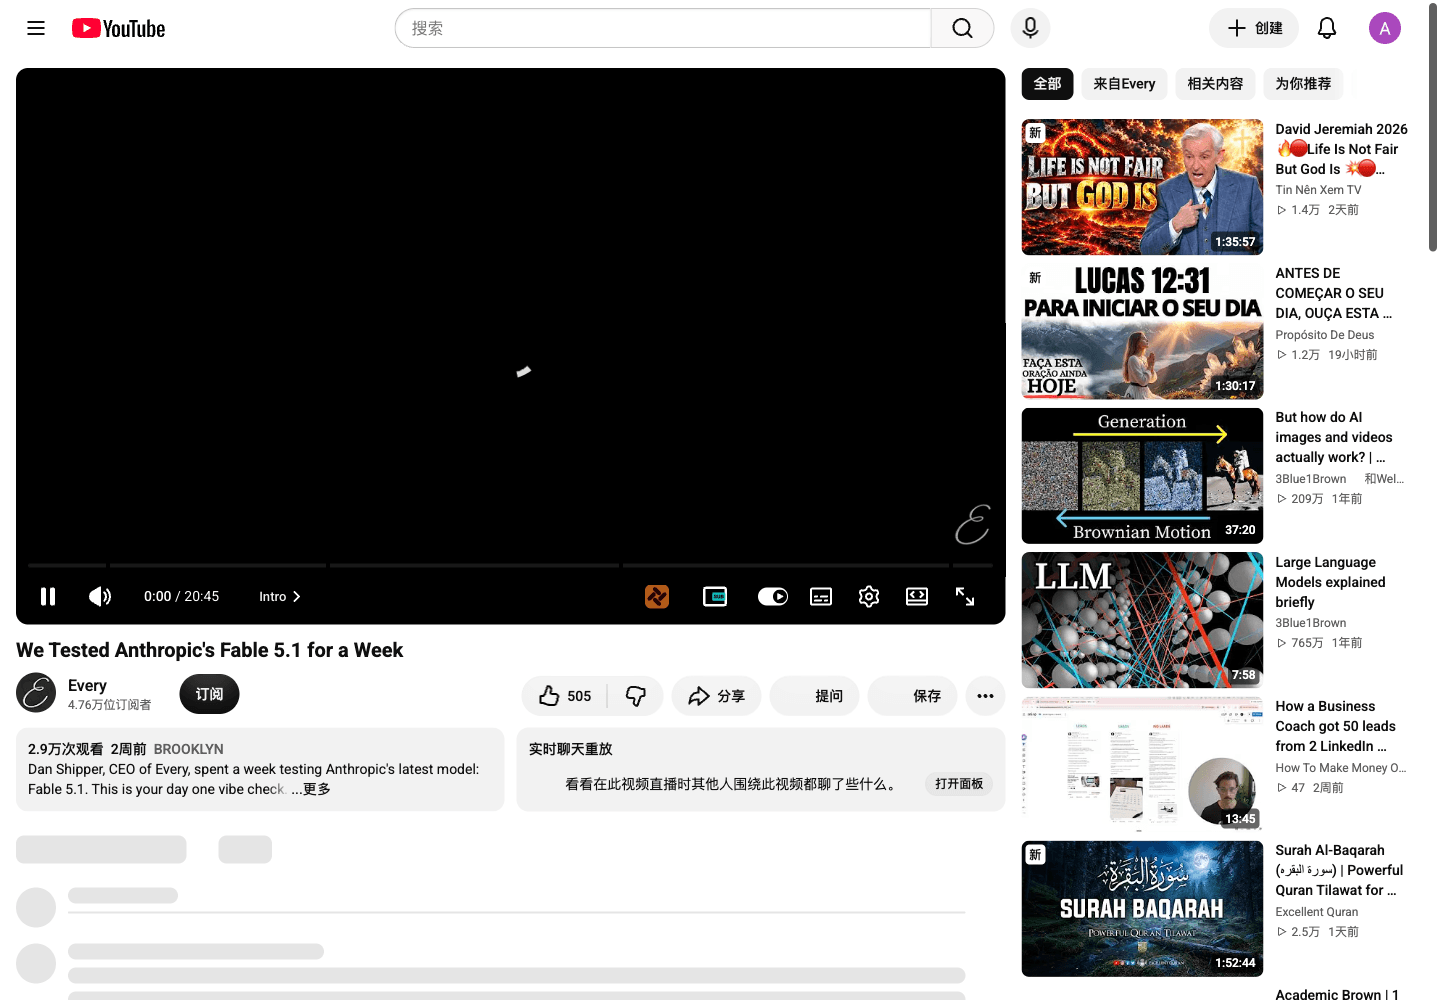
The balance: quota is not money but behaves like it. On subscriptions, Fable burns five-hour windows fast — one r/ClaudeAI user reported 30% of a day's usage gone in one debugging session ("I ain't letting it spawn Opus 5 agents"), and commenters on Every's week-long video reported exhausting a five-hour window in 10–20 minutes. Those are self-reported plan experiences, not benchmarks, but they point the same direction as the API math: delegation and effort decide the burn rate. Usage credits on paid plans let you keep working at standard API rates past the limits.
Plan availability: API, clouds, and consumer plans
The API rate card is only one of three economies. Checked on claude.com/pricing and the platform docs on September 22, 2026:
| Surface | Price (verified display) | Fable 5.1 access |
|---|---|---|
| Anthropic API | Token rates above | Yes — claude-fable-5-1 |
| Free plan | $0 | No (Sonnet/Haiku only) |
| Pro | $17/mo annual ($200 up front) or $20 monthly | Yes — usage credits, 50% of weekly limits |
| Max 5x / 20x | From $100/mo | Yes — same credits rule, 5x/20x Pro usage |
| Team Standard / Premium | $20 / $100 per seat monthly-billed ($25/$125) | Yes — Premium = 5x Standard |
| Enterprise | $20/seat/mo annual + usage at API rates | Yes, with spend controls |
| Clouds | AWS Bedrock, Google Cloud, Microsoft Foundry | Yes; regional endpoints +10%, Foundry meters in CCUs |
Subscription mechanics that decide real cost: usage resets on rolling five-hour session windows, with weekly limits stacked on top for paid plans; web, desktop, mobile and Claude Code draw from one pool; Pro is "at least 5x" Free per window, Max is 5x/20x Pro. Fable specifically draws down usage credits set at 50% of weekly limits on Pro and Max — a Fable hour costs twice a Sonnet hour against your allowance, which is the arithmetic behind the "burned my window" reports above.
Third-party routes carry their own conditions: OpenRouter's Fable page notes data retention is not waivable there, and its Bedrock endpoint is BYOK-only mid-migration. The defaults also differ by surface — High effort in Claude Code versus Medium on the web — so the same subscription draws down at different speeds depending on where you work.
Two worked budgets, with every assumption visible
Standard rates, no retries, no tools, no taxes. Worked arithmetic, not predictions.
A short question with a long think. 10,000 input tokens, 2,000 output:
(10,000 × $10 + 2,000 × $50) / 1,000,000 = $0.20A cold agent loop over a large repo. 300,000 input tokens (still standard rate — no long-context tier), 8,000 output:
(300,000 × $10 + 8,000 × $50) / 1,000,000 = $3.40The warm version of the same loop. Same 300,000-token context, 90% cached, one 1-hour write per session, 8,000 output:
(270,000 × $0.25 + 30,000 × $10 + 300,000 × $20 + 8,000 × $50) / 1,000,000 = $0.97 + writesThat third line is the whole story of this release in one calculation: the same work drops from $3.40 to under a dollar when the prefix holds still — and climbs back the moment context churn, retries, or Opus-routed sub-agents reappear. The model resource and its prompt collection track repeatable tasks you can measure your own hit rate on.
Local calculation
Estimate Claude Fable 5.1 API token cost
Uses the official USD rates checked 2026-09-22. Values stay in this browser.
Cache hits bill at $0.25 per million tokens — the 0.025x Fable exception. This estimate excludes retries, tool overheads, safeguard reroutes, and provider markups. The US-only multiplier applies to every line. Verify current rates
The calculator runs entirely in this page — nothing is sent anywhere. It prices both cache-write durations, the Batch and US-only modes, and validates inputs locally. What it deliberately does not model: retries, sub-agent tier routing, tool overheads, and safeguard reroutes — those belong in your margin. Recheck the official rate card before committing a budget; these are the September 22, 2026 numbers.
A practical option: run the comparison in Tabbit
After the budget comes the boring part: actually running Fable-shaped work needs a place where pages, files, and model calls sit together, and where "try Fable at medium, fall back to Sonnet" is a selection instead of an orchestration project. That is the gap Tabbit Browser occupies — an agentic AI browser whose model picker, live tabs, and local files share one surface.
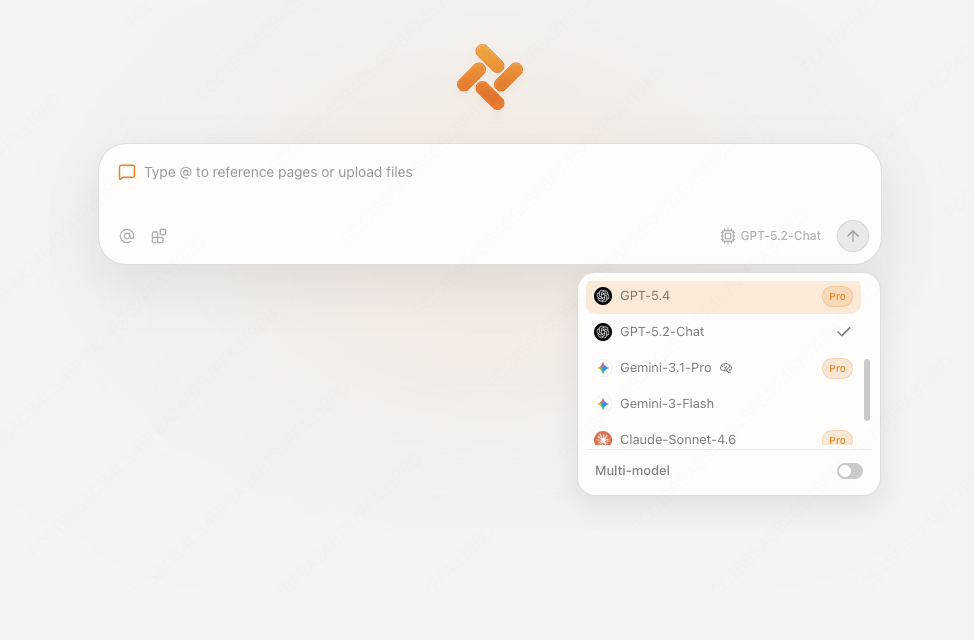
The boundaries, stated plainly: Tabbit is a client, not an Anthropic billing layer. Model availability depends on your account and edition, and nothing in the browser changes what Anthropic charges — the rate card above applies wherever Fable runs. This article did not run a Fable task inside Tabbit, so no availability or performance claim is made here. What the browser changes is setup cost: measuring your own cache-hit rate and effort threshold on real work — the two numbers this entire page says decide your bill — before writing any orchestration code is cheapest in a workspace built for exactly that. The Tabbit working-habits guide covers the method; the AI browser overview is the general starting point.
 Tabbit Browser
Claude Fable 5.1 pricing decision table
| Your workload | Cost driver | Best starting path | Watch out for |
|---|---|---|---|
| Long agent loops, stable repo/docs context | Cache reads | Standard tier, prefix-stable prompts, 1h writes | Context churn turns reads into 1.25–2x writes |
| Short chat, quick edits | Output tokens | Lower effort — or Sonnet 5 | $50/M output dominates; Fable is overkill |
| Overnight evaluation, batch refactors | Volume | Batch API at 50% | Interactive/managed-agent sessions don't qualify |
| Open-ended autonomous builds | Delegation + output | Cap sub-agent tiers; prefer Fable writing its own code | Opus-routed sub-agents billed at Opus rates |
| Compliance-required US processing | Every line | US-only at 1.1x, Batch where allowed | Premium applies to cache reads too |
| Subscription-based daily use | 5h windows + credits | Pro/Max with credits at 50% of weekly limits | High-effort defaults burn windows in minutes |
Final verdict
Claude Fable 5.1 is priced like an ingredient for long-horizon work, and the release genuinely moved one number: cache reads at $0.25 per million make cached-context agent loops dramatically cheaper than on Fable 5 — independent measurements put realized savings at 15–30%, and your mileage is decided by hit rate, not by the sticker. Buy it for exactly that shape of work, at the lowest effort that passes your acceptance check, with delegation tiers capped and Batch carrying everything that can wait. For short interactive tasks, strict budgets, or churning contexts, the family ladder exists precisely so the flagship is a routing decision, not a default — and on subscriptions, treat the five-hour window as the real invoice.
Recheck the official pricing page monthly: Sonnet 5's standardization shows this ladder moves. The overview and review carry the capability story; the community records linked above carry the workload evidence; and the cross-family pricing comparison shows what the same list price costs elsewhere.
Sources
Anthropic pricing docs — rate card, caching multipliers, Batch, residency, tool pricing; checked September 22, 2026
Anthropic launch page and Claude Fable product page — savings claims, defaults, reroute billing, availability; checked September 22, 2026
claude.com/pricing — Free/Pro/Max/Team/Enterprise plans and Fable access rules; checked September 22, 2026
Artificial Analysis release page — effort-tier intelligence, speed, cost-per-task snapshot; checked September 22, 2026
Firecrawl: 57-run cost measurement — token ratios, realized savings, task-spec effects; September 7, 2026
OpenRouter Fable 5.1 — provider rates and route conditions; checked September 22, 2026
Community records with screenshots and conditions inline: r/ClaudeCode $1,200 vs $500, r/ClaudeCode 37% savings, r/LLMDevs same-price analysis, r/ClaudeAI quota burn, Every's week-long test comments

FAQ
How much does Claude Fable 5.1 cost?
On the Anthropic API, Claude Fable 5.1 is $10 per million input tokens and $50 per million output tokens, checked on Anthropic's pricing docs on September 22, 2026. Prompt-cache writes cost $12.50 per million (5-minute) or $20 per million (1-hour), and cache reads cost $0.25 per million. The Batch API halves everything to $5/$25, and US-only inference adds a 1.1x multiplier to every line.
Is Claude Fable 5.1 cheaper than Fable 5?
It depends on which token dominates your bill. Anthropic estimates typical workloads cost about 25% less and highly agentic workloads up to about 45% less, entirely from the cache read cut to $0.25 per million. But Artificial Analysis measured its cost per benchmark task rising 18% because Fable 5.1 emits more reasoning tokens. Workloads that re-read a stable cached context get cheaper; workloads that generate fresh output or churn context can get more expensive.
Is Claude Fable 5.1 available on the Free plan?
No. Anthropic's plan comparison marks Fable as unavailable on Free. It is available to Pro, Max, Team, and Enterprise users; on Pro and Max, Fable usage draws on usage credits set at 50% of weekly limits. Free-plan users get Sonnet and Haiku models only.
What is the cheapest way to run Claude Fable 5.1?
Stack the levers in order: keep prompts prefix-stable so reads bill at $0.25 instead of $10 per million, run at the lowest effort level that passes your acceptance check, route non-urgent work through the Batch API at 50% off, and skip US-only inference unless compliance requires it. Also cap delegation: sub-agents routed to Opus 5 bill at Opus rates and are a common hidden cost line.
Does Claude Fable 5.1 charge extra for long context?
No. Anthropic bills the full 1M-token context window at standard per-token rates, with no long-context tier or threshold repricing; prompt caching and Batch discounts apply across the whole window. This differs from flagships like GPT-6 Astra, where prompts above 272K input tokens reprice the entire request at higher long-context rates.
Do safeguard reroutes or failed tool calls bill at Fable prices?
No. Anthropic states that queries automatically rerouted by cybersecurity or biology safeguards are not charged at Fable prices; they are completed by Opus 4.8 or Opus 5 instead. Failed web searches are not billed, web fetch has no extra charge, and code execution is free when used alongside search or fetch tools.